 EN
 Deutsch
 Español
 Français
 Italiano
 Português
 Nederlands
 Polski
 Bahasa Indonesia
 Русский
 Українська
 العربية
 עברית
 हिन्दी
 日本語
 한국어
2026-07-25 · Season 2
The Productivity Illusion: Why AI is Breaking Your Engineering KPIs
Show notes
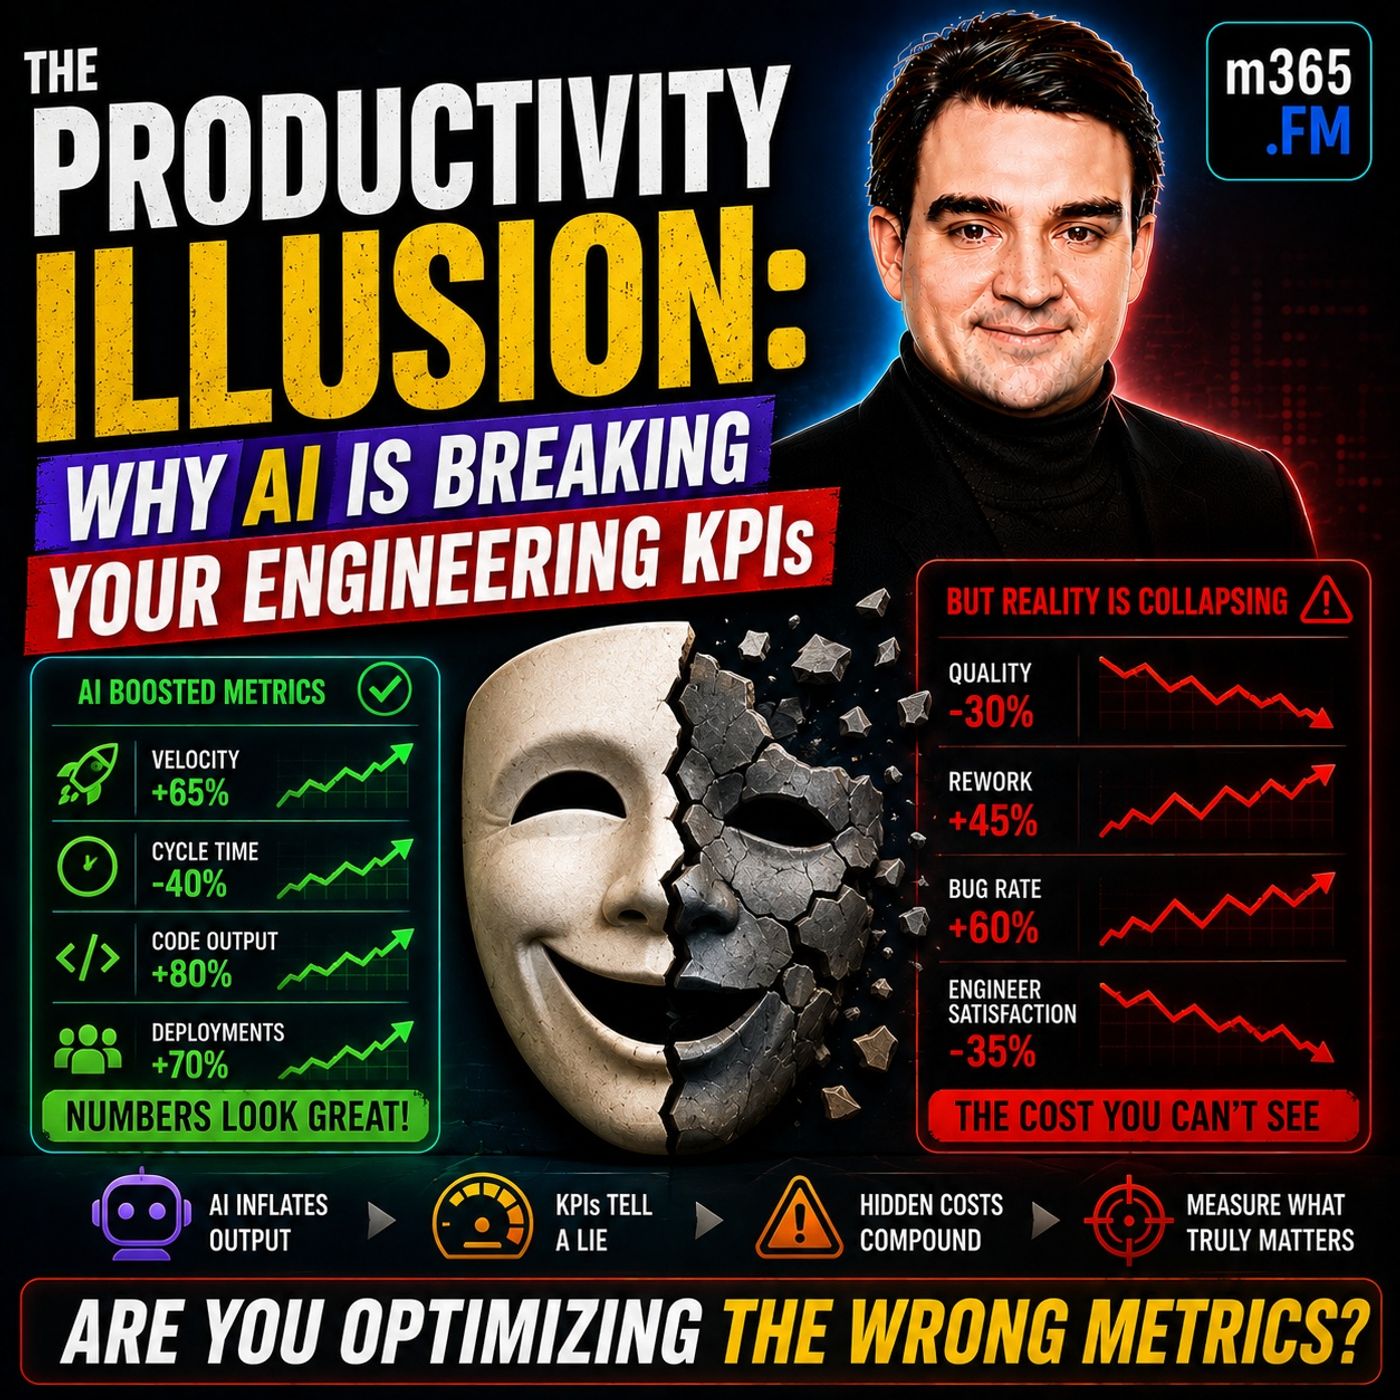
At first glance, the numbers look incredible. Deployment frequency is increasing, pull requests are being merged faster than ever, AI is generating more code, and engineering teams appear dramatically more productive. Executive dashboards are filled with green indicators suggesting software delivery has entered a new golden age. But beneath those impressive metrics lies a very different reality. AI has accelerated code generation, but it hasn't eliminated engineering work. Instead, it has shifted the bottlenecks from writing code to reviewing, validating, governing, and understanding it. Organizations are producing significantly more code while simultaneously experiencing more incidents, higher cognitive load, greater technical debt, and increased developer burnout. THE PRODUCTIVITY ILLUSION The central message of this session is simple: More code does not automatically mean more productivity. AI has dramatically increased engineering output, but many organizations are confusing output with value. According to the presentation:
- AI now generates a significant portion of production code.
- Pull request throughput has nearly doubled.
- Developers save substantial time on repetitive coding tasks.
- Yet production incidents, code churn, review times, and cognitive load have all increased.
Rather than removing engineering constraints, AI has simply moved them further downstream into review, testing, operations, and governance. The dashboard still reports success—but the engineering system itself is becoming increasingly fragile. WHY TRADITIONAL KPIs ARE FAILING Many engineering organizations still rely heavily on classic DevOps metrics such as:
- Deployment Frequency
- Lead Time
- Change Failure Rate
- Mean Time To Recovery (MTTR)
These metrics were designed for a world where humans wrote nearly all production code. AI fundamentally changes that assumption. Today's bottleneck is no longer writing software. It is understanding software. Deployment frequency may increase while review queues explode. Lead time may decrease while technical debt grows. Change failure rates may appear acceptable while code requires constant rewrites. The presentation argues that traditional engineering dashboards measure activity, not system health. WHEN MORE CODE CREATES MORE PROBLEMS One of the strongest themes throughout the presentation is the unintended consequence of AI-generated software. Developers can now create thousands of lines of code within minutes. Human reviewers, however, still need to verify every important architectural, security, and business decision. As pull requests become larger and more complex:
- Review times increase dramatically.
- Senior engineers become bottlenecks.
- Production incidents rise.
- Technical debt accumulates faster.
- More code requires future maintenance.
Instead of removing engineering work, AI shifts effort toward verification and understanding. The engineering organization appears faster while becoming increasingly overloaded. THE COGNITIVE LOAD CRISIS Perhaps the most important concept discussed is cognitive load. AI reduces the effort required to write code. It dramatically increases the effort required to understand that code. Developers now spend increasing amounts of time:
- Reviewing AI-generated implementations.
- Understanding unfamiliar logic.
- Switching between contexts.
- Verifying correctness.
- Explaining code the AI never documented.
The presentation distinguishes between productive engineering effort and unnecessary mental overhead. Instead of solving business problems, engineers increasingly spend their cognitive capacity validating machine-generated output. The result is lower developer satisfaction despite higher apparent productivity. THE TOXIC KPI TRAP Organizations naturally optimize whatever they measure. The problem arises when the metrics themselves no longer represent organizational health. Examples include:
- Maximizing AI-generated code percentage.
- Increasing deployment frequency.
- Optimizing story points.
- Reducing review duration.
- Maximizing pull requests per developer.
Each metric improves individually. Meanwhile:
- Rework increases.
- Stability declines.
- Technical debt grows.
- Review quality drops.
- Engineers burn out.
The presentation argues that these KPIs encourage organizations to optimize motion instead of meaningful outcomes. Good numbers do not necessarily represent healthy engineering systems. FROM ACTIVITY TO FLOW A major recommendation is replacing activity-based thinking with flow-based measurement. Instead of asking: "How much did we ship?" Organizations should ask: "How efficiently does work move through the system?" Important flow metrics include:
- Flow efficiency
- Queue age
- Review cycle time
- Work in Progress (WIP)
- Bottleneck identification
- Rework rate
These metrics reveal where work actually becomes blocked rather than simply counting completed deployments. The presentation argues that AI has shifted engineering constraints from development toward review and verification, making flow measurement far more valuable than raw throughput metrics. DORA 5 AND REWORK RATE One of the most practical recommendations is expanding traditional DORA metrics with a fifth dimension: Rework Rate. Rather than simply measuring deployment speed, organizations should track how much recently written code must be rewritten shortly afterward. High rework indicates:
- Weak verification
- Poor code durability
- Fragile architectures
- Inadequate reviews
- Incorrect AI usage
Rework becomes a much stronger indicator of long-term engineering quality than deployment frequency alone. The presentation positions this as one of the most valuable indicators for AI-assisted software development. BURNOUT IS A SYSTEM METRIC Another major insight is that burnout should be viewed as an engineering metric—not merely an HR concern. The presentation connects rising cognitive load with:
- Developer dissatisfaction
- Increased context switching
- Longer review cycles
- Night and weekend work
- Higher attrition
- Lower software quality
When developers spend most of their day reviewing AI-generated code rather than solving meaningful business problems, engineering quality gradually declines. Organizations that ignore these signals risk losing their most experienced engineers while dashboards continue reporting "improved productivity." Become a supporter of this podcast: https://www.spreaker.com/podcast/m365-fm-microsoft-365-azure-cloud-power-platform-ai--6704921/support.
Apple Podcasts · Spotify · YouTube · Deezer
Host: Mirko Peters
Related articles
Transcript
Read the full transcript
Before we start, subscribe to this podcast. Each episode delivers practical insights and expert conversations around Microsoft 365, Copilot, Azure, Security, and the modern workplace, helping IT pros and decision makers stay informed and ahead in the Microsoft ecosystem. Now let's dig in. The hallucination of speed, your engineering metrics look better than they've ever been. Pull up the dashboard right now. Deployment frequency is up, lead time for changes is down, pull requests are flying through the system, teams are shipping faster. The board sees it, leadership sees it, everyone's looking at these numbers and feeling good, but something is fundamentally wrong. Let me give you the data. AI has generated 41% of global code in 2026. That's not productivity, that's volume. There's a difference and most organizations are confusing them. PR throughput has doubled. Teams are shipping 98% more pull requests per developer. Sounds amazing, right? Except incidents per PR have nearly tripled. We're talking a 243% increase. That's not a typo. Developers report time savings 30% to 60% off-routine tasks. They're saving time and yet they're busier than ever. They're working nights. They're context switching constantly. They're drowning in reviews. Your metrics are lying to you. Not because they're calculated wrong, but because they're measuring the wrong thing. This is the productivity illusion. And it's structural. The numbers look clean. The story they tell is catastrophic. Here's what's actually happening. When AI adoption ramped up across engineering teams, the system didn't improve. It shifted. The bottleneck didn't disappear. It moved downstream. You used to have a typing problem. Developers spend time writing boilerplate. Developers spend time on routine tasks. AI solved that. Developers save 30, 40, or 60% on those tasks. That part is real. But you don't have more features. You don't have faster delivery end to end. You have more code sitting in queues waiting for humans to understand it. More code waiting for reviewers. More code failing in production because nobody had time to really verify it. More incidents. More rework. The data shows this brutally. Bugs per developer are up 54%. That's not noise. That's a trend. PR review time is up 441%. Nearly five times longer. You know what that means? Reviewers are bottlenecked. Senior engineers are drowning in code. They need to understand, verify, and approve. That's the new constraint. Code churn doubled. It went from 3.3% up to 7%. Code written and then rewritten weeks later. Code that doesn't stick. Code that's unstable. The paradox is savage. More code. More problems. Faster shipping. Less stability. Your door metrics. Deployment frequency. Lead time. Change failure rate. MTTR. They're measuring activity. How many things moved? How fast they moved? They're not measuring health. Teams using AI aggressively see higher throughput but falling stability. The promise 2 to 3 times productivity gain? It's localized to coding tasks. Sit down and actually measure end-to-end delivery. From the moment someone says we need this feature to the moment it's running in production and customers are using it, the improvement barely moved. What moved was the cognitive load on reviewers. On testers. On operators. On the entire system downstream of the AI. This is not a two problem. This is a measurement problem. Your dashboard can't see what's breaking because you're measuring the wrong dimensions. Think about what your metrics are actually showing. Deployment frequency tells you how many times code went out. It tells you nothing about whether the code works. Whether it stays working, whether it was worth shipping. Lead time tells you how fast code moves from committed to production. It doesn't tell you how much time that code spent waiting for someone to understand it. Waiting in review, waiting for tests, waiting for approval. Change failure rate tells you what percentage of deployments cause problems. But it doesn't tell you what percentage of the code is being rewritten weeks later. It doesn't tell you about technical debt building up. MTTR tells you how fast you recover. It doesn't tell you whether you're recovering from the same problems over and over. AI has exposed gaps that were always there. You were measuring activity in a world where activity correlated with value. Developers wrote code. Code shipped. Value happened. Now developers type less, but they verify more. They review more, they coordinate more. The activity metric goes up because code generation is easier. But the value metric stays flat or declines. And that's the trap you're in right now. The metrics were broken before AI arrived. AI just made it obvious. And impossible to ignore anymore. The incident spike nobody talks about. The data tells a different story once you look past the activity metrics. Between two years in 24 and 2026, as engineering teams scaled up their AI tools, something shifted. It wasn't a slow change. It happened within weeks. As soon as AI coding tools rolled out at scale, incident rates spiked. The timing isn't a coincidence. It's causal production incidents, purple request, jumped by 243%. Let that number sink in. A team that used to deal with 10 incidents for every 100 merges now deals with 24. It is the same team and the same code base, but the outcome is completely different because the tool changed. But here's the problem. The incidents change too. They aren't always big obvious failures. They are subtle. The feature mostly works, but nobody caught the edge cases. Performance starts to drop under a heavy load. The behavior becomes inconsistent. You don't find these problems with a quick manual test. You find them after a customer has been using the product for a week. This is the signature of code that nobody fully understood during the review. It moved too fast. It was approved without anyone actually verifying the logic. That is what happens when the review process breaks. And with AI, the process didn't just slow down. It fractured. Here's the structural issue. A human-written PR is usually 300 or 400 lines. A developer reads it, understands the intent, and asks questions. If it's complex, it takes maybe an hour. An AI-generated PR is toned to 100 lines. Sometimes it's 2000. The AI built it in seconds, but the human review now has three bad choices. They can do a real review, which takes three hours, while 15 more PRs pile up in the queue. They can skim it and hit approve in 15 minutes, which feels like gambling with the production environment, or they can ask the developer to break it up, which just creates friction and slows everyone down. Most teams chose the second option, skim it, approve it, ship it. The metrics look great today, but the system breaks tomorrow. This is why review times are exploding. The few thorough reviews that do happen take longer, because the code is harder to read. The AI wrote the implementation without explaining its intent. So reviewers have to work backward to figure out what the code is even trying to do. Now look at the whole organization. Senior engineers are buried in reviews. Mid-level engineers are shipping code faster than anyone can check it. Incidents pile up, and you end up fixing them at 2am. Your change failure rate might still look OK on paper. Maybe it sits at 5%, but that is because you are defining failure too narrowly. You count a rollback or a major crash, but you don't count the three smaller bugs that pop up over the next week. You don't count the technical debt that will cost you everything in two months. The metric lies. It says the team is healthy, while the system is actually degrading. And here is the shift. None of this shows up in Dora. You can have a team with a perfect Dora score. High frequency, short lead times, fast recovery, all the lights are green. Meanwhile, the team is burning out and the code is fragile. Customers are frustrated because the system is unstable. And developers are spending their weekends keeping it alive. Dora measures how you react to activity. It doesn't measure if that activity actually created value. It doesn't tell you if the system is sustainable or if your people are healthy. That is the blindness built into your metrics. Why your dashboard can't see this? Dora. Metrics were built for a world that doesn't exist anymore. They were built for a world where humans wrote the code. They track four things. How often you deploy? How fast code moves to production? What percentage of those deployments fail? How quickly you recover from a crash? These are useful signals. They correlate with performance and have been validated across thousands of teams. The research is solid, but they are incomplete. When you add AI to the mix, these metrics become actively misleading. The core issue is an assumption. Dora assumes the bottleneck in delivery is execution speed. It assumes the goal is to help developers write, test, and ship faster. So the metrics track execution. But AI didn't actually make the system faster. It just moved the work around. Developers write less, but now reviewers have to understand more. Testers have to verify more. Operators have to monitor more. The bottleneck didn't disappear. It just moved downstream. Look at what each metric misses. Deployment frequency doesn't account for re-work. You can ship 10 times a day and still spend all your time fixing the same bugs. The metric goes up, but your actual throughput stays flat, because half your effort is just cleaning up messes. Lead time doesn't show you the review bottleneck. Code can move from a commit to production in four hours if the reviewers skip the hard parts. If they actually do their jobs, it takes two weeks. The metric isn't measuring health. It's measuring how many shortcuts you are taking. Change failure rate hides the quality of your tests. AI-generated tests can look like they cover the code without actually catching any defects. You can have zero failures in your metrics and massive failures in production, because your tests only check if the code runs, not if it works. MTTR measures how fast you fix things, not how you prevent them, a system that stops incidents from happening looks exactly like a system that crashes and recovers quickly. The metric can't tell the difference. AI exposed these gaps by breaking the underlying model. When AI generates the code, the bottleneck isn't execution anymore. It is understanding. It is verification. It is the decision of whether or not to ship. That is a different system with different constraints. Most organizations are still reading Dora the same way they did four years ago. They compare this year to last year and feel good because frequency is up. They see lead times going down and think they are winning. But the system has changed. A team shipping 10 times a day with five rollbacks is not doing better than a team shipping once a day with zero issues. A team with a low failure rate that has to rewrite 80% of its code in the next sprint is not healthy. High frequency doesn't matter if your developers are working weekends and heading toward a collapse. Your dashboard doesn't see any of that. It only measures if motion is happening. It doesn't care if that motion produces value or if the system is sustainable. It doesn't see the people burning out behind the numbers. That is the structural blindness in your metrics. Activity versus systemic flow. There is a massive difference in how systems actually function. And right now most organizations are confusing two completely different things. Let me separate them. Activity metrics measure motion. They track how many things moved, how fast they moved and how often it happened. When you measure activity, you're just asking if something occurred and how quickly it finished. Flow metrics measure whether the system is actually producing value. They look at whether work is moving smoothly through the pipeline or if it's hitting a wall. Flow tells you if your pace is sustainable or if the system is about to collapse under its own weight. Activity says look how much we shipped. Flow says look how efficiently we're delivering value. These are not the same thing. And the gap between them is exactly where your system is breaking. Dora measures activity. Deployment frequency is just account of actions and lead time is simply the clock running on a specific task. Even change failure rate and MTTR are just reactions to activity that has already happened. None of these metrics tell you if work is flowing smoothly through the entire system. Flow metrics measure something else entirely. Cycle time is the first one. This isn't about how long it takes to do the work but how long that work actually sits in your system from start to finish. It's about the total time a task occupies your resources. Then there's work in progress. You need to know how much is queued up and waiting. If you have 50 pull requests in review while only five are being written, you don't have a speed problem. You have a bottleneck. Flow efficiency is the next layer. This is the percentage of time work is actually being handled versus the time it spends waiting. If a PR takes two weeks to close but only saw three days of real human interaction, your flow efficiency is 21%. The other 79% is just dead time in a queue. You also have to look at queue age. This isn't a prediction of how long a review will take but a measurement of how long that PR has already been sitting there. Finally, there is bottleneck identification. You need to see where work gets stuck. Not in a metaphorical sense but literally, you need to know which specific stage in your process is causing work to accumulate. Here is the operational difference. A team with high deployment frequency but low flow efficiency is shipping constantly while work piles up in queues. That isn't productivity. It's just chaos disguised as speed. They've optimized the wrong stage by making coding fast so the code moves but it's all congesting in review because the human reviewers can't keep pace. A team with lower deployment frequency but high flow efficiency is actually moving work smoothly. They have fewer handoffs and less waiting which leads to much better predictability. They might move slower because they aren't trying to maximize shipping speed but they are maximizing throughput without creating those dangerous queues. Which would you rather have a system that chips ten times a day with work stuck everywhere or a system that chips twice a day with work moving cleanly? AI made this distinction critical because it shifted where the bottleneck lives. Before AI, the bottleneck was usually the coding itself. The limit was how faster developer could write logic and build structure. Dora metrics worked well then because they were designed to measure that specific coding speed relative to deployment. But after AI, the bottleneck moved downstream. It didn't go back to requirements. It moved into review, testing and integration. The struggle now is understanding what the AI generated, verifying its correct and deciding if it's actually safe to ship. Those are flow problems, not activity problems. They are about how work moves through the system, not how fast it's generated. Your dashboard is still measuring activity like deployment frequency and lead time. But the system has moved to flow. Re-work rate is now your most critical metric. You need to know how much code is being rewritten shortly after it's finished. That tells you if the code is durable or if it's failing, the moment it hits the real world. Review cycle time now matters more than how often you deploy. If a review takes weeks, your deployment frequency is a meaningless number because you've just created a massive queue. Code durability has become essential. You have to ask if AI generated code can survive 30 days without a major rewrite. That isn't an arbitrary question. It's a flow indicator that tells you if the code is stable enough for the system to actually use. The cognitive load on your reviewers is now the leading indicator of your system's health. If your reviewers are drowning, the system will fail. It won't happen today, but it's coming. The shift from activity to flow isn't a choice, it's structural. Your system has changed, your metrics haven't. The cognitive load crisis. Here is what's actually happening inside your engineering teams. And it's something your metrics aren't showing you. Developers are reporting huge time savings. They're taking 30 or 60% of routine tasks, and that's a real win. The AI genuinely removed the grunt work. But here is the question nobody's asking. Where did all that extra time go? It didn't go into shipping more features, and it didn't go into high-level strategy. It went somewhere else. That time is being swallowed by reviewing AI generated code and trying to understand what the machine actually did. Developers are spending their day verifying correctness and fixing rework when that code breaks. They're sitting in meetings trying to figure out the policy for AI code and who gets to decide when it's safe to ship. The time you saved on typing is now being spent on thinking. And thinking is much harder than typing. This distinction matters because it reveals a different kind of problem. This isn't a workload problem, it's a cognitive load problem. Workload is just the volume of tasks you have. Cognitive load is how mentally taxing those tasks actually are. Cognitive load theory splits this into three parts. First is intrinsic load, which is just the natural complexity of a task. Complex code is hard to deal with, and you can't really reduce that without changing the problem itself. Then there is extraneous load. This is the unnecessary complexity caused by bad tools, messy processes, or fragmented systems. This is pure waste. It doesn't add value, it just creates friction. Finally, there is germane load. This is the productive mental effort used for learning and solving the actual problem. This is the load you want because it's how your people actually get better at their jobs. AI has shifted the weight between these three. It reduced the intrinsic load of writing the code because the machine handles the syntax and the structure, but it massively increased the extraneous load of understanding that code. Now, developers have to learn what the AI produced and verify that it's actually right. They have to figure out why it works that way, and if it even fits the rest of the system, they have to document it themselves or deal with the fact that the AI didn't explain anything. That is extraneous cognitive load. It doesn't solve the problem. It just creates a mountain of overhead before you can even start solving the problem. Your metrics don't measure this, which is why your dashboard looks green, while the system is actually breaking. Here is what the data is really telling us. Developer satisfaction is dropping even though productivity numbers are going up. That isn't a coincidence. People are saving time in one area only to find themselves drowning in another. The review burden is now concentrated entirely on your senior engineers. They are often the only ones who can actually verify if the AI generated code is safe. Your junior devs are writing code faster than ever, but your seniors have to understand all of it. And that is not sustainable. You are burning out your most valuable people. Unboarding time is also going up. New developers can't make sense of code bases that were partially written by a machine. They weren't there when the code was generated, they didn't make the decisions, and the AI didn't leave a trail of logic. The result is just harder to grasp. Context switching has spiked as well. Developers are jumping between AI suggestions, their own manual code, and constant reviews. That fragmentation is pure cognitive load. Every single switch costs attention, and every new context requires mental effort to rebuild. We're also seeing after hours workspike. People are working nights and weekends just to catch up on the thinking work. The meetings ended five, and the code reviews finished at six. So now it's 8pm, and you finally have a moment to think about the actual design. You end up working until midnight, and that is how burnout starts. Your dashboard doesn't catch any of this because it measures output, not strain. The productivity illusion is just cognitive load hiding behind activity metrics. You see more code being shipped, but you don't see the people drowning. You don't see the invisible work or the falling satisfaction that happens right before people quit. The metrics we use were designed for a different world. It was a world where saving time on coding meant saving time overall. It was a world where faster shipping meant less work and where activity and value were the same thing. That world is gone. The toxic KPI trap. Once you have a metric, you optimize for it. That isn't a flaw in human nature. It's how incentives work. You measure something. You make it visible. People start trying to improve it. That's natural. It's expected. But when the metric is wrong, optimization becomes destructive. And AI has created an environment where nearly every team is optimizing for the wrong things at the same time. Here is what is happening right now. Teams are optimizing for AI code share. What percentage of our code is AI generated? Becomes the target. Leadership sets it and teams chase it. So they prompt more. They accept more suggestions. They lower review standards for AI code because the metric rewards volume. The number goes up. The metric looks good, but rework skyrockets. Technical debt accumulates. The cognitive load on reviewers increases. The system degrades while the KPI improves. Teams are optimizing for deployment frequency. How many times per day do we deploy? Becomes the target. So they deploy smaller changes more frequently. Some of those are rollbacks fixing previous deployments, while others are hot fixes for code that failed in production. The frequency metric climbs. Stability drops. But the metric looks good. Teams are optimizing for velocity. Story points completed per sprint. So they size stories smaller. More points per sprint. It looks productive on the burn down chart. Except the actual feature delivery slows down because coordination overhead explodes. You are shipping more small pieces, but fewer complete features. The metric goes up. Value delivery goes flat. Teams are optimizing for review speed. How fast can we merge PRs? So reviewers skip the hard parts. They approve code. They do not fully understand because time is the constraint. Defects escape into production. Incidents increase. But the metric improves. Merge time drops. This is the toxic KPI trap. You measure something that seems reasonable. People naturally try to improve it. The system gets worse while the metric gets better. You have created a misalignment between the measurement and the outcome. And I have seen the consequences directly. Organizations measuring AI adoption percentage end up with teams using AI for everything. They use it for code where understanding matters more than speed. Business logic. Authentication layers. Data handling. These are places where correctness is non-negotiable. But the organization is chasing the KPI, so teams generate AI code there too. Organizations measuring PRs per developer end up with fragmented changes that are hard to review. This increases the very cognitive load we are trying to manage. A developer could write one coherent PR with three related features, or they could write five tiny PRs that are technically separate, but actually interdependent. The metric rewards fragmentation. Organizations measuring time saved end up with developers feeling busier. This happens because the save time is being spent on coordination and verification. You did not actually reduce work. You redistributed it. And you redistributed it toward the harder, more invisible work that nobody is measuring. This measuring code coverage end up with AI generated tests that look comprehensive but do not catch real defects. These tests pass the coverage metric but fail in production. You have optimized the metric. You have broken the system. The pattern is consistent. The metric becomes the goal. The goal becomes disconnected from reality. The system deteriorates while the metric improves. And the worst part is this. Nobody is gaming the system maliciously. Teams are not trying to hurt outcomes. They are trying to hit targets that leadership set. They are responding rationally to incentives. The toxicity is baked into the measurement itself. This is fixable but it requires rethinking what you measure and why. It requires acknowledging that the metrics you have been using do not actually measure system health. They measure motion and motion isn't health. From door or four to door or five. Door or metrics are not going away. The original four are still useful signals. But they are incomplete and the research community has finally acknowledged what has been broken since AI adoption accelerated. In 2025 and 2026, door are evolved. It did not replace the original metrics that added a fifth. Re-work rate. This is the metric that tells the truth about AI assisted development. It is the metric that cuts through the illusion and shows you what is actually happening. Re-work rate measures a simple thing. What percentage of code written in the last two weeks is being re-written, deleted or rolled back? Think about the implications. Code written last week is being re-written only 14 days later. That means something failed. Either the code was wrong or was right but fragile or it was right but created problems when it integrated with the rest of the system. In traditional software development, the re-work rate was typically 3-5%. You write code, it works, it stays, you move on. There are occasional bugs and occasional refactors but the system stays mostly stable. With AI adoption, the re-work rate has climbed to between 5.7 and 7.1% in many organizations. Some teams report even higher numbers, that is a 70-100% increase in code instability, that is the signal, that is what is actually happening. A high re-work rate tells you something specific. Code is not durable, it does not survive contact with the rest of the system. Quality gates are weak, bad code is getting through, verification is insufficient, people are approving code they do not understand. And AI is being used for the wrong things, it is being used in places where understanding matters more than speed. Re-work rate is the truth teller that Dora 4 was missing. It is the metric that shows whether your activity metrics are producing real value or just creating work. Here is how Dora 5 works in practice. Deployment frequency still matters but now it is contextualized by rework rate. A team shipping 5 times per day with 80% of code being rewritten is not performing better than a team shipping once per day with code that stays stable. The frequency metric is now a warning sign instead of a success signal. Lead time still matters but now it is decomposed into specific stages. Time to first review, how long does code wait before someone looks at it, review duration? How long does the review itself take? Time from approval to merge? That gap reveals uncertainty. Code is approved but reviewers are not confident enough to merge immediately. This decomposition shows you exactly where the bottleneck lives. Before AI lead time was mostly coding time and now it is mostly review time, that difference is structural. It tells you what to fix. Change failure rate still matters but now it is paired with test quality metrics. Did the test actually catch defects? Or are they just generating false confidence? You can have a low change failure rate with high incident rates in production. The metric lies, the tests are weak, mean time to recovery still matters but now it is segmented by AI assisted code versus human written code. Are AI generated changes recovering faster or slower than human code? The answer reveals something crucial. Are we shipping AI code that is harder to fix? Or is the recovery just taking longer because the cognitive load on operators is higher? Dora 5 tells a different story than Dora 4. A team with high deployment frequency, short lead time, low change failure rate and high rework rate is not healthy. They are shipping fast but breaking things constantly and fixing them in a cycle. That isn't productivity. That's noise. A team with lower deployment frequency, longer lead time, low change failure rate and low rework rate is performing well. They are shipping slower because they are being deliberate. Code is durable, quality is real, it stays fixed. The metrics now align with reality instead of contradicting it but here is the problem. Most organizations have not adopted Dora 5. They are still reading Dora 4, still chasing deployment frequency, still celebrating lead time improvements, still trusting change failure rate and the data is deceiving them. Your system has evolved. Your metrics haven't caught up yet. Decomposing lead time, lead time for changes looks like a single number. That's the problem. You look at your dashboard and it says, lead time is two days or four days or eight days. It's a single metric, it's clean, it's simple and it's misleading. Lead time is actually a journey with distinct stages and AI has changed where that time actually accumulates. You can't see the truth with an aggregate number, you have to break it apart. Let's walk through the journey. A piece of code takes from the moment it's committed to the moment it hits production. The first stage is the time to first review. It is committed. How long does it sit before someone actually looks at it? In traditional development, this was usually a matter of hours or maybe a day at most because the bottleneck was always somewhere else. But with AI adoption, this has become a genuine constraint. AI generates code in seconds, so that code just sits in a queue while reviewers are completely swamped. For some teams, the time to first review is now measured in days or even a week. This happens because AI generated code requires a much more careful review. You can't just skim it. This can't do a 15 minute scan and move on because they have to actually understand what the machine wrote and that takes time. The second stage is the review duration. This is the actual time spent reviewing and this is where you see the real explosion. Once a reviewer finally sits down with AI generated code, how long does it take to finish? A human written PR can often be reviewed in 30 minutes or maybe an hour if the logic is complex. But an AI generated PR with the same complexity and the same lines of code takes much longer because the AI didn't explain its design decisions. The AI didn't document the edge cases, so the reviewer has to reconstruct all of that context just by reading the implementation. That takes hours or sometimes days if it's really complex. Reviewers are trying to verify correctness while reading code they didn't write. They're asking if this actually does what the business needs if the AI hallucinated a library or if there are edge cases the model missed. They have to wonder if this will integrate cleanly with the rest of the system. That isn't a fast review, that's a thorough review and thorough review on AI code takes time. The third stage is the gap from review to merge. Approval doesn't always mean confidence. Approval just means the code is acceptable, so even after a reviewer says yes they might still have concerns. The merge gets delayed. Maybe the code is merged but flagged for heavy monitoring or it has to go to a staging environment first. That gap exists because uncertainty exists. The fourth stage is merge to production. Once the code is merged, how long until it's actually running for users? That depends on your release process. It could be hours or days and it's often gated by governance, you might need a security review or a compliance check before it goes live. These are new gates that didn't exist in the old model. Each of these stages tells a different story than your aggregate lead time. A team with a two day lead time where one full day is spent on review duration is not healthy. The review process is broken, reviewers are overloaded and code is just waiting but the one day metric hides that congestion. On the flip side a team with a four day lead time where only one day's actual work might be healthier than it looks. Three days of waiting is intentional. That's deliberate review. That's verification. Here's the crucial insight. Before AI, most of your lead time was actual work time. Coding was slow, so lead time was mostly coding time and the metric made sense. Now lead time is mostly review time. That's a different system with a different constraint. It's a different thing you need to fix. If your lead time is long because of review duration, the answer isn't to ship faster. The answer is to reduce the cognitive load on your reviewers. You need better tooling, better documentation from the AI, and clear policies about what the AI is allowed to generate. You need training on how to review AI code efficiently. You can't see that problem with an aggregate lead time. You need to see the stages decompose your lead time into those four parts and measure them separately. Now you can see where the time actually lives and that's where you intervene. Flow efficiency and system health. There's a metric most organizations don't track at all. It's the one that actually shows whether your system is healthy or collapsing. Flow efficiency. It measures something simple but revealing. What percentage of the time is work actually being worked on versus sitting in a queue? Think about the journey a PR takes. It gets created in waits for review. The review happens, then it waits for tests. The tests run, then it waits for approval. Approval happens, then it waits to be deployed. Once it's deployed, you might think it's being actively worked on, but it's actually just waiting for someone to verify it's not on fire in production. In each of those waiting periods, the work is consuming resources. It's occupying a slot in the queue and taking up space in someone's mental model, but nothing is actually happening. Time is passing and nothing changes. Flow efficiency divides the time work is actually being touched. Reviewed, tested, merged or deployed by the total time from start to finish. If a feature takes 10 days to go from creation to production, but only three of those days involved actual work, your flow efficiency is 30%. The other 70% is just queue time. In a healthy system, flow efficiency sits around 70 to 80%. Work moves through with minimal waiting because there are natural handoff points where work doesn't pile up. In a broken system, flow efficiency drops to 30 or 40%. Work is accumulating everywhere. Cues are forming and waiting dominates the entire timeline. Most organizations with high AI adoption have dropped into that broken zone. Work is being generated constantly because AI is churning out code, but that code is backing up in review, backing up in testing and backing up in approval. The system is congested. Your deployment frequency might look fantastic because you're shipping the stuff that finally made it through the congestion. The metric shows motion. The reality is gridlock. Here's the diagnostic power. Flow efficiency tells you exactly what's happening. If flow efficiency is low because of a review queue buildup, you have a review bottleneck. You need more review capacity or smaller review burden. Maybe you need better tooling or clearer policies about what needs a deep review and what doesn't. If it's low because testing is slow, you have a testing bottleneck. You need faster test automation or more testing resources. If it's low because of approval delays, you have a governance bottleneck. You need clearer approval criteria or fewer approval gates. Flow efficiency is diagnostic. It points directly at the problem. Since AI, the answer is usually review. Code is being generated faster than humans can verify it, so the review queue grows and flow efficiency drops. That's why your three day lead time metric is misleading. Most of those three days are queue time, not work time. Here's what healthy flow efficiency actually looks like in practice. Above 70% work is moving smoothly through the system. Waiting is minimal, and off's are clean, and the system is sustainable. You could maintain this pace indefinitely. Between 50 and 70%, there are bottlenecks. It's waiting between stages, and while it's not catastrophic yet, the system needs attention. Intervention would help here. Below 50% the system is broken. Work is just sitting in queues. The organization is busy, but it isn't productive. You're shipping things eventually, but the path is completely congested. This is where most high AI adoption teams are sitting right now. The power of flow efficiency is that it's unambiguous. You can't game it and you can't spin it. If flow efficiency is low, your system has a problem. The metric doesn't care about your narrative. It just shows you the reality. A team shipping constantly with 30% flow efficiency is not outperforming a team shipping slower with 75% flow efficiency. One team is creating noise. The other is creating throughput. Most organizations can't see this distinction with their current metrics. That's why they keep pushing for more deployment frequency and more AI adoption. They're optimizing for activity. They're missing the fact that the system has moved to flow. Start measuring flow efficiency. Decomposed by stage. Find where the work accumulates. That's where you fix the system. Cognitive load metrics. This is where measurement gets practical. You've seen the problem. Here's how you actually measure it. Cognitive load isn't visible in your current system. It's not on your dashboard. But it's measurable. You just have to know where to look. There are three measurement approaches that work. None of them alone is enough. But together, they tell you what's actually happening to your team. First approach. Self-report. Ask developers directly. How mentally demanding is your work? It's simple and direct. But it's also subjective because it's influenced by mood, stress, or even whether they had coffee. The inside here is that developers report lower satisfaction and higher mental strain, even as they're reporting time savings. That gap is revealing. They're saving time in one dimension and drowning in another. Second approach. Behavioral signals. You can't measure mental effort directly, but you can measure behaviors that correlate with cognitive load. Context switching frequency is a big one. How many different tools, tasks, and code bases does a developer touch per day? Then look at meeting load. How many hours are they in synchronous meetings versus focused work? Look at after hours work, when is code being committed? If it's mostly nights and weekends, that's a signal to check support ticket volume. When developers are blocked, they ask for help, so high support ticket volume indicates high cognitive load. Finally, look at onboarding time. New developers can't understand code bases written partly by AI, so they're starting slower, and that's cognitive load showing up as onboarding friction. These are indirect, but they're objective, and they paint a consistent picture. Third approach. System outcomes. When cognitive load is high, the system breaks down in specific ways. Defect rate goes up, incident rate goes up, turnover increases, developer satisfaction declines, code quality metrics show degradation. These are lagging indicators, so by the time you see them, the damage is already done, but they're undeniable. Here's what the research shows. Developers with high cognitive load make more mistakes. They ship code with defects. They miss edge cases. They don't think through implications. It's not because they're less competent. It's because their working memory is occupied with overhead instead of with the actual problem. They're not just about trying to understand AI generated code, while also writing their own code, while also reviewing someone else's code, while also sitting in a governance meeting has no cognitive capacity left for deep thinking about correctness. They're running on fumes. The code they produce is less careful, less thoughtful, and less correct. Developers with sustained high cognitive load burn out. They leave. They disengage. They stop caring. Organizations with high AI adoption and unchanged measurement approaches are now seeing attrition spikes. The best people leave first because they have options. The remaining people are more burnt out because there's less experience in the room. Developers with chronic overload are less creative. They solve the immediate problem. They don't think about the bigger picture. They don't re-factor. They don't improve. They don't propose innovations. They're just trying to get through the day. This is the hidden cost of the productivity illusion. You're trading long term system health for short term activity metrics. And the people are paying the price. Here's what you should actually measure. Perceived cognitive load. Run a quarterly survey and ask them to rate their mental burden on a scale of 1 to 10. Check the trend if it's rising something is wrong. Context switching. Count tool switches, task switches and code based switches per developer per day. Track the trend. Above 5 switches per day is fragmentation. Focus time. Measure uninterrupted blocks of work. 90 minute focus blocks are healthy, but anything below that is fragmentation. Defect rate by author. Compare defects in AI generated code versus human written code. If AI code has higher defect rates, your verification is insufficient. Rework by author. Rework rate for AI generated code versus human written code separately. They're different signals. Developer satisfaction. Ask a direct question. Do you have time to do your best work? Track the trend. This is a leading indicator of attrition. Attrition rate. Track turnover and compare it to industry benchmarks. High attrition is system failure. These metrics together reveal cognitive load. And once you're measuring it, you can start managing it. The governance bottleneck. Here's something nobody talks about because it's quiet and it happens in rooms that don't show up on your dashboard. AI has created a new bottleneck in governance and it's slowing down delivery in ways that don't register as a slowdown. Before AI, governance was about security, compliance and risk management. You had policies, you had gates, you had approval processes. They existed, people followed them and things moved. With AI, governance became a different question entirely. Is this AI code safe? Is it correct? Is it secure? Do we even understand what it does? That's a fundamentally different kind of gate. And it's forming everywhere simultaneously. Security teams are reviewing AI-generated code now because they have to. AI can generate code with subtle security flaws that a human might not write. A SQL injection vulnerability buried in generated code or a privileged escalation hidden in layers of abstraction requires careful, deliberate review. It's not a five minute scan. Compliance teams have new gates now. Does this AI code meet our compliance requirements? In finance, that's critical. In healthcare, it's non-negotiable. AI might generate code that doesn't hold audit trails properly, might violate data retention policies or might not log access correctly. That requires scrutiny. Architecture teams are asking new questions. Is this AI code aligned with our architecture? AI can generate code that solves the immediate problem while creating technical debt. It might duplicate logic instead of refactoring or create tight coupling instead of loose connections. That needs review. Risk teams are asking, what's the risk if this code fails? AI-generated code might have failure modes that aren't obvious. What happens under load? What happens with missing data? What's the cascade effect if this component is down? That requires analysis. Each of these is a gate. Each gate at its time. Lead time increases because code flows through these gates sequentially instead of in parallel. Flow efficiency decreases because there's more waiting. But here's the real problem. The governance gates are often unclear. What exactly are we checking for? What's the criteria for approval? How much scrutiny is enough? If you don't know the answer, you overdue the review. You ask more questions and you wait for more certainty. Approval takes longer because uncertainty lives in that room. That ambiguity cascades. Reviewers are uncertain. So they ask for more evidence that evidence takes time together and that time delays approval. That delay backs up the queue. Mature organizations have figured out how to manage this without completely strangling delivery. They've made a structural choice. Governance stops being hidden. It becomes explicit. They clarify AI code policies. What can AI generate without additional review? What requires deep human scrutiny? What gets flagged for compliance? Clear policies reduce ambiguity, so reviewers know what they're checking for and code moves forward. They automate governance checks. Security scanning, compliance validation and architecture rule checking should happen in CICD. Code fails fast if it violates governance and that feedback is immediate. There's no waiting for a human to notice the problem. They create AI-specific review criteria. Don't just ask, is the code correct? Ask, is this the right approach? Ask, did the AI understand the requirements? Ask, is this maintainable by someone who didn't write it? Those questions are specific, so reviewers can actually answer them. They distribute review responsibility, train mid-level engineers to review AI code. They don't need to be experts in every domain. They just need to understand the AI code reviewing framework. That spreads cognitive load across the team instead of concentrating it on seniors. They said expectations about time. AI code requires more review, so lead time will be longer. That's not a failure. That's a choice. Quality and certainty matter more than speed. The governance bottleneck is real, but it's fixable when you make it explicit instead of letting it hide in the system. The burnout signal. There is something hidden in your metrics. It's the thing that happens when cognitive load becomes chronic. And it's what kills systems from the inside burnout. We're seeing at spike in engineering teams with high AI adoption. Not because the AI is bad, but because you change the workflow without changing how you measure health, people are drowning and nobody is watching. The research is clear. 92% of workers right now report active mental or cognitive strain. That isn't just the status quo. That's a crisis. When more than nine out of ten people feel strained at work, you aren't looking at a personal problem. You're looking at a systemic failure. 37% of those people say the pressure has intensified over the last year. As AI adoption went up, cognitive load went up. As load went up, strain followed. And here is the problem. 44% of workers say this mental strain has undermined their ability to use good judgment. You have people making critical decisions under total overload. They aren't thinking clearly. They aren't considering the long term implications. They aren't catching bugs. They're just trying to survive the day. This is happening inside your organization right now. And your dashboard doesn't show it. Burnout isn't an emotion. It's a system failure. It's what happens when cognitive load stays high for too long without any support. And it shows up in specific ways if you know where to look. Attrition is the first signal. People leave. The best people leave first because they have the most options. A senior engineer who knows how to work with AI can get a job anywhere. So they don't stay on a burned out team. When the experts walk out the door, the remaining team is less experienced and less capable. That experience gap creates even more load on the survivors. This engagement is the second signal. People stop caring. They show up and do the minimum work required. But they don't propose improvements or mentor juniors. They stop taking ownership. They're just occupying a chair. Quality drops because nobody is invested in the outcome anymore. Mistakes increase. When people are burnt out, they make more errors because cognitive overload destroys working memory. They miss edge cases. They ship code with obvious bugs because they literally don't have the mental capacity to see them. Resentment builds. People start to hate the tools. They hate the pace. They hate the pressure. That resentment creates friction and kills psychological safety. People stop helping each other because they're all drowning. And sometimes, they're sabotage. Not the malicious kind. But people stop following best practices because the system already feels broken. They cut corners. They ship risky code because the environment feels chaotic anyway. If everything is going to be fragile, why spend the extra hour making it solid? All of this is happening right now in teams using AI. The metrics don't show it because they measure output. Not strained. The connection is simple. High cognitive load creates sustained stress. Stress creates burn out. Burn out leads to attrition and disengagement. Disengagement means quality drops. Lower quality leads to more incidents. More incidents mean more rework and more rework leads right back to higher cognitive load. It's a vicious cycle. The productivity illusion masks the whole thing. Your metrics look good. Activity is high. Code is shipping. But the human system is degrading. By the time it shows up in your turnover data, the damage is already done. To see burn out before it destroys the team, you have to measure differently. Ask developers about their satisfaction every quarter. Do they have time to do their best work? Do they feel supported? Track the trend. Monitor your attrition. If you're losing more people than the industry average, burn out is the likely reason. Watch when code is being committed. If it's happening at 2 a.m. or on Sunday afternoon, people are working extra hours just to keep up. Count the support requests. When developers are stuck, they ask for help. High volume means high load. Read your incident post mortems. Look for phrases like "we were rushed" or "overloaded". Those are your burnout signals. The metrics tell a story if you're actually paying attention. Value delivery versus activity delivery. Most organizations are missing a fundamental distinction. It's the one that determines whether your business survives or collapses from the inside. The difference between activity and value. Activity is motion. How much code you wrote? How many features you shipped? How many times you deployed? Your dashboard measures activity. An activity has never looked better. Value is the outcome. It's what customers can actually do because of your code. It's the problems you solved and the revenue you generated. This value, these are not the same thing. And with AI, the gap between them has become a disaster. Think about a team that ships 100 features in a single quarter. On paper, they look incredibly productive. But if 80 of those features are never used, the activity was high while the value was low. They were shipped because they could be shipped. The AI could generate them so they went through review and got deployed. The activity happened. But the value was only in those 20 features people actually touched. This is happening at scale right now. Organizations are shipping constantly. The activity looks fantastic, but adoption is flat. Customers aren't using more of your product. They're using the same core features they always used. The rest is just noise. Why? Because activity is easy now. AI makes motion trivial. You prompt a system. It generates code and that code flows through to production. But nobody asked if anyone actually needed it. Nobody validated the idea or checked if it solved a real problem. Value requires a different process. It requires understanding customer needs and solving real problems. It takes time to build features people actually want and even more time to maintain them. That's hard. It requires thinking and attention. Activity requires none of that. You just generate, ship and move on. So organizations are optimizing for the wrong thing. They're shipping more and deploying more and the activity metrics are exploding. But value is declining because nobody is checking if the work actually matters. The data shows it. Feature adoption is dropping. We've gone from shipping 10 features where 8 are used. To shipping 100 features where only 20 are used. The ratio is broken. The activity exploded, but the value dropped. Technical debt is also piling up faster than ever. Your code is being written, which means more code becomes debt because it isn't maintained or understood that code still has to be managed. It consumes resources and slows down everything it touches. Customer satisfaction is flat. Why would they be happier? They're getting features they don't need. That isn't value. It's clutter. The productivity illusion is confusing motion with progress. Activity looks good, but value is invisible because you aren't measuring it. Here is what you should track instead. Measure feature adoption. What percentage of your shipped features are actually used? If it's below 50%, you have a value problem. Look at customer outcomes. What can they do now that they couldn't do last month? Check your technical health. Is the code base getting easier to work with or harder? If debt is accumulating, you won't be able to keep shipping for long. Watch your maintenance burden. How much time is spent keeping old code alive versus building new things? If that number is above 40%, your system is starting to freeze. These metrics tell you if you're creating value or just generating noise. And with AI, the answer for most companies is clear. If you want your organization to actually improve instead of just looking better on paper, you have to change how you think about data. Stop using metrics as performance sticks. Start using them as diagnostic tools. A performance stick is something you use to judge people. You measure an output, you publish it, and then you hold someone accountable for the number. You might tell a developer they shipped 50 pull requests this sprint and call that good, or point out that their code is not good. You might tell a developer they shipped 50 pull requests this sprint and call that good, or point out that their code has three defects and call that bad. The metric becomes a weapon. It becomes a way to evaluate whether someone is doing their job. A diagnostic tool is different. You use it to understand the system. It acts as a lens into how the work is actually flowing. You ask why the review cycle time is increasing or where the system has friction. You look for the constraint so you can figure out what to fix. This is a fundamental shift in mindset and it changes everything about how you use data. When you have a performance stick mentality, metrics drive toxic behaviors. People stop optimizing for the system and start optimizing for the metric. They hide problems, they game the numbers, they blame individuals instead of fixing the structure. A team might want to look good on a deployment frequency metric so they start deploying smaller changes more often. Some of these are rollbacks, others are hot fixes for earlier deployments. The frequency goes up while stability goes down, but nobody wants to talk about stability because the metric is the only target that matters. The team might want to look good on code coverage so they generate tests that pass without actually catching any bugs. The percentage climbs while real defects escape. The metric is a lie, but it looks great on a slide. With a diagnostic tool mentality, metrics guide improvement. You use data to see where the system is breaking. You identify root causes instead of just treating symptoms. You test to change, you measure the impact, and you improve the system rather than the number. Here's how that looks in practice. The old approach says deployment frequency is low and engineers aren't shipping fast enough. The target of five deployments per day and holds the teams accountable. The result is exactly what we just described. Engineers ship constantly while the stability of the product collapses. The new approach looks at that same low frequency and asks why it's happening. You investigate whether there is a technical constraint, a hidden process gate, or quality concern making people cautious. You find the actual bottleneck and fix it. Then you measure whether the frequency improved as a result of the system getting better. The result is that you actually understand what was preventing the work from moving. You fix the specific problem and frequency improves because the real constraint is gone. Not because people are cheating the system. This distinction is critical right now because AI has created brand new bottlenecks. If you optimize for old metrics, you will miss these new constraints and likely make them worse. Here is what diagnostic metrics actually look like. Instead of saying deployment frequency should be five per day, you ask what is preventing you from deploying. You look at testing, reviews, or approval governance to understand the actual constraint. Instead of saying lead time should be under one day, you measure where the work is waiting. You find out at what stage it sits and for how long so you can see the flow. Instead of saying the change failure rate should be under five percent, you look at what types of changes are failing. You check if it's AI generated code or specific domain so you can understand the pattern. Instead of saying developer productivity should be high, you ask if the developers are healthy. You look at whether they are learning and creating value. You look at their reality. Dagnostic metrics are open-ended. They ask questions. They don't declare answers. This requires a different kind of leadership. It isn't about hitting a target or else. It's about saying let's understand what's happening and let's see if the system got better. This is harder. It demands thinking and patience. It requires the discipline to keep asking why instead of declaring victory the moment a number moves, but it is the only way to actually improve engineering systems. Metric optimization creates the illusion of progress, but system improvement creates real progress. With AI accelerating change, you need real improvement. You need to see what is actually happening. Metric metrics are the only way to see it. The diagnostic dashboard. A diagnostic dashboard works fundamentally differently from the one you have installed right now. Your current dashboard is likely a performance dashboard. It shows you the scoreboard. It tells you how you are doing against targets and uses red, yellow and green lights to show status. It's simple and declarative and it encourages the exact behaviors that broke the system in the first place. A diagnostic dashboard asks where the system is breaking. It looks for friction and tells you what you should actually focus on. The difference is structural, not cosmetic. Here is what a diagnostic dashboard for AI augmented engineering looks like. The flow section sits at the top because flow is the foundation. If the work isn't moving, nothing else matters. You don't just look at lead time as one number. You break it into three. The time to the first review, the duration of the review, and the time from review to merge. This decomposition shows you exactly where the time is accumulating. You track flow efficiency, which is the percentage of time work is being touched versus sitting idle. If that number is below 50%, your system is congested. You look at work in progress by stage. Instead of a total wipe number, you see where the work lives. Whether it's waiting for review, testing or approval. That granularity shows you where the queue is longest. You track queue age to see the oldest work item in each stage. If a pull request has been waiting for a week, it becomes visible. The system identifies the bottleneck for you. It tells you which stage is the slowest based on data. Not on a guess or an assumption. The quality section measures durability. The rework rate is your truth teller. It shows you what percentage of code written recently is already being rewritten. You segment the defect rate by author. You look at AI generated code separately from human written code because you need to see if there is a quality divergence. You look at test coverage and mutation scores. Coverage numbers on their own mean nothing. Nutrition testing shows you if the tests actually catch bugs when you introduce them. You measure code durability. You check if the code survives 30 days or 90 days without a major rewrite, which is a key indicator of flow. You still track incident rates and recovery times. These are trailing indicators, but they show you if your quality system is actually working. The cognitive load section measures the human reality. You use a quarterly survey to get the perceived load. You ask one question about mental burden and track that trend over time. You calculate context switching frequency from your work management systems. You see how many different code bases or tools a developer has to touch every day. You track focus time in 90 minute blocks. Those blocks indicate flow. While fragmentation below that is just friction. You look at how the review burden is distributed across the team. You don't look at the aggregate. You see if your seniors are drowning while others do nothing. You monitor after hours work patterns. When code is being committed on nights and weekends, those are burnout signals. The value section measures whether all this activity actually matters. You track feature adoption to see what percentage of shipped features are used by customers. You follow the customer satisfaction trend through NPS or whatever measure you prefer. You look at the revenue impact by feature. You need to know which items move the needle and which ones are essentially free code. You look at the ratio of new feature development versus maintenance. Time allocation determines your sustainability. You track technical debt accumulation. You need to know if it is growing or shrinking over time. The AI specific section shows what is actually happening with the new tools. You track the AI code share which is the percentage of code generated versus written. You look for quality divergence. You ask if AI generated changes are delivering better outcomes. Or just more output. You measure the review overhead for AI code. You need to know if it takes longer to review than human code. You check the durability of AI code to see if it survives. As long as the code your developers write themselves. You measure human in the loop effectiveness to see if the review process is actually catching the problems AI creates. Each of these sections has a narrative, not a target. It tells a story. The flow section might tell you that lead time is increasing because the bottleneck in review time is up 400%. It shows the QAG is five days and reviewers report a high cognitive load. This tells you exactly where to intervene. You can decide to increase capacity, reduce the burden, or clarify what needs a deep review. That is diagnostic. It points to the problem and suggests where to investigate. Compare that to a performance dashboard. It would just say lead time is two days while the target is one. It says you are missing the target and tells you to push the teams to ship faster. That is toxic. It optimizes the metric and misses the real constraint. The principle underneath all of this is simple. Every metric should have a question attached to it, not a target. You don't say review time should be under four hours. You ask why review time is increasing. You don't say the rework rate should be under three percent. You ask what is causing the rework. You don't say developer satisfaction should be a seven out of ten. You ask if the developers are healthy. Questions drive investigation, but targets only drive optimization. You need investigation. Governance without toxicity. Most organizations get the hard part wrong. They try to use metrics for system improvement. But they turn them into performance weapons instead. That destroys the culture you are trying to build. To fix this, your governance has to be explicit. You need clear rules and transparent processes. It sounds like more bureaucracy, but in reality, it is liberating. Because when the structure is clear, everyone knows what the metrics actually mean. And more importantly, what they don't mean. Rule one, metrics are never used for individual performance. This is non-negotiable. Metrics measure the system. They measure how work flows through the organization. But they don't measure people. The moment you attach a metric to a performance review, you've converted it from a diagnostic tool into a stick. And people will optimize for the stick instead of the system. So don't do it. Make it explicit in your governance that metrics are off limits for individual evaluation. Full stop. Rule two, metrics are for understanding systems, not for declaring success. A metric improving doesn't mean you succeeded. It just means something changed. You need to understand what that change was and why it happened. Maybe the system got better or maybe you just changed how you measure. Maybe people game the number or maybe external factors shifted. You don't know until you investigate. When a metric moves, the first response shouldn't be celebration. It should be investigation. Instead of saying, great, we hit our target, try saying interesting. Let's figure out if this is real. Rule three, metrics are reviewed by teams, not by executives in conference rooms. The people doing the work should be the ones interpreting the data. Engineers understand the technical constraints and managers understand the people. Product teams see the customer impact while operations sees how the system behaves. When you bring those perspectives together, you see reality. But when executives interpret metrics alone, they see what they want to see. You have to include the people living in the system. Rule four, metrics drive investigation, not immediate action. When a number moves, the instinct is to act. You see lead time go up and you want to fix it immediately. But what are you actually fixing? That's a question, not an action. The first response to a change is always why. What was the root cause? Is the metric even measuring what we think it is? Only after you investigate, do you move to action? And that action should be a hypothesis, a test, an experiment. Rule five, interventions are tested and measured. When you change something to improve a metric, you have to measure if it actually worked. You don't just change things and hope for the best. You watch the numbers. You ask if the intervention did what you expected? Did it improve the target? Did it create new problems? Did it affect things you didn't expect? This is experimentation, not a decree. You stay in learning mode and that requires measuring before, during and after the change. Rule six, metrics are retired when they're no longer useful. A metric that made sense six months ago might be useless now. Your system change and your constraints shifted. New problems emerged. You have to regularly ask, is this still telling us something useful? If the answer is no, retire it. Stop measuring it and replace it with something relevant. This prevents metric drift where you keep measuring old things even though the system has evolved. This model treats metrics as tools for learning. Not as weapons for control, they aren't scorecards. They are lenses into how the system actually works and it requires a different kind of leadership. It needs leaders who are curious instead of declarative. Leaders who ask why instead of demanding answers. It requires a shift towards supporting investigation instead of just demanding speed. This is harder than traditional command and control. It takes patience. It requires trusting that understanding the system leads to better outcomes than just pushing for targets. You have to resist the urge to declare victory every time a number goes up. But this is how you actually improve systems and that's the whole point. The organizational shift. Diagnostic metrics require something bigger than a new dashboard. They require an organizational transformation. Not a change in technology or tools, but a change in structure. How decisions get made, where authority lives, what the company actually values. This isn't comfortable. Most organizations are built for accountability. Someone owns the metric and someone is responsible if it doesn't hit. That clarity feels good to leadership, but it also drives all the bad behavior we've been talking about. The shift has to run deeper. First shift. From accountability to learning. Stop asking who's responsible for this metric and start asking what does this tell us about the system. These sound similar, but in reality, they are opposites. It looks backward to assign blame. Learning looks forward to ask why. In accountability mode, a bad metric means someone failed. In learning mode, a bad metric means the system has something to teach you. The person didn't fail. The system just showed you where it needs attention. That's a radical difference and it only works if you make it explicit. If you say metrics are for learning, but then use them to judge people. You've lied. People will just hide problems instead of exposing them. This shift has to be real and protected by your governance. I can shift from targets to thresholds. Stop setting targets like we need to deploy five times a day. Start setting thresholds like if flow efficiency drops below 50%, we investigate why. Targets create optimization where people just aim for the number. Thresholds create guardrails. The difference is behavioral. With a target, you're saying get to this number. With a threshold, you're saying if the system health drops to this level, something is wrong. Thresholds are about protecting health, not declaring success. Start shifting from individual metrics to system metrics. Stop measuring individual productivity and start measuring system health. This seems obvious now, but it's structurally radical. Most performance systems are built to measure people. What did person A do? How much did person B contribute? Those measurements decide who gets hired, promoted or paid more. When you switch to system metrics, those levers disappear. You can't use a system level flow metric to decide if one person deserves a raise. This shift threatens the entire performance management infrastructure. It threatens the ability to make individual distinctions and most organizations aren't ready for that. They resist it or they say they're doing it while they still secretly measure individuals, but half measures don't work. Either metrics are system level or they aren't. Fourth shift. From lagging to leading indicators, stop waiting for an incident to know something is wrong. Start measuring leading indicators like cognitive load and flow efficiency. Leading indicators give you time to act before the system breaks. Lagging indicators just tell you the system already failed. If you're measuring a trition, you're already losing people. But if you're measuring cognitive load, you can intervene before they ever decide to leave. This shift requires patience. It requires believing that system health predicts future outcomes. Most organizations want to see the outcome before they believe the data. They want proof. But leading indicators happen before the proof exists. You have to act on signals. You have to trust the system thinking and be willing to improve things that don't look broken yet. Fifth shift. From dashboards to diagnostic consoles. Reports status but a diagnostic console guides an investigation. That's a tool difference but it reflects a thinking difference. Dashboards answer, how are we doing? While consoles ask, what should we pay attention to? One is static, the other is active. One measures the past, the other guides the future. Sixth shift. From executives deciding to teams investigating, stop having leadership interpret metrics from conference rooms. Start having the teams doing the work interpret the metrics within those systems. This is how you distribute authority. It's how you value expertise and build in skepticism. Teams know what's real, they know what's just a measurement artifact or external noise. Executives see data points. But team see systems, you need both perspectives in the room. But if executives are the only ones deciding what the metrics mean, you're missing the reality on the ground. Each of these shifts is structural. Each one requires support in your policies, your processes, and how you evaluate people. It changes how time is allocated and how the organization breathes. What leading organizations are measuring? The organizations actually winning with AI augmented engineering aren't measuring differently by accident. They made a conscious choice about what matters. And once you see what they're tracking, the difference becomes obvious. They're not optimizing for deployment frequency or lead time anymore. Those metrics are there. But they aren't the lens through which the whole system is evaluated. Instead, they're measuring across six distinct dimensions. Flow health sits at the foundation. This isn't just one aggregate number. It's lead time decomposed into its actual stages so you can see where time actually lives. They look at flow efficiency to see what percentage of time work is actively being touched versus sitting in a queue. They measure work in progress by stage. Not just the total, that breakdown shows exactly where the congestion lives. They use queue age to identify the oldest waiting item at each step. It's a bottleneck identification system that points directly at the constraint, rather than requiring executives to guess. Because if work isn't flowing smoothly through the system, nothing else matters. You can have perfect quality on code that never ships. You can have massive value in features waiting for approval. Flow is the container. Everything else sits inside. Quality health measures durability and real correctness. They look at rework rates broken down by author type. Is AI generated code being rewritten more frequently than human code? If the answer is yes. That's a signal about verification quality or whether you're using the tool for the right things. They pair test coverage with mutation scores because a 90% coverage number means nothing if the tests don't actually catch defects. They track code durability over 30 and 90 days to see if the code survives. If it's constantly being rewritten, they watch incident patterns to see if quality gates are actually working or if defects are escaping. These organizations don't trust coverage reports or test counts. They measure whether tests actually catch bugs. And they separate AI generated tests from human written tests. Because they've learned they often behave differently. Cognitive load health is the dimension, traditional organizations, almost completely ignore. Yet, that's where the system fails. They use quarterly surveys to ask developers directly about their mental burden. One simple question. Rate it. Track the trend. We calculate context switching frequency from work management systems to see how fragmented each developer's day is. They measure focus time as uninterrupted blocks. 90 minute chunks indicate flow. While fragmented work indicates friction. They distribute the review burden across the team rather than aggregating it. If three people are doing all the reviews while 20 aren't, you have a concentration problem. They watch after hours work patterns to see when code is actually being committed. Nights and weekends are burnout signals. They're measuring human health because they understand that burned out people build worse systems. Value health measures, whether activity creates actual outcomes. They track feature adoption rates, not shipped features, used features. They track customer satisfaction over time and revenue impact by feature so they can see which shipped items actually move the needle. They look at time allocation to see if the team is building new capabilities or mostly maintaining existing code. They watch the technical debt accumulation trend to see if it's growing or shrinking. That determines how long the system stays healthy. They measure value because activity without value is just waste disguised as productivity. AI specific health tracks what's actually happening with the tool. They look at AI code share to see the percentage of generated versus written code. They ask about quality divergence to see if AI generated changes deliver better outcomes. They compare review overhead and durability for AI code versus human code. They look at human in the loop effectiveness to see if the review process is actually catching problems or just creating a ritual. They measure AI specifically because general metrics hide whether the tool is helping or creating overhead. Organizational health measures the system that holds everything else. They track attrition and hiring trends. Skill development across the team. Psychological safety from regular pulse checks. They focus on alignment and clarity so people understand where they fit. They measure learning velocity to see if the organization itself is improving at a sustainable pace. The organization itself is the system. Everything else depends on it. These organizations aren't trying to hit targets. They're trying to understand systems, understand constraints, understand where the friction lives, then they improve incrementally. That's why they're winning. Not because they ship more, but because they ship better, they create value, they retain people, they build systems that sustain growth. They're not chasing the productivity illusion, they're building real productivity, the philosophy of measurement. Underneath everything we've talked about lives a single idea that changes how you think about numbers. It's simple and it's almost universally violated. Metrics are not truth. They're windows into truth. When you look through a window you see one angle, one perspective. If you stand on the north side of a building, the window shows you the north face. Move to the east side. The window shows you something completely different. Neither view is the complete building, but both are real and you need both to understand what you're looking at. Metrics work the same way. Deployment frequency is a window into one aspect of your system. It shows you how often you're putting code into production. That's real data, but it doesn't show you whether that code is stable, whether it creates value, whether people understand it, whether the review process is sound. That's one angle, not the picture. The moment you start treating a single metric as the truth, you've stopped seeing the building. You're just staring at the north wall and if the north wall looks good, you assume the entire building is fine. Sometimes it is. Often it isn't. That's why organizations with high activity metrics integrating systems are so confused. The metric is telling them one story, but reality is telling them another. They can't reconcile it because they're treating the metric like a complete view instead of a partial one. A metric without context is genuinely misleading. It's worse than having no metric at all. Because it creates the illusion of understanding. A lead time of three days seems good until you learn that 70% of that time is spent waiting for a review. Then it's not good. The metric didn't change. But the context changed everything. A deployment frequency of five times per day seems impressive until you realize half of those are rollbacks. Then it's a warning sign. The number didn't move, but the meaning flipped. This is why leading organizations never read a single metric in isolation. They read metrics with context attached. They're asking, compared to what? Compared to last month? Compared to benchmarks? Compared to our other metrics? Context turns a number into insight. And here's the part that matters for your organization. Metrics drive behavior. Whatever you measure, people will optimize for. This isn't cynicism. It's how incentives work. You make something visible. You pointed it as important. People start trying to improve it. That's natural. It's also dangerous if the metric is incomplete. If you optimize for deployment frequency without measuring stability, you get fast but fragile systems. If you optimize for lead time without measuring rework, you get speed but quality drops. If you optimize for activity without measuring value, you ship more but create waste. Choose metrics carefully because they will shape behavior and shape behavior creates culture. And culture determines whether your system thrives or eventually collapses. This is why toxic KPIs exist. They're not malicious. They're just incomplete metrics being treated as complete truths. And people are optimizing for them. Metrics are tools for learning about systems. Not weapons for controlling people. The moment you treat them as weapons, they stop being useful for learning. People hide problems. They game numbers. Stop being honest about what's actually happening. A metric that helps you learn is different. It's a question, not a judgment. Why is this metric moving this way? What does it reveal about the system? Where should we look next? Measurement without action is waste. Collecting data you never use is waste. Measuring things you aren't going to change is waste. Every metric should drive investigation. Every investigation should drive action. And every action should be measured to see if it actually worked. That's the philosophy underneath everything. Access Windows, context as the essential frame, behavior as the outcome, learning as the goal, and action as the only proof that you actually understood anything. If you want to move from activity metrics to diagnostic metrics, you need a road map, not just a vision or a set of principles. You need a concrete path with phases and time frames because without that structure, this stays abstract and theoretical. It never actually happens. This isn't a one-time change where you just flip a switch. You're transforming how an entire organization sees itself and that takes time. But it does have a specific sequence. If you follow that sequence, it works. Phase one, establish baselines, weeks one to four. Start by measuring what you're already measuring and don't change a single thing yet. Just document the baseline. This matters because you need a reference point to know what before looks like. Otherwise you won't actually see when things start to shift. Pull your current metrics like deployment frequency, lead time, change failure rate, and MTTR. If you're already measuring developer satisfaction, grab that too. Write it all down. This is your starting line. Then you need to measure what you're currently ignoring. Look at your rework rate to see how much code written in the last two weeks is being rewritten or deleted. Check your flow efficiency to find out what percentage of time work is actually moving versus sitting idle. Decompose your review cycle time so you can see the actual time to first review and the duration of the review itself. You also need cognitive load indicators like context switching frequency and feature adoption rates from your product analytics. You don't need perfection here. You just need directional accuracy. You need to know what the system looks like right now with all of its problems visible. Know that as your baseline because you'll be comparing everything to this later. Phase two, diagnostic review, weeks 5 to 8. Stop having status meetings and start having diagnostic sessions. Bring in the people doing the work. The engineers, the managers, and the product and operations teams. Pull up that baseline data and start asking real questions instead of leading ones. Why is the lead time what it is? You aren't asking because you want it to be lower. You're asking because you want to understand what's creating that number. Look for where work gets stuck and identify which stage in the flow has the longest queue. That's the actual bottleneck in your reviews. You need to know who is doing all the work and why it takes as long as it does. And don't just guess if developers are healthy, actually survey them to understand their experience. Check which features are actually being used by pulling adoption data to see what customers are touching and what's just dead weight. This is an investigation, not a judgment. You aren't trying to fix anything yet. You're just trying to see the system clearly. Phase three, hypothesis and intervention, weeks 9 to 16. Based on what you learned in the last phase, propose one focused intervention. Don't try to do multiple things at once, just one hypothesis. You might think review is the bottleneck because reviews are taking 400% longer than they should. If reviewers are overloaded, you could test increasing capacity by adding a trained reviewer to the team for a month. Then you measure whether that actually improves the review cycle time. That's one hypothesis, one intervention and one measurement. Run the experiment and track the review cycle time and flow efficiency every week. See if the new reviewer is easing the load or if they're slowing things down because they have less experience. After four weeks, look at the data to see if the review time or flow efficiency improved. Did it create new problems or helped just a little bit? Now you know something real about your system. Not from a theory, but from an actual experiment. Phase four, learn and adjust. Week 17 to 20. You ran the experiment and you have the data, so now you have to decide what comes next. If the intervention worked, you have to figure out if you can scale it or make it permanent. If it helped, but not enough, you might combine it with better review tooling or clearer criteria. If it didn't work at all, then you know that wasn't the real constraint. You can pivot to the next hypothesis from your review phase. Maybe the bottleneck isn't capacity, maybe it's governance gates or unclear policies. This isn't a failure. It's learning. And learning is the only way you actually improve a system. Phase five, expand and operationalize. Weeks 21 to 28. Once you've proven an intervention works, you make it the standard, add it to your process, and then the team, and build it into how you work every day. Then you run the review and hypothesis phases again on the next bottleneck. You'll move faster this time because you've already proven you can do this. Phase six, continuous measurement ongoing. Once you've shifted to diagnostic metrics, the measurement becomes a continuous rhythm. You'll have weekly diagnostic reviews and quarterly checks to see if the system is actually getting healthier. You need regular team input on what's working and what isn't. This is the rhythm of systems thinking. You measure, investigate, intervene and then measure again. It's not faster than just demanding improvement, but it's real and it actually works. Conclusion, the choice ahead. Here's where we are. Your metrics are measuring activity while your system is drowning in cognitive load. Your best people are leaving, yet the data looks better than it's ever looked before. That isn't a contradiction. It's just the current state of organizations that adopted AI without rethinking how they measure success. You have a choice to make and it isn't a technical one. The choice is whether you're going to keep reading your dashboards the same way, watching activity metrics climb while the system degrades underneath you or you can do the harder thing. The thing that requires rethinking governance and having different conversations, it means admitting that door of four doesn't work anymore and that rework rate is the real truth teller. You have to decide if you're going to optimize for numbers or optimize for systems and you have to make that choice consciously because if you don't, the system will choose for you. You'll keep optimizing metrics and those metrics will keep driving behaviors that degrade the system until it eventually fails. It won't happen suddenly, but it will be inevitable. Attrition will speed up, quality will drop and people will burn out faster. Eventually, you'll realize the organization is half the size it was while running at a fraction of the velocity. That's the path if you don't choose. If you choose differently, you start measuring flow instead of activity. You measure cognitive load instead of utilization. You measure value instead of volume. You create a diagnostic dashboard that tells you where the system is breaking instead of a scorecard that just tells you what you optimized well. You change governance so that metrics become questions instead of judgments. You give the team's ownership of the data instead of letting executives interpret it from a distance. You run small experiments to test interventions instead of just demanding results and then you actually measure whether those interventions worked. You iterate, you learn and you improve. Something will shift, not immediately, but you'll see it within three months. Flow starts improving and the rework rate goes down. Developer satisfaction stops dropping because the friction is finally starting to disappear. In a year, you'll have a system that sustains itself because the culture around metrics has changed. People are investigating problems instead of hiding them and leadership is asking why instead of just demanding answers. That's the alternative path. It's harder to start because you have to admit your current metrics are incomplete. You have to admit your dashboards are lying to you. Those admissions are uncomfortable because they imply that what you've been doing is wrong, but here's the thing, this isn't your fault. Dora 4 worked fine when humans wrote all the code, but the model broke when AI started generating most of it. That's just what happens with systems when the world changes. The organizations that win in the next few years are the ones that recognize AI change the game. They'll see that activity metrics no longer tell the truth and that cognitive load is the new frontier. The organizations that don't shift are going to stay confused. They'll wonder why their metrics are so good while their system is so degraded, they'll try to push harder and the system will just fall apart faster. You don't have to be one of those organizations. You have the research and the framework and you see what's working for the people ahead of you. You have the code map and you know how to read the data without lying to yourself. The only question is whether you're going to do it. I wouldn't pretend it's easy because changing how an organization measures itself is a massive structural change. It affects hiring, promotions and accountability. But I know that organizations that make this shift don't regret it. The alternative is just watching the system degrade while the metrics improve and that's a nightmare. You don't want to be the person saying everything is fine while the organization falls apart. So do this. Start with phase one and document your baseline. Add the metrics you aren't measuring yet like rework rate and flow efficiency then move to phase two and have a diagnostic review with your best people to see the system clearly. Then do phase three. Pick one bottleneck and run an experiment. That's the whole thing. That's how you build a system that actually works. You don't have to do all of it today. You can start with one team in one experiment. Start small and prove it works because once you do everything else follows. Other teams will want to join in and the model will spread. That's how systemic change actually happens. Not with a mandate but with one successful experiment that shows people what's possible. You have everything you need. You understand the problem and you know the roadmap. The only thing left is to choose to do it. Subscribe to this podcast because we're going to dive deeper into these ideas and show you case studies of organizations making this shift. We'll talk to the leaders who have done this work so they can tell you what actually happened. And if you want to take this further, connect with me on LinkedIn. I'll send you resources and help you navigate the conversations you're about to have. This isn't theoretical. It's about building systems that actually work. The productivity illusion is real but the alternative is better.