 EN
 Deutsch
 Español
 Français
 Italiano
 Português
 Nederlands
 Polski
 Bahasa Indonesia
 Русский
 Українська
 العربية
 עברית
 हिन्दी
 日本語
 한국어
2026-07-16 · Season 3
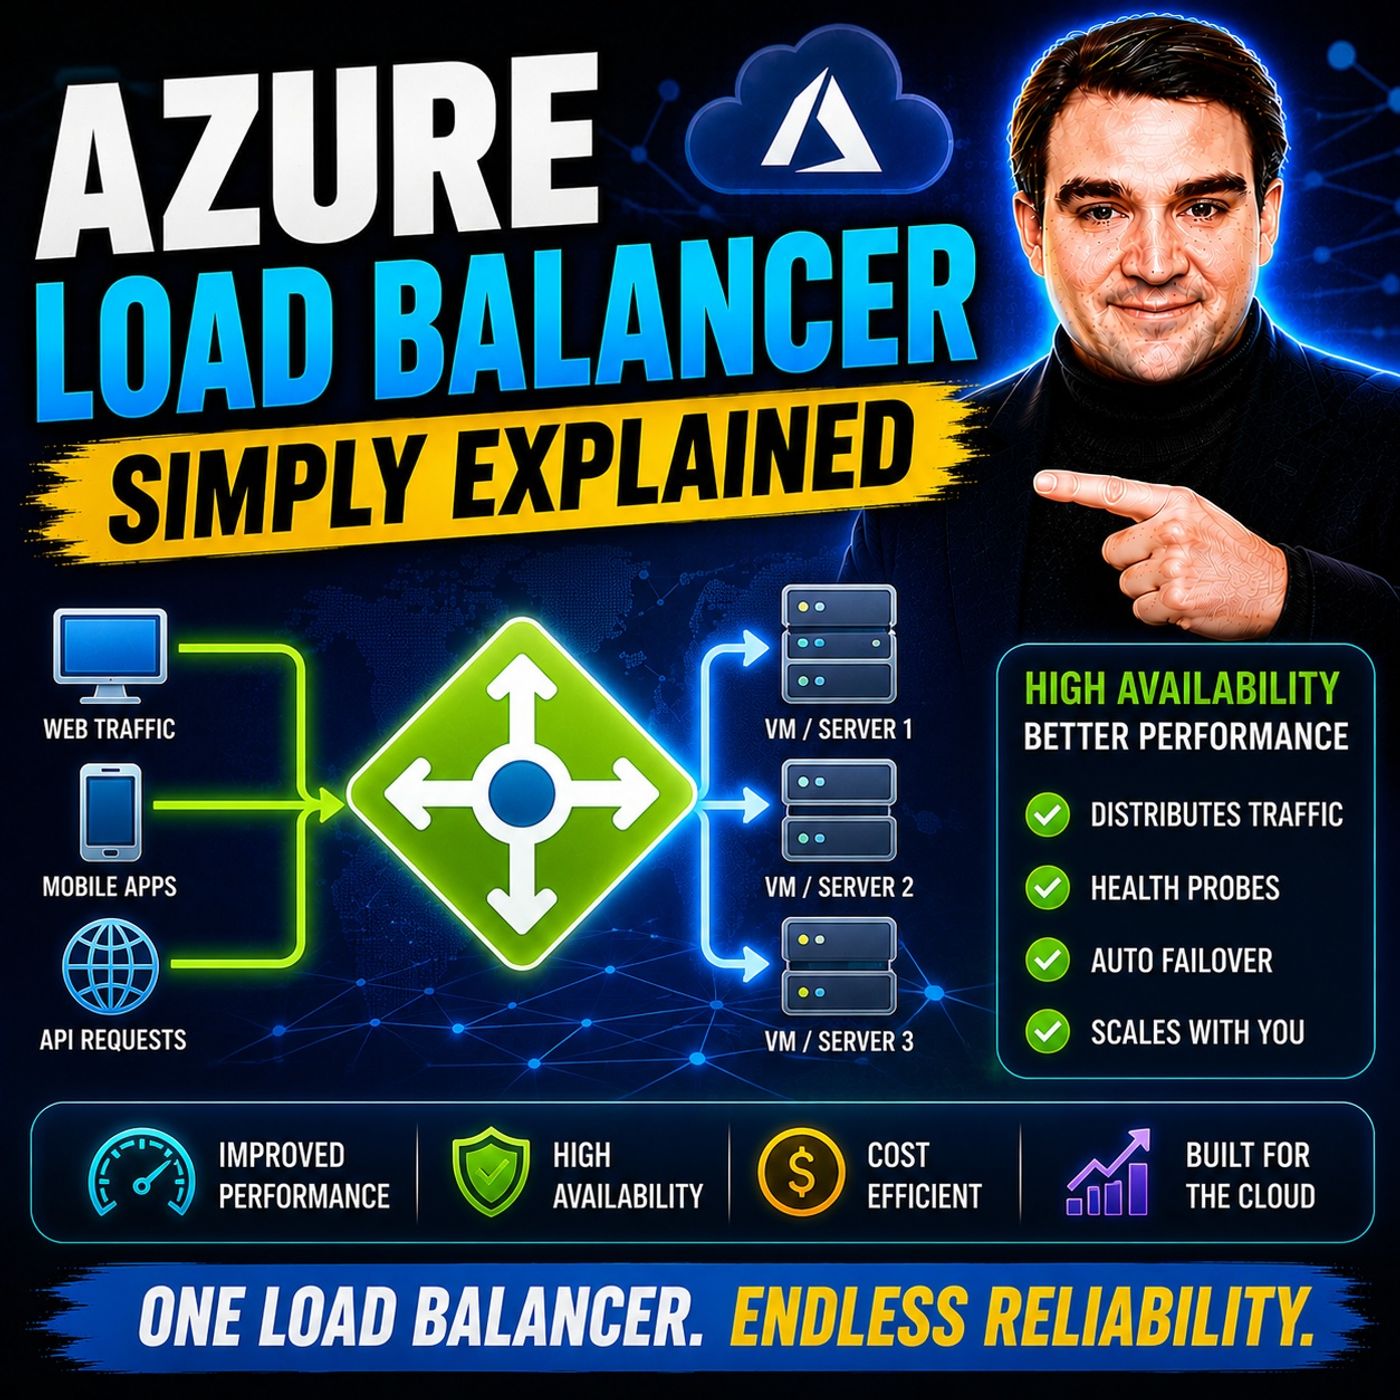
Azure Load Balancer — Simply Explained
Show notes
Every application starts small. A single virtual machine serves your website, processes customer requests, and handles all incoming traffic. At first, everything works perfectly. But as your user base grows, traffic spikes, maintenance windows, or unexpected server failures quickly expose a major weakness—your entire application depends on one machine. In this episode of m365.fm, we explain Azure Load Balancer in plain English and show how Microsoft distributes network traffic across multiple servers to improve availability, scalability, and reliability. You'll learn why Azure Load Balancer acts like a smart reception desk for your infrastructure, ensuring users are always connected to healthy servers without even realizing anything has changed. Whether you're preparing for Azure certifications or building production cloud applications, this episode gives you a practical understanding of one of Azure's core networking services. WHY EVERY MODERN APPLICATION NEEDS LOAD BALANCING Running applications on a single server creates three major risks: downtime, poor performance during traffic spikes, and maintenance interruptions. We explain why adding more servers alone doesn't solve the problem and why a load balancer is needed to intelligently distribute requests across multiple backend systems. Through simple real-world analogies—including a busy restaurant and a reception desk—you'll discover how Azure Load Balancer automatically directs incoming traffic to available virtual machines while protecting users from outages and keeping applications responsive under heavy workloads. FRONTEND IPS, BACKEND POOLS, HEALTH PROBES, AND RULES Azure Load Balancer consists of four core building blocks that work together to deliver high availability. This episode explains Frontend IP addresses, Backend Pools, Health Probes, Load Balancing Rules, and Inbound NAT Rules using practical examples that make Azure networking easy to understand. You'll learn how health probes continuously monitor server availability, why unhealthy virtual machines are automatically removed from rotation, and how Azure Load Balancer distributes TCP and UDP traffic using its hash-based load balancing algorithm. We also cover session persistence, client IP affinity, public versus internal load balancers, and why Azure Load Balancer operates at Layer 4 of the OSI networking model. STANDARD LOAD BALANCER, HIGH AVAILABILITY, AND BEST PRACTICES Modern Azure deployments almost always use the Standard Load Balancer, which provides zone redundancy, advanced diagnostics, support for up to 1,000 backend instances, and significantly improved resilience compared to the retired Basic SKU. We explain when to use Standard Load Balancer, Gateway Load Balancer, and internal versus internet-facing deployments. You'll also discover common configuration mistakes—including blocked health probes, incorrect Network Security Group rules, SKU mismatches, routing issues, and unnecessary session persistence—and learn how to troubleshoot them before they impact production environments. AZURE LOAD BALANCER VS. APPLICATION GATEWAY, FRONT DOOR, AND TRAFFIC MANAGER One of the most common Azure networking questions is choosing the right traffic distribution service. This episode concludes by comparing Azure Load Balancer, Azure Application Gateway, Azure Front Door, and Azure Traffic Manager, explaining where each service fits within a modern Azure architecture. You'll learn why Azure Load Balancer is optimized for Layer 4 TCP/UDP traffic, when Application Gateway becomes the better choice for web applications, and how Front Door and Traffic Manager extend traffic management across multiple Azure regions worldwide. Whether you're designing highly available business applications, building cloud-native services, or preparing for Microsoft Azure certifications, this episode provides the practical foundation needed to confidently deploy Azure Load Balancer and create resilient, scalable cloud infrastructure. Become a supporter of this podcast: https://www.spreaker.com/podcast/m365-fm-microsoft-365-azure-cloud-power-platform-ai--6704921/support.
Apple Podcasts · Spotify · YouTube · YouTube Music · Deezer
Host: Mirko Peters
Related articles
Transcript
Read the full transcript
Welcome to another episode of Microsoft Knowledge Nuggets here on M365 FFM, I'm your host, Mucopeters. In this series, we take one Microsoft technology and explain it in plain English. Today's topic is one that almost everyone has heard of, but very few people actually understand as you're a load balancer. Imagine running a restaurant with only one chef. If they call in sick, the kitchen shuts down. If a crowd shows up, the orders pile up, and nobody gets fed, that's the problem with running your app on a single server. Most people think a single server is fine for low traffic apps until it isn't. And by then, it's too late. By the end of this episode, you'll understand what Azure Load Balancer actually does, why you need one, and how it keeps your apps running even when things break. Think of it as the smart reception desk for your servers. That mental model is going to carry us through everything that follows. Why your app needs a bouncer, the case for load balancing? Here's the thing, when you start a new app, it's easy to just put everything on one server. One VM handles all the traffic. It's simple. It works, until it doesn't. That single server has three problems it can't solve on its own. First availability, what if the server crashes? The app goes down. Second, performance. What if traffic spikes? The server gets overwhelmed and your users get a spinning wheel of death. Third, maintenance. How do you update the software without taking the app offline? You can't, because there's only one server. The solution is obvious when you step back, spread the work across multiple servers, and put something in front that decides which server handles each request. That something is a load balancer. Let me give you a real example. Imagine a small e-commerce site during Black Friday. One server buckles under the traffic, pages load slowly. Customers leave. But with multiple servers behind a load balancer, nobody notices. Traffic gets spread out. Every server handles its share, and the site stays fast. One server fails, the load balancer sends traffic to the others. The customers never even know. So how does Azure actually do this? Let's build a mental model. The Smart Reception Desk. Your mental model for Azure Load Balancer. Think of Azure Load Balancer as the reception desk in a busy office building. The front end IP is the building's street address. It's the one single door that everyone knocks on. When someone visits your app, they hit this address, they don't know about the servers behind the scenes. The back end pool is the group of employees who actually do the work. These are your virtual machines. They sit in the back, ready to handle whatever comes in. Health probes are the receptionist checking if each employee is awake and able to take work. Every few seconds, the receptionist looks over and says, hey, are you still with us? If an employee doesn't respond, the receptionist stops sending people their way. Load balancing rules are the instructions for who goes where? The receptionist has a set of rules that say, anyone asking about billing goes to desk three, anyone with a delivery goes to desk five. In Azure, these rules say, anyone hitting port 80 goes to port 80 on a VM in the back end pool. Here's the thing to remember. The load balancer itself doesn't do the work. It's a traffic cop, not a worker. It just directs traffic to the servers that actually handle the requests. It operates at layer four of the network model, which means it works with TCP and UDP traffic. It doesn't read your web traffic or inspect what's inside the packets. It just looks at IP addresses and ports and makes a decision. Now let's break down each part of this reception desk one at a time. Frontend IP, back end pool and the rules that connect them. So you've got this reception desk, but how does it actually work? Let's walk through the three pieces that make it tick. First, the frontend IP. This is the address your user actually connect to. It can be a public IP if your app faces the internet or a private IP if it only lives inside your virtual network. You can even have multiple frontend IPs on the same load balancer. Think of it like having a main entrance and a loading dock, different traffic, different doors, same building. Second, the back end pool. This is where you put your virtual machines or VM scale sets. The load balancer only sends traffic to members of this pool that are healthy. If a VM is in the pool but not responding, it doesn't get traffic, simple as that. Third, the load balancing rules. These are the glue that connects everything. A rule says anyone hitting port 80 on this frontend IP gets sent to port 80 on a VM in this back end pool. That's it. You define the frontend, you define the back end and the rule tells the load balancer how to connect them. Here's a concrete example. Say you have a web app running on port 80. You create a frontend IP, let's call it 40.40404040. You create a back end pool with two VMs. Then you create a rule that says traffic to 40404040 on port 80 goes to port 80 on the back end pool. Now when someone visits your site, the load balancer picks one of those two VMs and sends the request there. There's also something called inbound in-at rules. These let you map specific ports on the frontend IP to specific VMs in the back end pool. So if you need to RDP into VM number one, you can hit port 5,001 on the frontend and the load balancer sends you directly to port 3389 on that VM. No public IP needed on the VM itself. It's a clean way to manage remote access without exposing your VMs directly to the internet. But how does the receptionist know which employee is actually ready to work? That's where health probes come in. Who's listening? Health probes and why they matter. This is the feature that makes high availability possible. Without health probes, your load balancer would just blindly send traffic to every server in the pool, even the dead ones. Here's how it works. The load balancer sends a ping to each back end server every few seconds. Think of it like the receptionist checking in on each employee. You still there? You still able to work? If the server responds great, it stays in rotation. If it doesn't respond within a certain window, the load balancer removes it from the pool immediately. More traffic gets sent to it until it starts responding again. There are two types of probes. TCP probes just check if the port is open. They say, "Hey, is port 80 listening?" If yes, the server is healthy. HTTP and HTTPS probes go a step further. They actually send a request to a specific endpoint and check for a valid response. This is useful when you want to make sure the application itself is running, not just the operating system. Here's where beginners get tripped up. You set up a probe, you configure everything correctly, but the backend keeps showing as unhealthy. Nine times out of ten, the problem is the network security group. The probe traffic comes from a specific Azure IP address, 168.63, 129.16. If your NSG blocks that IP, the probe can't reach your server. The server is running fine, but the load balancer thinks it's dead. Traffic stops flowing. It's a simple fix once you know to look for it, but it catches almost everyone the first time. The real impact of health probes is this. When a server fails, users see zero downtime. The load balancer detects the failure, removes that server from rotation, and sends all traffic to the remaining healthy servers. Your users never know anything happened. That's the whole point of a load balancer. Now how does the load balancer decide which server gets each visitor? It's not random. Distribution logic, how traffic gets spread. So you've got a load balancer, you've got healthy servers in the backend pool, and you've got health probes keeping everyone honest. But how does the load balancer actually decide which server gets each visitor? Here's the thing, most people get wrong. Azure load balancer does not use round robin. It doesn't just take turns sending traffic to each server like a schoolteacher calling on students. Instead it uses something called a hash based distribution. Here's how it works. When a request comes in, the load balancer looks at five things. The source IP address, the source port, the destination IP address, the destination port, and the protocol. That's called the five tuple hash. It runs those five values through a mathematical function and gets a number. That number determines which backend server gets the request. The key insight is that this is per flow, not per packet. Every packet in a single connection goes to the same backend server. You don't want packets from the same user session bouncing between different servers. That would break things. Once the load balancer decides which server handles a connection, all packets in that connection stay with that server. Now there's something called session persistence or client IP affinity. When you enable this, all requests from the same client go to the same backend server. This is important for stateful applications. Think about a shopping cart. You add items, you browse around, you come back. If each request went to a different server, your cart would keep disappearing. Session persistence keeps you tied to one server, so your state stays intact. But here's the catch. Your load balancer does not enable session persistence by default. You have to explicitly turn it on and you should only do that when you actually need it. Because session persistence can cause uneven traffic distribution. If one client makes a thousand requests, they all go to the same server, even if the other servers are sitting idle. For most applications, the default hash based distribution is actually better. It spreads traffic more evenly across your backend servers, especially when you have a large number of connections. So to summarize, hash based distribution, per flow routing and session persistence only when you need it. That's how traffic gets spread. The load balancer we've been talking about handles traffic from the internet. But what about traffic between your own services? Public versus internal, two flavors, same engine. So far, we've been talking about a public load balancer. Someone on the internet hits your front end IP and the load balancer sends them to a backend server. But that's only half the story. There are actually two flavors of Azure load balancer and they use the exact same engine. The only difference is the front end. A public load balancer has a front end with a public IP address. Users from anywhere on the internet can hit that IP and reach your application. This is what you use for anything that faces the outside world. Your website, your API, your customer facing app. An internal load balancer has a front end with a private IP inside your virtual network. Only resources inside your vnet can reach it. No internet access. This is what you use for internal services. Your databases, your APIs between application tiers, your microservices that talk to each other behind the scenes. Here's where it gets interesting. Both types use the exact same logic. Both use health probes. Both use the same distribution algorithm. Both support the same rules and features. The only difference is the IP address at the front. Public or private, that's it. In a real world architecture, you'd use both. A public load balancer at the web tier handles incoming traffic from users. Behind that, your web servers process requests and send them to an internal load balancer at the business logic tier. That internal load balancer distributes work across your application servers. So behind those, another internal load balancer might connect to your database cluster. Each tier gets its own load balancer and traffic flows from public to private. Each step handled by the right tool. But Azure gives you more than one type of load balancer. Let's clear up the difference between standard gateway and the retired one. Standard versus gateway versus the dead basic. So we've covered public and internal load balancers. But Azure actually gives you three different types of load balancers and knowing which one to use matters. The one you should use for pretty much everything new is the standard load balancer. It's zone redundant, meaning it can survive an entire Azure data center going down. It supports HA ports, which lets you load balance all ports and protocols at once for things like network virtual appliances. It can handle up to a thousand backend instances in a single pool. And it gives you advanced diagnostics so you can actually see what's happening with your traffic. Standard is the default choice. If you're building something new, start here. Then there's the gateway load balancer. This one is more specialized. It's not designed to distribute traffic directly to your application servers. Instead it's a middleman that hands traffic off to a security appliance before it reaches your app. Think firewalls, intrusion detection systems or packet inspection tools. The gateway load balancer sits in the traffic path, sends everything through the appliance first and then forwards the clean traffic to your application. You don't need this for a simple web app. But if you have strict security requirements and need to chain multiple network appliances together, this is the tool. And then there's the basic load balancer. Don't use it. You can use it for a simple web app. You can figure the health probe, but the backend servers keep showing as unhealthy. Nine times out of ten, the problem is that your NSG is blocking the probe traffic. The probe comes from a specific Azure IP address 168.63, 129.16. If that IP isn't allowed in your NSG rules, the probe can't reach your server. The server is running fine, but the load balancer thinks it's dead. The fix is simple, just add an inbound rule that allows traffic from that Azure IP on your probe port. That's it. Next up is the wrong probe protocol of port. You set up a TCP probe on port 80, but your application is actually listening on port 8080. The probe checks port 80, gets no response, and marks the server as unhealthy. The server is fine. The probe is just looking in the wrong place. Make sure your probe protocol and port match what your application is actually doing. If your app listens on 8080, probe port 8080. If your app expects an HTTP response, use an HTTP probe instead of TCP. As QMS match is another common one, you create a standard load balancer, but attach a basic public IP. They don't match, and the deployment fails or behaves unpredictably. The rule is simple. Keep your SKUs consistent. Standard with standard, basic with basic, and since basic is retired, just use standard for everything. Session persistence left on by mistake can cause uneven traffic distribution. You enable sticky sessions because you read somewhere that it's good for performance, but your application doesn't actually need it. Now one server gets hammered with traffic while the other sit idle. The fix is to understand your application's state requirements. If your app stores session state in a database or distributed cache, you don't need session persistence at the load balancer level. Only enable it when you absolutely have to. User defined routes or UDRs can silently break your load balancer. You set up a custom root table that sends traffic through a firewall or a network appliance. The problem is that your probe traffic also follows those routes. If the root sends probe packets somewhere they shouldn't go, the backend appears unhealthy even though the application is running perfectly. Always check your root tables when troubleshooting load balancer issues. And here's a classic one. Someone sets up a load balancer with a single VM in the backend pool. They tested traffic flows, everything looks good, then they stopped the VM to simulate a failure, and the app goes down. They think the load balancer is broken. It's not. A load balancer with one backend server provides zero redundancy. If that server goes down, there's nowhere else to send traffic. Always have at least two instances in your backend pool. That's the whole point of having a load balancer in the first place. So here's your troubleshooting checklist. Check the NSG rules, check the probe protocol in port, check the root tables, and check the application health directly from another VM in the same network. Nine times out of ten, the problem is in one of those four places. When to choose load balancer versus app gateway versus traffic manager. So you understand what a load balancer does. But as your actually gives you four different services for distributing traffic, and each one has a specific job as your load balancer is layer four. It handles any TCP or UDP protocol within a single region. Use it for internal services, non-HTTP workloads, or when you just need simple distribution. It's your foundation. Application gateway is layer seven HTP and HTTP only. Think of it like a hotel concierge who knows exactly where each guest should go based on what they're asking for. It can route traffic by URL path, handle SSL termination, and protect your web apps with a web application firewall. Use it when you need smart routing for web traffic. Traffic manager works at the DNS level. It's like a travel agent who sends you to the nearest office. If your users are in Europe, it routes them to your European servers. If your European data center goes down, it sends them to the next closest region. As your front door is the global version of application gateway. It gives you layer seven routing, acceleration, and WAF protection at the edge. Use it for global web applications where performance and security matter. Here's the practical rule of thumb. Use load balancer for non-HTTP traffic. Use application gateway for web apps in one region. Use front door or traffic manager for global distribution. Start with load balancer as your foundation and layer the other services on top as your needs grow. So now you have it. Azure load balancer is the smart reception desk for your servers. The front end IP is the door everyone knocks on. The backend pool is your team doing the work and health probes keep everyone honest. Next time you set up a VM in Azure, ask yourself one question. What happens if this one VM fails? If the answer is downtime, you need a load balancer. Start with a standard load balancer in front of at least two VMs. Add health probes. Test by stopping one VM and watch the traffic keep flowing. That's all for this episode of Microsoft Knowledge Nuggets. Subscribe on your favorite podcast platform and share this with someone starting their journey. Next time we'll cover application gateway. Simply explained.