 EN
 Deutsch
 Español
 Français
 Italiano
 Português
 Nederlands
 Polski
 Bahasa Indonesia
 Русский
 Українська
 العربية
 עברית
 हिन्दी
 日本語
 한국어
2026-07-14
Azure Chaos Studio - Simply Explained
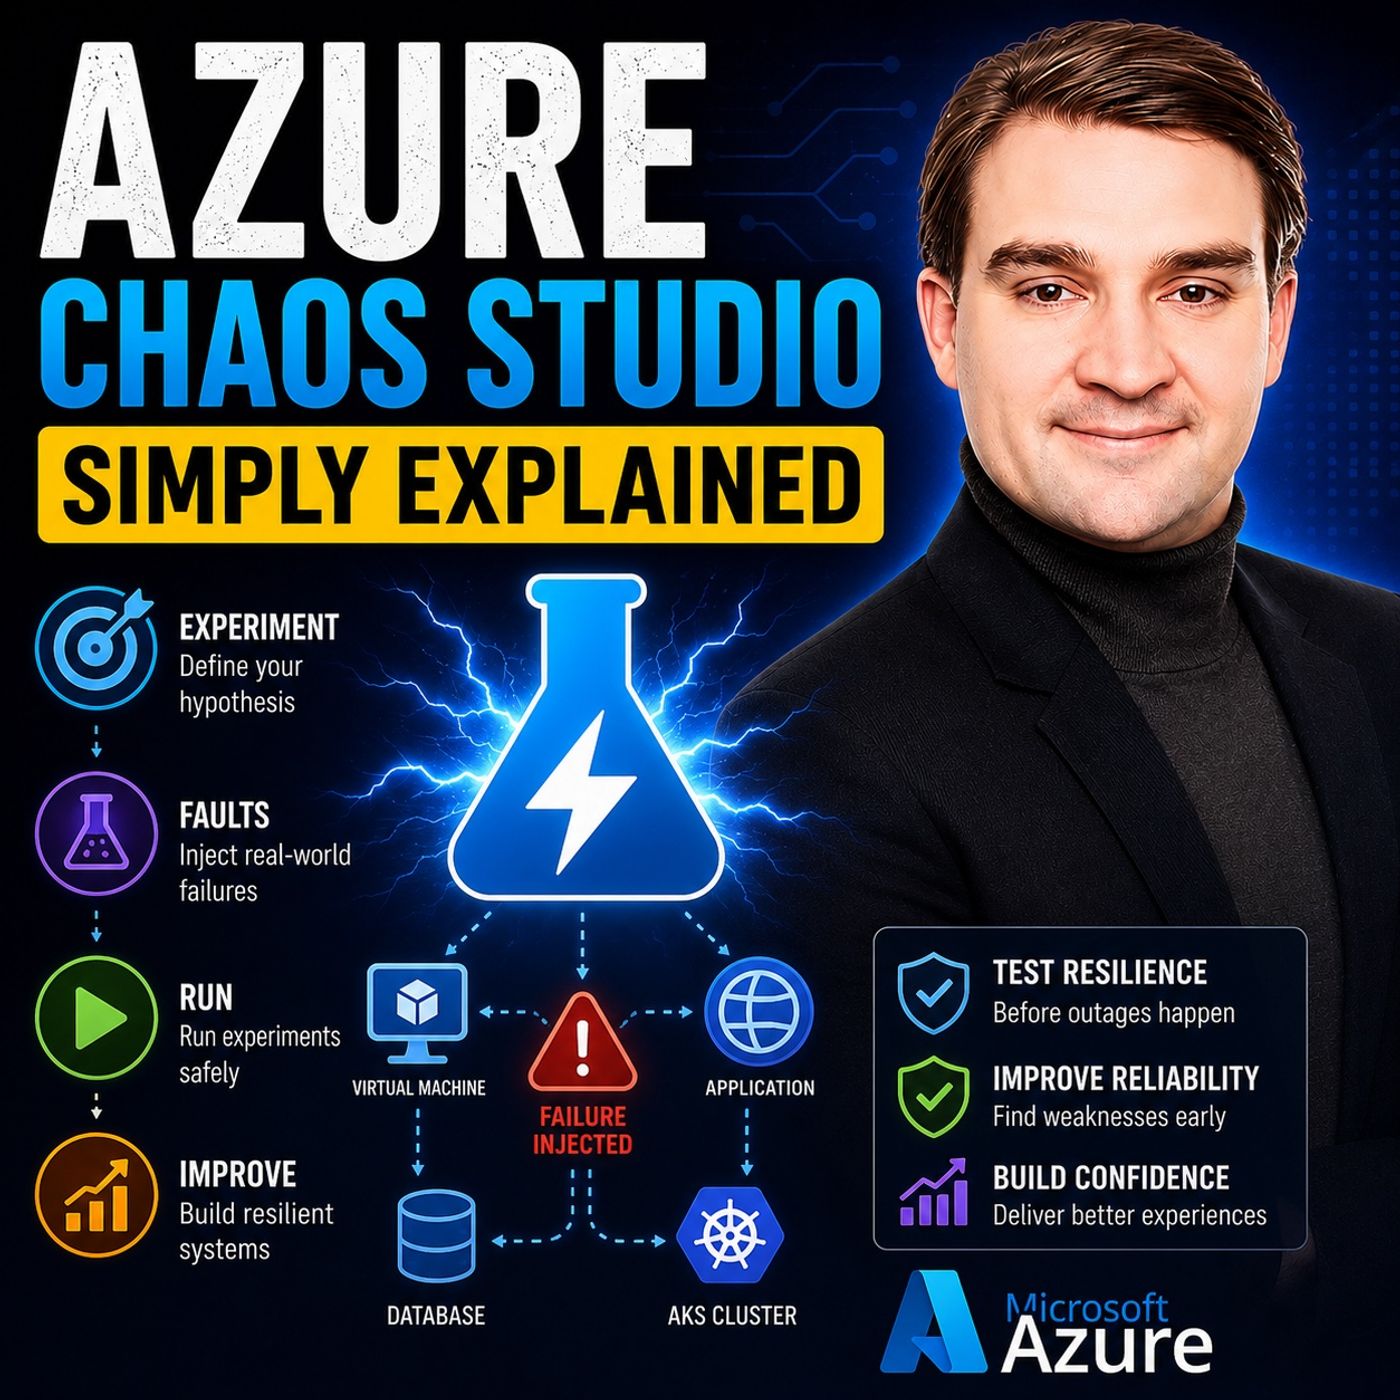
Show notes
Cloud applications rarely fail because of a single bug. More often, they fail because of unexpected combinations of network latency, overloaded servers, unavailable databases, or infrastructure outages. The challenge is that traditional testing assumes everything works perfectly, while production environments rarely do. In this episode of Microsoft Knowledge Nuggets on M365 FM, Mirko Peters explains Azure Chaos Studio in plain English and shows how organizations can deliberately introduce controlled failures into their Azure environments to improve resilience before real incidents occur. Whether you're a cloud architect, DevOps engineer, SRE, developer, or IT administrator, you'll discover why chaos engineering has become an essential practice for building highly available cloud applications. WHY TRADITIONAL TESTING ISN'T ENOUGH Conventional testing verifies that software behaves correctly under ideal conditions, but production systems operate in a world full of unexpected failures. Virtual machines crash, databases slow down, APIs become unavailable, and network latency increases without warning. Modern cloud applications consist of dozens of interconnected services where a single failure can quickly cascade throughout an entire platform. Azure Chaos Studio helps organizations validate not only whether applications work, but whether they continue working when critical components fail unexpectedly. UNDERSTANDING CHAOS ENGINEERING Chaos engineering is not about randomly breaking systems—it is a scientific process for validating system resilience through carefully controlled experiments. Teams begin with a hypothesis, introduce a specific failure, observe how the application responds, measure the results, and strengthen weaknesses before they become production outages. Azure Chaos Studio provides a safe and repeatable framework for conducting these experiments while limiting the blast radius and maintaining full control over every test. HOW AZURE CHAOS STUDIO WORKS Azure Chaos Studio is a fully managed Azure service that injects real failures directly into Azure resources. Organizations can simulate virtual machine shutdowns, CPU and memory pressure, network latency, application failures, process termination, DNS disruptions, Kubernetes faults, and many other real-world scenarios. Experiments can target Azure Virtual Machines, Virtual Machine Scale Sets, Azure Kubernetes Service (AKS), Azure Cosmos DB, Azure Cache for Redis, networking components, and additional Azure services. Using steps, branches, actions, and reusable experiment definitions, teams can model complex failure scenarios without building custom tooling. BUILDING RESILIENT CLOUD ARCHITECTURES One of Azure Chaos Studio's greatest strengths is validating cloud architecture under realistic operating conditions. Engineers can verify load balancers, autoscaling, failover mechanisms, monitoring, alerting, disaster recovery procedures, and application resiliency before users experience real outages. Combined with Infrastructure as Code, Azure DevOps, GitHub Actions, ARM templates, Bicep, and CI/CD pipelines, chaos experiments become a regular part of modern cloud engineering rather than occasional manual testing. SAFETY, GOVERNANCE, AND CONTROL Despite its name, Azure Chaos Studio is designed around safety and governance. Every experiment defines explicit targets, approved fault types, execution order, duration, and scope before any disruption occurs. Organizations decide exactly which Azure resources can participate, ensuring production environments remain protected while resilience testing is performed under carefully controlled conditions. This enables teams to learn from failures without creating unnecessary business risk. KEY TAKEAWAYS Azure Chaos Studio transforms failure from something organizations fear into something they actively learn from. By safely injecting controlled disruptions into Azure environments, teams can validate resiliency, improve availability, strengthen disaster recovery, and identify hidden weaknesses long before customers are affected. As cloud applications continue growing in complexity, chaos engineering is becoming a core DevOps and Site Reliability Engineering practice—and Azure Chaos Studio provides Microsoft's enterprise platform for building resilient, reliable, and production-ready cloud solutions. Become a supporter of this podcast: https://www.spreaker.com/podcast/m365-fm-microsoft-365-azure-cloud-power-platform-ai--6704921/support.
Apple Podcasts · Spotify · YouTube · YouTube Music · Deezer
Host: Mirko Peters
Guests
Related articles
Transcript
Read the full transcript
Welcome to another episode of Microsoft Knowledge Nuggets. I'm your host, Mirko Peters. What if you could break your own cloud apps on purpose in a controlled way to make them stronger? Sounds backwards, but it's the same logic firefighters use when they set a controlled burn. They start small fires on purpose to clear out dry brush. So when a real wildfire comes, there's nothing left to burn. That's what Azure Chaos Studio does for your cloud apps. By the end of this episode, you'll understand what the service is, why you'd want to use it, and how it helps you build systems that don't fall over when things go wrong. So grab your coffee and let's start with the problem. The problem. Why traditional testing isn't enough? Here's the thing about traditional testing. It checks whether your software works as designed under normal conditions. You write a test, run it, and if the output matches, you pass. Great for catching bugs, but it misses how your system behaves when something unexpected fails, like a network timeout, a virtual machine that dies, or an entire availability zone going dark. Modern cloud apps aren't simple anymore. They're distributed systems that talk to databases, caches, identity services, third party APIs, and other microservices, and all those pieces have hidden dependencies. One small failure can cascade through the whole system. A database gets slow, the app times out, the load balancer marks it unhealthy, traffic reroutes, other instances get overwhelmed, and suddenly your entire application is down. Traditional testing doesn't catch that because it tests in perfect conditions with everything available, zero network latency, and no one shutting down VMs during your test run. So you deploy to production feeling confident, then reality hits, and that false confidence is dangerous because it's the difference between knowing your system works and knowing it survives. And that's where chaos engineering comes in. What chaos engineering actually is? Chaos engineering is a practical method. You inject real controlled failures into your system and observe how it reacts. This doesn't happen in a lab or a simulation. It happens on your actual resources. The idea is simple, you start with a hypothesis. Something like, if we lose one virtual machine, the load balancer should keep routing traffic to the remaining instances. Then you run an experiment, you shut down that VM and watch what happens. Does the load balancer do its job? Does the app stay up? Do your alerts fire correctly? You measure everything and then you fix what breaks. Here's the thing, chaos engineering is not random destruction. It's not a developer walking into the server room and pulling cables for fun. It's scientific, repeatable, and safety constrained. You define the blast radius and control exactly what fails when and for how long. And most importantly, you learn from it. Every experiment gives you evidence. Either your hypothesis was right and your system is resilient, or it was wrong and you found a weakness to fix. Either way, you win. The challenge is that building your own chaos engineering tooling is hard. You'd need to write scripts to shut down VMs, inject CPU pressure, block network traffic, and orchestrate all that safely and repeatedly. That's a lot of work. And that's exactly why Azure built a managed service to handle it. Introducing Azure Chaos Studio. Azure Chaos Studio is a fully managed service for running chaos experiments directly on your Azure resources. No custom scripts, no third party tools, no building your own failure injection platform. It's all in the Azure portal ready to go. Here's how it works. Chaos Studio gives you two ways to inject faults. Service direct faults run through the Azure control plane itself. You tell Chaos Studio to shut down a VM and it does it through Azure's own APIs. No agent needed. Agent-based faults install a small agent inside your virtual machine. Then it can crank up the CPU to 100%, fill up memory or kill a specific process. These let you simulate problems that happen inside the operating system, not just at the resource level. Here's an analogy. Imagine you own a large office building. You want to know if your fire escapes actually work. Waiting for a real fire is a terrible idea. So you hire a dedicated disaster crew. They come in, block off a stairwell, simulate smoke on the third floor and watch how people react. That's Chaos Studio. It's your disaster crew. You call them in, they run the drill, and you learn whether your building is safe before the real emergency hits. Chaos Studio supports a wide range of Azure resources. Virtual machines, VM scale sets, Azure Kubernetes service clusters, Azure Cosmos DB, Azure cache for readers, network security groups, and more. The fault library keeps growing. So whether you're running a simple two-tier app or a complex microservices architecture on AKS, you can test it. Here's the good news. You don't need to build any custom tooling. Everything is available through the Azure portal, the CLI, REST APIs, ARM templates, or BICEP. You can define your experiments as code and integrate them into your deployment pipelines. But let's not get ahead of ourselves. First, let's break down how these experiments are actually structured. The building blocks, targets, steps, branches, actions. Every chaos experiment starts with targets. What is a target? It's simply an Azure resource you want to run faults against. You open Chaos Studio, find your resource, a VM, a scale set, an AKS cluster, and you onboard it. That means you tell Chaos Studio, this resource is available for experiments. Here's the key. When you onboard a target, you also pick which faults you're willing to allow on that resource. You don't enable everything. You choose CPU pressure, yes. Full VM shutdown? Maybe not for production? You decide. Once your targets are onboarded, you create an experiment. Think of an experiment as a blueprint. It describes exactly what failures to inject in what order, against which targets, and for how long. You don't just say break something. You define the entire scenario upfront. Experiments have a simple structure. Steps, branches, and actions. Steps run one after another. Step one finishes, then step two starts, then step three. This is how you model a timeline. First, degrade the network, then stress the CPU, then shut down a VM. Each step is a phase in your scenario. Inside each step, you can have one or more branches. Here's where things get interesting. Branches run in parallel. So inside step one, you could have branch A adding latency to your database and branch B cranking up CPU on your web servers, both at the same time. This lets you simulate complex, multi-fault scenarios that mirror real-world incidents. Then you have actions. Actions are the actual faults. CPU pressure, memory exhaustion, VM shutdown, network delay, DNS block, process kill. Each action targets a specific resource or group of resources. And again, you can only use actions that you've enabled on that target. That's your safety net. If you didn't enable VM shutdown on a target, the experiment simply won't run that action. So the workflow looks like this, onboard your targets. Enable the faults you're comfortable with. Create an experiment with steps, branches, and actions. Then run it. But before we get into running one, there's something important to understand. When chaos studio runs an experiment, it's not simulating anything. It's actually doing these things to your resources. CPU pressure is real CPU pressure. A VM shutdown is a real shutdown. That's the whole point. You're testing how your system behaves under actual failure conditions. And that means you need to be careful. So let's walk through a real experiment and see how it all comes together. Running your first chaos experiment. Let's make this real. Imagine you have a web application running on three virtual machines inside a virtual machine scale set. Each VM leaves in a different availability zone. You have a load balancer in front distributing traffic across all three. The hypothesis is simple. If we lose an entire availability zone, the load balancer should reroute traffic to the remaining two VMs and the application stays available. So you design an experiment with two steps. Step one, stress two of the three VMs with 95% CPU for five minutes. That simulates a noisy neighbor scenario or a runaway process. Step two, abruptly shut down all the VMs in zone two. That simulates a real zone outage. You run the experiment and then you watch what happens. Here's what you'd see. In the first five minutes, two VMs, spike to 100% CPU, the third one stays normal because you didn't target it. You're monitoring dashboards light up. Alerts fire. The load balancer notices that those two VMs are struggling, but because they're still technically running, it keeps sending them traffic. Your app slows down but doesn't go offline. That's interesting. You learn something already. Then step two kicks in. The VMs in zone two are abruptly shut down, not gracefully, not with a warning. They just disappear. One of those two stressed VMs was in that zone, so it's gone. The load balancer sees the health probe fail, removes it from the back end pool, and routes all traffic to the remaining healthy VMs. Your app stays up. The hypothesis holds. But here's what you might not expect. The remaining VMs now have to handle 100% of the traffic. If you didn't have enough capacity to absorb that load, you'd see latency spike. Maybe the app stays technically online, but users feel the pain. That's a finding. You now know you need either more headroom or faster auto scaling. And remember, this isn't a simulation. When chaos studio runs this experiment, those VMs actually hit 95% CPU. That zone two shut down is a real shut down. The VMs stop the load balancer rebalances, and your application either survives or it doesn't. That's the whole point. You're not guessing. You're watching real behavior under real failure conditions. You learn whether your app stays up or falls over. And if it falls over, you fix it before your customers ever see it happen. But this power comes with responsibility. You need to be careful. Safety first, avoiding unplanned outages. Chaos studio has multiple safety mechanisms built in. And before you run your first experiment, you need to understand every single one. The first safety layer is identity and permissions. Every experiment you create gets its own system assigned managed identity. But that identity starts with zero permissions by default. You have to explicitly granted access to the resources it needs. And you grant the minimum permissions required. If an experiment only needs to stress CPU on two VMs, you scope the permissions down tight instead of allowing it to shut down everything in the resource group. Then there's the fault enablement I mentioned earlier. When you onboard a target, you choose exactly which faults you're willing to allow. If you never enable VM shut down on a production scale set, no experiment can shut down those VMs, even if someone targets them by accident. It's a hard block that requires you to deliberately opt into each fault type. Now about where to start and the answer is simple. Start small and start in a non-production environment. Run your first experiments in dev or staging, test with a single VM and a single fault, and validate that your monitoring works, your alerts fire, and you can cancel the experiment if something goes wrong. Only after you've built that confidence in a safe environment, should you even think about touching production. Microsoft has a warning about this that I want to share directly. They call it a resume in generating event. If you run a chaos experiment in production without proper safeguards and it takes down your entire application, that's the kind of mistake that could get you fired. That's not hyperbole. Chaos Studio is powerful because it actually does things to your resources, so use that power wisely. The last safety net is monitoring and cancellation. While an experiment runs, you can watch the progress in real time. You see which steps completed, which branches are active, and which actions are executing. If something looks wrong, you hit cancel and the experiment stops immediately. The resources that were affected stay in whatever state they're in, but no new faults get injected. So keep your dashboards open and your finger on the cancel button. Start small, be deliberate, and respect the power of the tool. So now that you know how to stay safe, the question is, where should you actually run these experiments? Shifting left versus shifting right. So where do you actually run these experiments? There are two main approaches and most teams use both. The first is shifting left. You run chaos experiments early in your development life cycle. As soon as code gets deployed to a test environment, you hit it with faults and make it part of your CICD pipeline. The pipeline deploys the app runs a chaos experiment to stress it, checks that it survives, and only then promotes the build to the next stage. Think of it as a quality gate, just like unit tests or security scans. If the app can't handle a VM shutdown in staging, it doesn't go to production. The second approach is shifting right, which means running experiments in production. And yes, that sounds terrifying, but hear me out. You don't start there. You only shift right after you've built confidence in non-production environments. You begin with small, limited experiments. Maybe you stress CPU on one instance during a low traffic period. You watch closely, you learn, and then you expand. Maybe you shut down a single VM in production during business hours and validate that your load balancer actually re-route traffic, that your users don't notice a thing, and that your monitoring catches it all. Over time, you build up to more aggressive experiments. There's a third approach that sits in the middle, game days. A game day is a scheduled chaos drill, where you bring together your development team, operations team, security team, everyone who would be involved in a real incident. You run a chaos experiment and practice your incident response. Who gets the alert, who makes the call to escalate? What's the communication chain? How fast can you diagnose the issue? Game days test the technology, but more importantly, they test the people and processes around it. The key idea across all three approaches is that chaos engineering is not a one-time test. You don't run one experiment, declare your system resilient, and move on. Systems change, code changes, configurations change, dependencies change. What was resilient last month might be fragile today. The goal is continuous resilience validation. You run experiments regularly, integrate them into your release process, and make them part of your operational rhythm. So what's the real value of all this effort? The real value, building confidence. Chaos engineering does more than find bugs. It builds confidence, and that's a completely different thing. A bug is a specific defect. You fix it and move on, but confidence is a feeling it's knowing your system can survive the unexpected, and you can't get that from unit tests or integration tests alone. You get it from watching your system handle a real failure and come out the other side. This process forces you to improve things you might otherwise ignore. You're monitoring, for example. When you run a chaos experiment, you quickly discover whether your dashboards show the right metrics, whether your alerts fire at the right thresholds, and whether your on-call team gets notified in time. If you can't see the failure happening, you can't respond to it. Chaos experiments expose those gaps. They also uncover hidden assumptions. Every architect has said something like, "If the database goes down, the app should just cache the last known data and keep running." That sounds good on a whiteboard, but does it actually work? Have you ever tested it? Chaos experiments answer that question with real evidence. You shut down the database and watch what happens. Maybe the app handles it gracefully. Maybe it crashes, either way you learn something you didn't know before. Chaos engineering is most powerful when you combine it with other resilience practices. Load testing, for example. You can stress your system with simulated traffic and inject faults at the same time, and that's a much more realistic test than either one alone. Tools like Azure Monitor and Application Insights give you the data to understand what happened during the experiment. Together they form a full resilience toolkit. Load testing tells you if your system can handle the traffic. Chaos engineering tells you if it can survive the failures. The result is fewer surprises. When a real outage happens, you've already seen something like it before. Your runbooks are tested, your team knows what to do, and your monitoring is tuned. You recover faster. Your user's barely noticed. That's the whole point. Not to break things for fun, but to build systems that don't break easily. And when they do break, to recover so fast nobody remembers it happened. So that's Azure Chaos Studio. It lets you test your systems resilience by injecting controlled failures before your customers ever experience them. If this episode made sense of another piece of the Microsoft Cloud puzzle, hit subscribe and share it with someone starting their cloud journey. They'll thank you later.