 EN
 Deutsch
 Español
 Français
 Italiano
 Português
 Nederlands
 Polski
 Bahasa Indonesia
 Русский
 Українська
 العربية
 עברית
 हिन्दी
 日本語
 한국어
2026-07-29 · Season 4
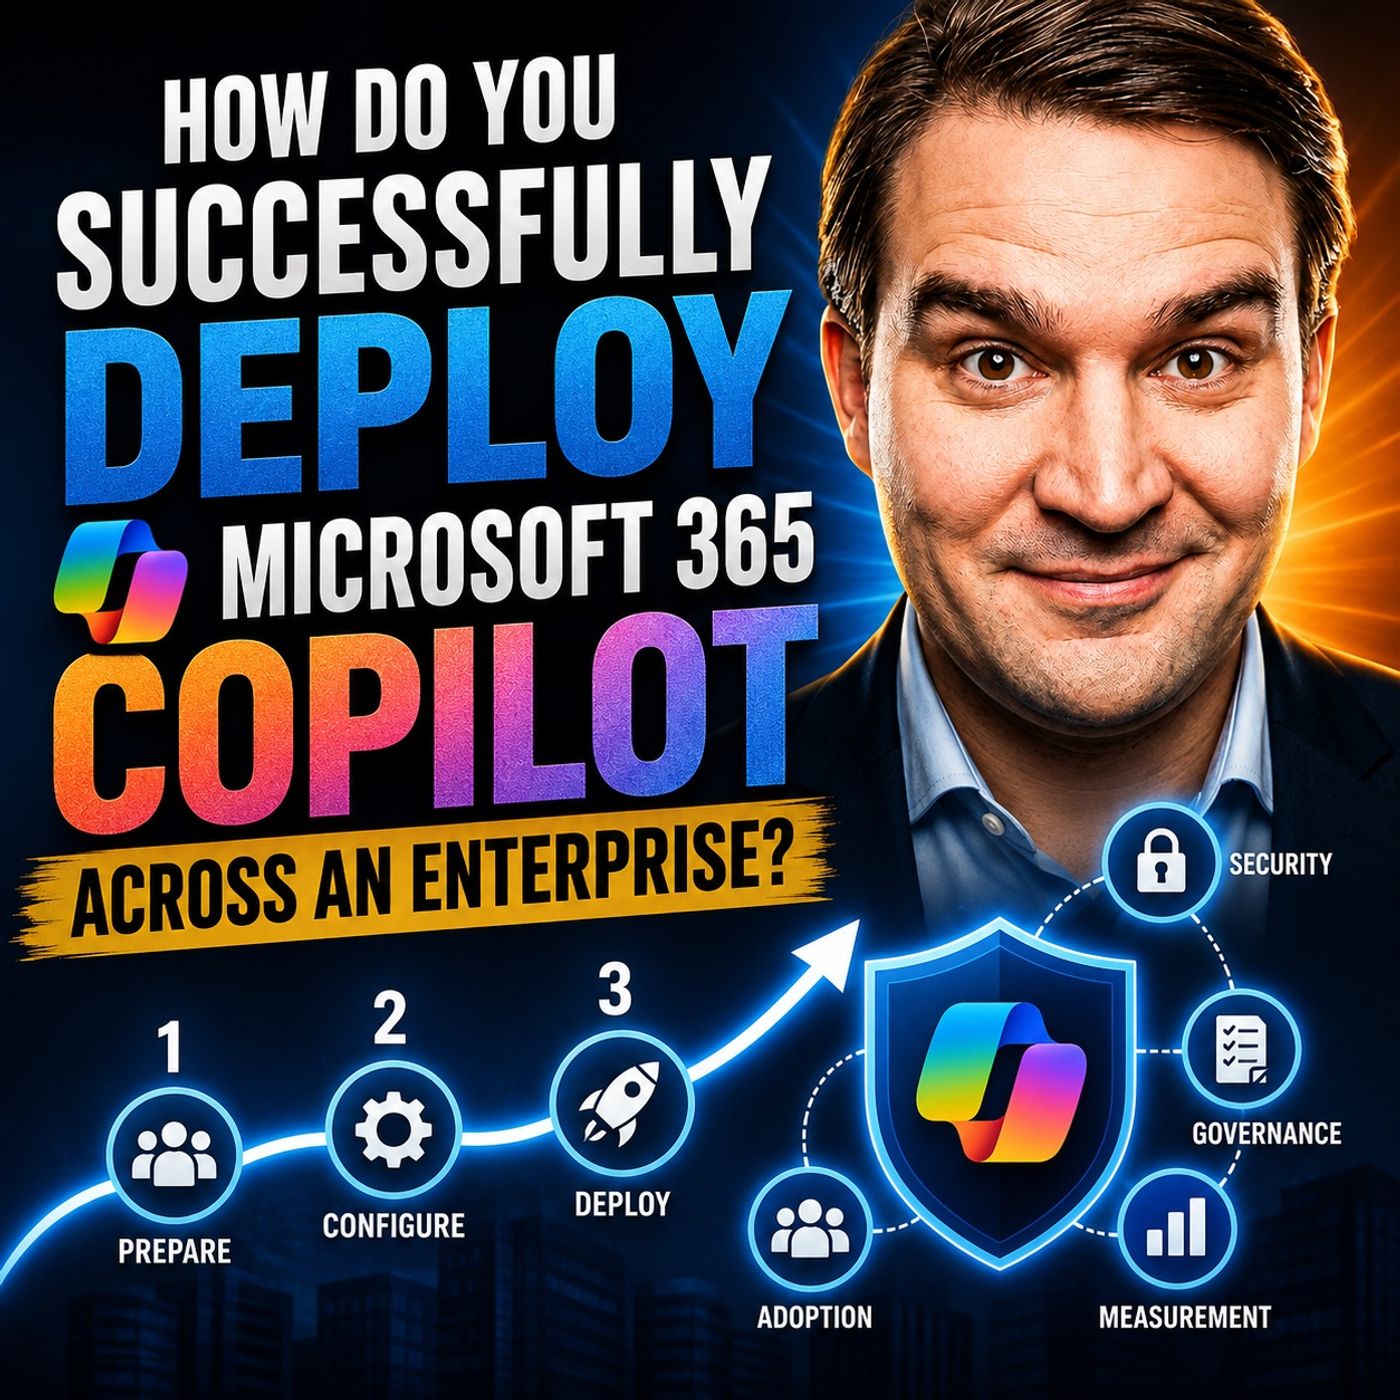
How Do You Successfully Deploy Microsoft 365 Copilot Across an Enterprise?
Show notes
A successful Microsoft 365 Copilot deployment begins long before licenses are assigned. Organizations should first define measurable business outcomes, identify high-value use cases, and secure executive sponsorship across IT, security, finance, and business leadership. Rather than treating Copilot as another software rollout, enterprises need an AI operating model that aligns governance, adoption, security, and ROI with real business processes. Starting with targeted scenarios creates faster wins while reducing risk and establishing a repeatable framework for future AI initiatives. ASSESS MICROSOFT 365 READINESS BEFORE ENABLING COPILOT One of the biggest mistakes organizations make is assuming their Microsoft 365 tenant is AI-ready simply because they own the licenses. Before deployment, businesses should assess identity management, SharePoint permissions, Teams collaboration spaces, OneDrive sharing, Microsoft Entra ID, Conditional Access, and overall information architecture. Existing oversharing, outdated permissions, unmanaged guest accounts, and poor data ownership become significantly more visible once Copilot can surface enterprise knowledge through natural language. A structured readiness assessment identifies critical risks before they become security incidents during rollout. SECURE YOUR DATA WITH GOVERNANCE, PERMISSIONS, AND MICROSOFT PURVIEW Microsoft 365 Copilot never creates new permissions—it simply works with the permissions users already have. That makes governance, Microsoft Purview, sensitivity labels, Data Loss Prevention, lifecycle management, and permission cleanup essential parts of every deployment. Organizations should prioritize high-risk content, establish clear ownership of SharePoint sites and Teams, implement strong information protection policies, and continuously review access rights. AI success depends as much on data quality and governance as it does on the underlying technology. RUN A CONTROLLED COPILOT PILOT BEFORE SCALING ACROSS THE ENTERPRISE Enterprise AI should expand through carefully planned pilot programs instead of company-wide deployments. Successful pilots focus on repeatable business workflows, measurable productivity improvements, and clearly defined success criteria. Business owners, IT, security, and finance should jointly evaluate business outcomes, adoption rates, governance findings, and user feedback before approving additional rollout phases. Every pilot should generate practical lessons that improve future deployments rather than simply proving that Copilot can generate content. DRIVE MICROSOFT 365 COPILOT ADOPTION WITH CHANGE MANAGEMENT Technology alone does not transform an organization—people do. Successful Copilot adoption requires executive communication, role-based enablement, workflow-specific training, AI champions, ongoing coaching, and continuous learning. Employees need practical guidance on when to trust Copilot, when human review remains mandatory, and how AI supports rather than replaces professional judgment. Measuring adoption should focus on changed business behavior and improved workflows instead of simple prompt counts or login statistics. MEASURE COPILOT ROI AND BUILD A SCALABLE ENTERPRISE AI PLATFORM The true return on Microsoft 365 Copilot comes from measurable business improvements rather than AI usage alone. Organizations should track workflow efficiency, quality improvements, reduced rework, employee productivity, governance maturity, and financial outcomes across every deployment phase. A successful rollout creates more than a productive workforce—it establishes the governance, architecture, operating model, and organizational experience required to scale future AI capabilities such as Copilot Studio, AI agents, Microsoft Graph integrations, and enterprise automation. Become a supporter of this podcast: https://www.spreaker.com/podcast/m365-fm-microsoft-365-azure-cloud-power-platform-ai--6704921/support.
Apple Podcasts · Spotify · YouTube · YouTube Music · Deezer
Host: Mirko Peters
Related articles
Transcript
Read the full transcript
Picture a global enterprise with offices across Europe, North America and Asia. The board has asked for an AI plan. The CEO wants a visible result this quarter. Procurement has negotiated the co-pilot agreement, the licenses are approved, and the first pilot group has already been told they'll get access next month. On paper, the project looks simple. Assign licenses, send a launch email, run a few training sessions, show usage in a dashboard, then the CISO asks a question that changes the meeting. What can co-pilot expose through the permissions we already have? Nobody in the room has a clean answer. The SharePoint estate has grown for more than a decade. There are project sites with no named owner. Teams created for initiatives that ended years ago still hold documents. OneDrive folders have been shared through old links. Some groups include external guests who no one has reviewed recently. A finance library has broken inheritance because someone needed to share one file quickly, which is how these things often start. Co-pilot doesn't invent new access. It works within the access a user already has, but that's exactly the issue. For years, weak permissions can hide in plain sight because most people don't know where to look. A document may sit in an old site, buried in a library with a vague name. Accessible to far more people than intended, it exists, but it's hard to find. Co-pilot changes that experience. It can make information easier to discover, connect, summarize, and reuse. That's the business promise. It can also make old oversharing far easier to act on. So the CIOC speed, the CSOC's exposure, finance sees a growing license commitment. Business leaders see people already using public AI tools because they're trying to get work done faster. All of them are right. The real question isn't whether you can deploy Co-pilot. You can. The question is whether you can turn it into a secure, scalable business capability rather than an expensive pilot that creates a few good demos, a spike in support tickets, and a difficult conversation at the next renewal. This isn't a software decision alone. It's an operating model decision. You're deciding how your organization will use AI with its data, how it will manage risk, who will own outcomes, and what evidence leadership will require before it spends more. Executive summary, the consultants answer. My recommendation is straightforward. To deploy Microsoft, 365 Co-pilot in phases, don't treat it as a tenant-wide license event. Start with a small number of business scenarios where work is repeatable, the process has a clear owner, the data risk is understood, and you can measure the result. At the same time, assess identity, data access, information structure, governance, security controls, and the support model needed to run this as an enterprise service. That sequence matters. Most Co-pilot programs don't fail because users can't open the app. They stall because the organization hasn't decided what good looks like, who owns the risk or how it will prove value beyond people saying they like the tool. The biggest risk is existing oversharing. Co-pilot respects permissions. If someone can access a file, co-pilot may use that file as context for that person. So your permission model becomes your AI access model. Old broad groups, unmanaged guest access, stale sites, and unclear ownership don't become less relevant because AI arrives. They become more visible. Here's the trade-off. You can move fast by limiting the initial scope using low-risk cohorts and control data sources when you repair the wider estate. Before you can attempt broad access immediately and accept that governance debt will arrive during the rollout when the cost and pressure are much higher. The biggest opportunity is not AI productivity in the abstract. It's reducing time lost in repeatable knowledge work, preparing for meetings, finding the current version of a policy, turning a long email chain into decisions and actions, creating a first draft from approved material. Pulling together a project update from information that already exists across Microsoft 365. Those are useful scenarios because they connect co-pilot to work that people already do. A good deployment produces measurable workflow gains, control expansion, and a spend that leadership can defend. It also produces something less visible but more important, an operating model for the next wave of AI capabilities including agents, connectors, and automation. You should expect some scenarios to fail. That's fine. A pilot should tell you where co-pilot helps, where the process needs repair, where training falls short, and where controls need tightening. If every pilot scenario succeeds, you probably select only the easy ones, which is not the same as proving you can scale. So let's zoom out. Leadership in IT often look at the same co-pilot deployment and see different problems. Until those views meet in one business decision, the technology discussion stays noisy. Why co-pilot projects start now? Co-pilot projects rarely begin because an organization woke up one morning with a perfect AI strategy. They begin because the board asks what the company is doing with AI, employees are already trying public tools, and competitors are talking about faster service, lower cost, and more productive teams. The pressure is real and doing nothing can look like a decision in itself. You may also have a quieter problem. People already spend large parts of their day looking for information, reading long email threads, turning meeting notes into actions, and creating first drafts from material that exists somewhere in the business. Those are not new problems. Co-pilot puts a very visible option in front of leadership to reduce that friction, but it changes the shape of the conversation. Your data is already spread across teams, SharePoint, OneDrive, and Exchange. A project decision may sit in a team's chat. The formal document may sit in SharePoint. The latest approval may exist in email. A person preparing for a customer meeting may have to piece all of that together manually, often under time pressure. This is where Microsoft 365 co-pilot can be useful. It works in the context of work already happening across the Microsoft 365 estate, rather than asking users to move content into a separate AI tool every time they need help. That convenience is also why the deployment decision carries weight. A standalone chat tool can be useful for generic drafting or public research. Co-pilot's business case is different. Its potential value comes from helping people work with the document's conversations, meetings, and relationships that already shape their daily decisions. So leadership sees an opportunity to reduce friction in knowledge work. They want to know whether proposal teams can respond faster, whether managers can spend less time assembling status reports, whether sales teams can prepare for customer conversations with less manual research, whether employees can recover time from meetings that create more follow-up than progress. Those are fair questions. It sees the other side of the same promise. More usage means more demand for help, more questions about what co-pilot can access, more pressure on identity controls, and more concern when an answer draws from content that a user did not realize they could reach. Security teams don't want vague reassurance. They want to know which controls apply, what evidence exists, who reviews exceptions, and what happens when something goes wrong. Violence has a different concern. Should every employee receive a license? Or should licenses go first to roles where the work pattern and potential benefit are clear? A broad rollout can create momentum, but it can also create a large recurring cost before the organization has proved that work actually changed. Here's the trade-off. Targeted licensing gives you more control and clearer evidence, but it can create frustration among employees who want access. Broad licensing creates a sense of fairness and speed, but it often turns the value discussion into an argument about usage reports rather than business outcomes. In practice, both approaches can work. The choice depends on what you're trying to learn first. If your immediate goal is to prove value, start where there's a defined workflow and an accountable business leader. If your goal is broad AI literacy, you may choose wider access, but you still need a way to separate exploration from measurable business benefit. The real question is not whether co-pilot has useful features. The real question is, what business decision you are trying to improve, what work you expect to change, and what proof leadership will accept before you expand? Until that is clear, technical readiness becomes a checklist without a purpose. Executive strategy to find the business decision. Before you assess the tenant, define the decision. Why are you deploying co-pilot in the first place? Not why the board thinks AI matters. Not why Microsoft has put it on every roadmap. What change is in the business? If this deployment works? If the answer is, we want people to be more productive, you haven't defined a decision yet. You've described a hope. Useful strategy starts with a specific business problem. Maybe proposal teams lose too much time finding prior content and turning it into a first draft. Maybe managers spend too much time after meetings chasing actions across email and teams. Maybe service teams can't find the latest approved answer while a customer waits. Those are different problems. They need different owners, measures, controls, and rollout plans. The first task in a consulting engagement is to separate demand from value. Lots of employees may want co-pilot. That tells you there is interest. It does not tell you whether organization should invest first. You need an executive sponsor who can make decisions across the business, not just approve a budget. This person needs enough authority to bring business leaders, security, finance, legal HR, and IT into the same conversation when the trade-offs get uncomfortable. A CIO can sponsor the platform. That makes sense. But if the CIO is the only sponsor, the project can quickly become an IT rollout with a business audience. Then IT owns the license count to the support queue and the risk while business leaders wait for someone else to explain the value that model rarely holds. The sponsor needs to ask business leaders a more direct question, where do you have work that is repeated often enough, painful enough, and clear enough to improve, start, there? A good initial scenario has a known process, a group of users who perform it often, and an accountable leader who can say whether the work improved. It also has a baseline. Without one, every claim after launch becomes opinion. Consider a sales or bid team that repeatedly prepares responses from approved company material. The potential benefit may come from faster discovery, faster first drafts, and less time recreating content that already exists. But you still need to know how the team works today. How long does it take to prepare a first response, where does rework occur? Who approves the output? Does faster drafting improve the time to submit? Or does it simply move the waiting time to another stage? That brings us to the real trade-off. Copilot can reduce effort within a task, but reduced effort does not automatically create financial return. If people save time but use it to absorb more work, improve quality or reduce delays, that may still be worthwhile. But you need to state which outcome you expect and who will turn recovered capacity into business value. Otherwise, the ROI model becomes a time sheet fantasy. Everyone has seen those. They look excellent in a steering pack and disappear when finance asks where the money went. Your strategy should name a short portfolio of scenarios, not a long wish list. For each scenario, document the business owner, user group, current workflow, expected change, data sensitivity constraints, and the measure that will decide whether it continues. You also need decision rights who can approve a new pilot scenario. Who accepts a risk that cannot be fixed before launch? Who decides that a department receives more licenses? Who can stop a scenario if it creates poor output, weak adoption, or an unacceptable control issue? These decisions shouldn't sit in a vague working group. A working group is useful for coordination. It is not useful when someone needs to say yes, no or not yet. In practice, I would expect the first strategy deliverable to include an executive AI strategy, a scenario portfolio, and a clear record of decision rights. It should fit on pages that senior leaders will actually read while linking to the detail that delivery teams need. Keep the strategy practical. It should state what you will do first, what you will not do yet, what evidence you need before expansion, and what conditions would make you stop. That last part matters. A deployment plan, without a stop condition, is usually a spending plan wearing a project badge. You're not trying to predict every future co-pilot use case. You're building a way to make good decisions as those use cases arrive. Strategy without a view of readiness becomes a wish list. Next, you need to test whether the environment can support the business promise you've just made. Success criteria and the investment case. Once you have a scenario portfolio, you need to decide what success means before the first license is assigned. This sounds obvious. It rarely happens with enough discipline. Teams often start with a broad claim such as, "Co-pilot will save time." Then they look at usage after launch, collect a few positive comments, and call the pilot a success. The project team has no shared answer. Start with the outcome, not the tool activity. For each scenario, define the business measure that should move. That might be the cycle time for creating a customer proposal. It might be the time between a meeting and a agreed action plan. It might be fewer hours spent finding approved policy content. In a service team, it may be faster response times with no drop-in-quality or compliance. Time saved matters, but it isn't enough on its own. If a manager saves 30 minutes each day and spends it answering more email, you may have improved their day. You haven't automatically created a financial benefit. If that same time lets the manager handle more customer work, reduces the need for overtime, speeds a decision, or improves the quality of a controlled process, then you can begin to build a credible investment case. That distinction needs to be explicit. Ask the business owner. If we recover this capacity, what will change? If they cannot answer, don't claim a hard financial return. Record it as a productivity or employee experience benefit instead. Those benefits can still justify investment, but they should not get dressed up as cash savings because that makes the whole case weaker. You also need a baseline. Before the pilot starts, observe the current workflow. Don't rely only on what people remember. Measure a sample of real work. How long does the task take from start to finish? How much of that time involves searching, drafting, checking, waiting for approval or correcting mistakes? Where does work get stuck? How often does someone redo it because the first version was incomplete or based on old information? This is where consultants slow the room down. A workflow that appears to take two hours may contain 20 minutes of actual effort and 100 minutes of waiting. Co-pilot may improve the effort, but it won't fix an approval queue, unclear ownership, or a process that requires three people to revise the same document because nobody agreed on the source of truth. Measure quality as well. For a proposal scenario, quality might mean fewer factual corrections, less rework from reviewers, and a higher rate of on-time submissions. For meeting follow-up, it might mean action items with a named owner and due date confirmed by the meeting lead. For information retrieval, it might mean users can find approved content faster without relying on informal messages or outdated copies. Then separate leading measures from outcome measures. Leading measures tell you whether people are using the scenario in the intended way. Are pilot users returning to co-pilot for the task? Are they using it within the relevant apps? Are they completing the enablement? Are managers reinforcing the new workflow? Outcome measures tell you whether the work changed. Did cycle time fall? Did quality hold or improve? Did the team increase throughput? Did customer response improve? Did operational risk reduce? You need both. A group can use co-pilot heavily and produce no business result. Another group may use it less often but gain real value in a high friction task. Prompt counts and chat activity can help you understand engagement, but they are not the investment case. For every scenario, define three decision points before launch. First, what would make you continue? Second, what would make you expand? Third, what would make you stop or remediate before spending more? Make these conditions concrete. For example, expansion may require that a scenario meets a target for cycle time improvement, maintains agreed quality levels, shows repeat use among the pilot group and has no unresolved control issues. A stop decision may follow if output quality creates too much rework if users do not change the workflow after proper support, or if the scenario depends on data that cannot yet be used safely. That creates a disciplined business case. Your initial ROI model should show the full cost, not just the license. Include enablement support, measurement, governance work, and the time needed from business leaders and pilot users. Finance should be able to see each assumption, challenge it, and understand what needs to happen for the forecast to hold. The deliverables here are a KPI framework, an initial ROI model, and an executive success charter. Together, they define the evidence you will collect and the decisions that evidence will support. Now you can test whether the tenant can support the promise. AI readiness assessment scored a real starting point. You now have a business case, a scenario portfolio, and a clear view of the evidence you need. The next question is less comfortable. Are you actually ready to run the pilot you designed? Not? Do we own Microsoft 365? Not? Can we assign licenses? The question is whether your current environment can support the specific scenarios you want to test without creating a voidable risk, poor user experience, or operational work that nobody planned for. An AI readiness assessment should not become a workshop where every team rates itself highly because it owns a tool. That happens more than people admit. Security says conditional access exists. Collaboration says SharePoint has governance. Identity says MFA is deployed. Each team says the data is in Microsoft 365. Each statement may be true, but none of them answers whether the controls work together for the people, data, and workflows entering the pilot. Readiness needs evidence. You assess identity, data access, information architecture, governance, security, post-year operations, and adoption capacity. Then you compare the result against the scope you intend to launch. A tenant may be ready for a controlled pilot with a small group using approved sites while being nowhere near ready for a broad enterprise rollout. Those are two different decisions. Start by defining the assessment boundary. Each business scenarios are in scope, which user groups will receive licenses, which regions are involved, which collaboration spaces contain the information they need, which systems sit outside Microsoft 365 that may affect their work. Without a boundary, the assessment becomes a massive enterprise cleanup program. That can be useful, but it will delay every practical decision. Your goal here is to find what could prevent a safe, useful pilot, and what needs a longer remediation plan. Think of a typical enterprise that wants co-pilot to help project managers prepare status updates. Access every document in every sharepoint site. You would assess the sites, teams, mailboxes, access patterns, and users tied to that workflow. Then you would identify what must change before the pilot, what can be monitored during it, and what must remain outside the initial scope. That is risk-based assessment. For each domain, ask three questions. First, is there a hard blocker? A hard blocker means you should not proceed with the planned scope until the issue is resolved. An example might be a user population without the identity controls your security policy requires, or a pilot scenario that depends on locations with unmanaged access and no accountable owner. Second, is there a manageable gap? This means the pilot can proceed if you narrow the scope, put a temporary control in place, or assign a clear remediation owner with a deadline. Third, is this an accepted risk? Some gaps will not be fixed before the pilot. That is normal, but someone with the right authority must accept the risk, understand the impact, and agree to the boundary around it. Accepted risk is not the same as ignored risk. One has an owner. It comes a surprise. A useful scorecard does not hide behind one maturity number. A single score may look tidy in an executive slide, but it can conceal the real issue. You might have strong identity controls and weak data ownership. You might have solid security tools, but no operational process to handle user questions, exceptions, or incidents. A green average can hide a red problem. Score each area by business impact and exposure. If a low-risk scenario uses a limited content set with named owners, an information architecture gap may be tolerable for the pilot. If the same gap affects sensitive commercial data across thousands of sites, it carries a different weight, context decides the rating. The assessment should also test the difference between policy and practice. A policy may require site ownership, but how many sites actually have an active owner? A standard may require labels, but do users apply them in ways that reflect how the business works? A governance forum may exist, but can it make a decision within the pace of a pilot? This is where the real starting point becomes visible. By the end of this phase, you should have an AI readiness scorecard that lists the assessed areas, evidence reviewed, risks found, business impact, current control state, remediation priority, and named owner. It should make clear what you can launch now, what needs repair first, and what remains out of scope. Would you approve your pilot based on that scorecard? If the answer depends on verbal reassurance from three different teams, you are not ready yet. If it shows clear boundaries, owned gaps, and evidence that the intended scope can operate safely, you can move forward with confidence. The next area deserves close attention, because identity decides who co-pilot can act for and what it can reach. Identity, licensing, and core service readiness. Identity comes before co-pilot because co-pilot works in the context of a user. It acts on behalf of that user. It searches what that user can search. It brings together information that user can reach. So if identity is weak, the rest of the deployment sits on weak ground, start with EntraID health. You need to know whether your pilot users have strong authentication, whether conditional access applies in the way you expect, and whether device posture affects access to Microsoft 365 services. MFA should be a rollout gate. If someone can access co-pilot from an unmanaged or risky device without the controls your organization expects, fix that before you make the service available. Conditional access needs the same level of review. Many enterprises have policies that grew over time. There may be exclusions created for a business unit, a legacy application, a service account, or an urgent project from years ago. The policy still exists because removing it feels risky. That is understandable. It also means you need to know whether the pilot population falls into one of those gaps. Check privileged access as well. A co-pilot deployment does not create a new reason for weak admin practice. Review who can assign licenses, change access groups, alter sharing settings, or modify policies that affect the pilot. Use least privilege. Keep privileged roles separate from ordinary user accounts. Make sure emergency access accounts are governed, tested, and not quietly used as a normal workaround. That last one always sounds obvious until you find it in the logs. Then move to licensing. The technical task of assigning a co-pilot license is simple. The management decision is not. You need to confirm that each target user has an eligible based license and that your license assignment method matches the rollout model. Individual assignment may work for a small pilot. Once you move into controlled waves, group based licensing through enter ID security groups usually gives you more control, clearer ownership, and a better audit path. Build those groups around the business decision. Don't create a group called co-pilot users and let it grow without rules. Create groups linked to a scenario, a department, a region, or an expansion wave. Name and owner. State the entry criteria. State who can remove a user. This gives finance and IT a clean view of who has a license and why. You also need reclaim rules. What happens if someone changes role, leaves the organization, moves out of the pilot, or never uses the license in the agreed period? If you cannot answer that, your pilot becomes a permanent license pool by accident. Licenses should support a business scenario, not become a status symbol. Core service readiness comes next. Microsoft 365 co-pilot depends on services your organization may already run, but already run is not the same as ready for this use. Check Exchange Online mailbox readiness for the intended experience. Check team settings that affect meeting content and transcripts. Review SharePoint and OneDrive availability, user provisioning, and service health expectations. Microsoft Graph forms the context layer across these services. You don't need to turn this into a technical lecture. The point is simple. If the information that supports a workflow lives in Exchange, Teams, SharePoint, and OneDrive. The quality of access and service configuration across those places affects the experience people receive. Client readiness matters too. Review the Microsoft 365 Apps Update channel across your target devices. Co-pilot experience depends on supported versions and supported channels. A common problem appears when the organization has a cautious update policy, while the business expects new co-pilot capabilities immediately. That is a governance choice, not a product fault. Here's the trade-off. Current channel may give users access to capabilities sooner, but it demands a support model that can absorb faster change. Monthly enterprise channel offers a more controlled rhythm, which may suit organizations that need more testing and communication. What matters is that you choose deliberately and explain the implication to users. Hybrid identity needs special attention. A typical enterprise may have cloud identities. Synchronized on-premises identities, guest accounts, dominant accounts, shared mailboxes, service accounts, and more than one tenant due to an acquisition. Each of those can affect access, licensing, support, and audit evidence. This identity is deserved a direct review. Who sponsors them? Are they still active? What can they access? Are they in groups inherited from an old project? The same applies to dormant user accounts. An account that should have been disabled is not a minor housekeeping issue when access to enterprise data sits behind it. Don't license service accounts. Don't treat shared mailboxes like ordinary users. Don't assume every identity and enter ID belongs in the co-pilot population. You're deliverable is a technical readiness register and a licensing strategy. It should show service dependencies, identity gaps, update channel decisions, licensing groups, cost owners, and remediation actions with named people behind them. Service readiness gets users through the door. It does not fix poor information structure once they are inside. Information architecture, data quality, and technical debt. Once identity and service readiness are understood, look at the information people expect co-pilot to work with. The first question is simple. Where does work actually live? Don't ask where the policy says it should live. Ask where people go when they need the latest proposal, a decision from last month, a customer commitment, or the approved version of a policy. In many enterprises, the answer is spread across several places. The project team says one thing. A SharePoint library holds another version. A shared mailbox contains the latest approval. Someone's one drive has the working draft because the formal site became too hard to use. Co-pilot can help people work with the information it can find. It cannot decide which of five conflicting versions is authoritative just because one has a more confident file name. That's a data quality problem, but not in the narrow sense. This is not mainly about removing blank rows from a spreadsheet or enforcing folder names. It is about business context. Does the document state its owner? Is there a current version? Does it have a clear purpose? Can a user tell whether it is draft guidance, a historical record, or an approved operational standard? If the answer is no, co-pilot may retrieve content that looks relevant, but sends the user in the wrong direction. The output may read well. That doesn't make the underlying information right. Start the assessment by mapping the information parts for the pilot scenarios. If you want project managers to prepare status updates, identify where they collect project information today. If you want account teams to prepare for customer meetings, identify the approved sources they rely on. If you want HR to help managers answer policy questions, identify the policy sources that should be used and the old sites that should not. That gives you a practical boundary. Then look for the patterns that create confusion. Unknown sites are common. So are duplicate libraries, stale teams, old channels, copy documents sets, and shared mailboxes that have become a shadow knowledge base because nobody agreed where the real record belongs. Technical debt rarely arrives as one dramatic failure. It accumulates through sensible local decisions. A team creates a new site because the old one is crowded. A project keeps its team after it ends because deleting it feels unsafe. A shared mailbox stays active because it contains useful history. Over time, the organization builds a large volume of content without a reliable way to separate current business knowledge from old material. That changes the co-pilot decision. You do not need to clean the entire tenant before running a pilot. That approach can become a long delay with no end date. But you do need to decide what content is suitable for the pilot, what needs repair first, and what should be excluded until ownership and structure improve. Here's the trade-off. Broad access may increase the chance that co-pilot find something useful. It also increases the chance that it finds stale, duplicate, or poorly governed information. Restricting the initial scope can reduce the richness of the experience, but it gives you a more reliable basis for testing whether the workflow itself improves. Or an initial pilot, choose content areas with named owners, current material, and a clear business purpose. Isolate sources where ownership is unclear, where content has not been reviewed, or where conflicting versions create a real risk of poor decisions. Metadata can help, but don't turn it into a paperwork exercise. Use metadata where it helps users and systems distinguish content that matters. A document type, business area, owner, status, or review date may be enough. If you ask users to complete 20 fields before saving a file, they will find ways around it. In a consistent, it is a predictable response to friction. Naming standards matter for the same reason. They should make information easier to identify, not satisfy, an architecture diagram that nobody outside I.T. understands. Retention and records rules must also reflect the value and purpose of the content, because keeping everything forever does not create a better knowledge base. It creates more noise. At this point, produce an information architecture gap map and a remediation backlog. The gap map shows where the pilot workflow depends on trusted information, where that information lives, who owns it, and what quality issues affect retrieval. The backlog separates immediate pilot actions from longer term work, with priorities based on business impact and risk. Good information architecture reduces future decisions. Without it, users spend more time asking whether they can trust what co-pilot found. And the next phase is where that uncertainty becomes far more direct, because permission cleanup is the work most teams try to postpone. Data and permission cleanup find the exposure. This is the phase almost every organization tries to shorten. Someone will say, "Co-pilot doesn't give anyone new access, so why do we need a permission cleanup before the pilot?" Technically, that first part is correct. Co-pilot works within the permissions already assigned to the user. Operationally, it misses the point. The problem is not new access. The problem is that old access becomes far easier to use. A user may have had access to a document for years without knowing it existed. With co-pilot, they can ask a natural question and receive a summary that brings that document into their working context. That is why a permission review belongs before broad deployment. Start with the forms of access that create the largest exposure. Look for broadly shared share point sites. That grant access beyond the intended audience anonymous links where they remain allowed and folders shared from personal one drive locations. Review guest access with the same discipline. Every guest should have a sponsor, a business reason, a defined scope and an active end date or review cycle. If you cannot explain why a guest still has access, that access should not remain by default. Then look at inherited permissions. Inheritance is useful when a site has a clear structure and a stable membership model. It becomes a problem when people break inheritance to solve one urgent sharing request, then add direct permissions to folders, files and libraries over several years. Eventually, nobody can explain who has access or why. This is common. It is also manageable if you treat it as an evidence exercise rather than a cleanup campaign based on guesswork. Review the groups used to grant access. Look for names that no longer mean anything. Look for male enabled groups that have become de facto security controls. Look for groups with no clear owner. Look for large nested memberships and groups that still contain people who changed role, left the business or joined through an old merger. When somebody says, "We don't know what that group does, so don't touch it," record that as a risk. It is not a reason to leave the problem invisible. The same review needs to cover teams because teams membership often maps to the collaboration spaces and files behind the experience. Check private channels, shared channels, old project teams and external members. Also examine shared mailboxes and common workspaces where teams have stored sensitive operational knowledge outside the normal document management pattern. You are not trying to make collaboration difficult. That matters because permission remediation can become heavy handed very quickly. If IT removes access without involving the business, users will work around the controls. They will download files, send attachments, create new unmanaged spaces or keep copies where nobody intended them to sit. The better approach uses risk-based triage. Prioritize content that combines high sensitivity, broad reach, stale ownership and active business use. A public project site with low risk material may need attention, but it does not carry the same urgency as a poorly owned location containing commercial plans, employee information, legal material, source code or financial records. Ask four questions for each exposure. What data sits here who can reach it today? Who is accountable for deciding who should reach it? How actively is the content used that gives you a workable queue? The data owner decides the intended access model. The platform team helps apply it, security validates the risk, the project team tracks the outcome. This is where accountability stops being a policy word and becomes a real operating practice. You may find that the safest pilot choice is not to clean every issue before launch. Instead, limit pilot users to approved content areas while remediation continues elsewhere. That is a reasonable trade-off when the scope is controlled and the risk is clear. What you should not do is ignore broad access because the cleanup looks difficult. Would you approve an AI tool to summarize and connect information across these access parts if a user had never seen a clear list of what they could reach? That is the consultant checkpoint. If the answer is no, you have worked to do before expanding the scope. The output from this phase is an oversharing inventory, a remediation plan, and named owners for each material finding. The inventory should not be a giant export that nobody reads. It should show the exposure, the affected business area, the likely impact, the accountable owner, the required action, and the target date. Some issues will lead immediate correction. Others can sit in a controlled backlog. The difference should be visible, agreed, and defensible. Permissions answer who can access content today. To keep that access model from degrading again, you need durable controls around classification, sharing, and the life of the information itself. Labels, life cycle, and durable controls. Cleaning permissions, once, is not governance. Without durable controls, the same problems return. A new team gets created with the wrong sharing settings. A document moves into a less protected location. Someone shares a sensitive file broadly to solve an urgent request. Six months later, you are back where you started. Except the AI estate is larger. The labels help turn a permission decision into a repeatable control. But keep the model simple enough that people can use it under normal work pressure. Most organizations need a small number of labels that employees can understand without opening a policy document. Terms such as public, general, confidential, and highly confidential can work if your organization defines them clearly and connects each label to a real handling rule. The names matter less than the behavior they trigger. For example, a highly confidential label may limit external sharing, apply encryption, and require access to named people. A general internal label may allow normal internal collaboration but block public access. Users need to know what choice they are making and why. Too many labels create false precision. If an employee has to choose between 12 similar classifications before they can save a document, they will guess. Or they will choose the default every time. That is not a user failure. That means the control designers ask people to do work that the system should handle for them, start at the container level where possible. A SharePoint site, team, or Microsoft 365 group usually represents a business purpose and a group of people working together. Apply a container label that sets the expected privacy, external sharing rules, and default protection. Then derive file labels from that container by default. This reduces choices at the point of work. If a project site is confidential, new files in its main library should inherit that classification unless there is a justified exception. A user can still need a more restrictive label for a particular document, but the safe default should match the workspace. Every exception needs a path who can change a label. What happens if a file sensitivity conflicts with the site where it is stored? Can a user move a highly sensitive document into a general workspace? What review happens when a label downgrade affects encryption or sharing? These are not edge cases once you operate at scale. They are normal work. Design the route before users find the gap. Microsoft PerView can support this model through data loss prevention, auto labeling, review cues and quarantine actions. The point is not to switch on every policy and hope for the best. But with the data types that create the clearest business and regulatory exposure, such as credentials, personal data, financial information or protected source code. Use DLP to detect conditions that should not be handled by user judgment alone. If someone labels a file as general, but it contains access tokens or sensitive employee data, the control should flag it, block an unsafe action where appropriate, or send it to a review queue. In higher risk cases, quarantine may be the right response until the content owner, security team or compliance function can decide what happens next. And needs human ownership. A DLP rule can detect patterns. It may not understand that a code name refers to an unreleased product, or that a finance team has a legitimate reason to handle information that would trigger a standard policy. Define exception groups, escalation routes and response times. Otherwise, your controls either block real work or become ignored alerts. Then manage the life cycle of the spaces and information itself. Every active team and share point side should have a named owner. That owner should periodically confirm that the site remains needed. Since membership is still appropriate, it's labels still fits, and its sharing settings reflect the current business need. This is attestation. It sounds administrative because it is. It is also one of the few reliable ways to stop abandoned workspaces from becoming permanent data risk. Set a sensible review cycle. Some sites need frequent review because they hold sensitive content or have changing external membership. Others can follow a longer cycle. If nobody confirms ownership, have a defined route for notification, archive, deletion and recovery. Delete business content without a recovery plan and don't retain everything forever because nobody wants to make a decision. External sharing follows the same principle. Allow it where there is a business need but tie it to data sensitivity named accountability and review. A supplier collaboration site does not need the same rule set as an internal planning site. A highly confidential file should not travel through the same sharing path as a general working document. The deliverable is an information protection baseline and a life cycle policy set. It should show the label, taxonomy, default controls, exception process, DLP actions, ownership rules, review cadence and recovery process. Once those controls are in place, you have a way to keep the estate from drifting back toward unmanaged access. Permissions determine access today. Security addresses what happens when that access comes under attack. Security and compliance deploy AI safely. Security for co-pilot starts with a plain idea. You do not approve a new way of finding and using enterprise information based on a promise that users will behave perfectly. You design controls that verify identity, device, session and access context each time the service is used. That is zero trust in practice. A user's password is not enough. You need to know whether the sign in carries risk, whether the device meets your management standard, whether the user is in an approved location or network context, and whether the requested access makes sense for that account. MFA is the baseline gate. If a pilot user cannot meet your MFA standard, they should not receive access. There is no useful argument for treating that as an optional improvement after launch. Unmanaged access is where you apply the policy to real working conditions. You may allow co-pilot from compliant managed devices while limiting access from unmanaged devices. You may require stronger controls for users handling confidential data. You may block high-risk sign-ins or require a fresh authentication challenge when the context changes. The policy design must match how people work. A global sales team may need mobile access while traveling. A regulated back office team may require a managed device and a restricted session. If you apply one rule to everyone without understanding the work, users will either lose the ability to do their job or search for ways around the policy. Here is the trade-off. Titer controls can reduce exposure, but they can also create friction. The answer is not to weaken the controls until users stop complaining. It is to design different access paths for different risk levels and make those paths clear before the roll-out starts. Next, define how you will protect sensitive information during normal use. DLP should cover the data types that matter to your organization. That may include credentials, personal data, payment information, financial forecasts, regulated records, legal material, or non-public source code. The control question is specific. What should happen when sensitive content appears in a prompt, a response, a file, or a sharing action? Some cases need monitoring, some need a user warning, some need blocking, some need escalation. Do not treat all DLP events as security incidents. If every alert reaches the security team, the team will drown in noise and business users will wait for answers, set severity levels, define who triages each level, agree what evidence they need, how quickly they need to respond, and who can make an exception. Or it matters because co-pilot changes how users interact with information. You need to retain the records required by your internal policy, legal obligations, and regulatory environment. That includes being able to investigate an allegation, respond to an e-discovery request, and understand what activity occurred when a potential data exposure is reported. Be clear with employees about this. DLP pilot is not a private personal notebook. Prompts and responses can fall within your organization's retention, audit, and legal discovery obligations. This is not a reason to create fear. It is a reason to set honest expectations about professional use. Inside a risk needs the same maturity. The goal is not to watch every employee or treat normal work as suspicious. The goal is to detect patterns that suggest a meaningful concern, particularly when sensitive content, unusual access behavior, and risky actions appear together. Usually legal HR and privacy teams need an agreed path for handling those cases. No single team should improvise after an alert arrives. For global organizations, data residency and regulatory boundaries need an early decision. Where are your users? Where does their data need to remain? Do particular regions have local requirements, labor rules, works councils, or sector controls that change what you can enable and when? Multigio may be part of the design, but it does not remove the need to understand local obligations. Encryption also requires practical review. Know which content protection's effect, how information can be used in co-pilot scenarios, and test the behavior with your actual labels and policies. A control that exists only in a design document is not a control you can rely on. You also need an incident path for AI specific events. What happens if co-pilot produces harmful or misleading content that enters a business process? What happens if a user receives information they should not have been able to discover? What happens when a malicious prompt attempts to manipulate an AI experience through content? It is asked to process? Don't promise that these events cannot happen. Define how you detect, contain, investigate, communicate, and learn from them. For a pilot, run a tabletop exercise. Give the teams a realistic scenario, then ask who does what in the first hour? If the response depends on finding the right people in an emergency chat, the process is not ready. The deliverable is a co-pilot security assessment and risk register. It should state the controls you have, the gaps you accept, the threats you monitor, the people who own each response, and the evidence you retain. Security controls only work when they fit the architecture people will actually use. The real architecture, choose the deployment shape. At this point you've established the business scenarios, tested readiness, reviewed information risk, and set the security boundary. Now you need to choose the deployment shape. The question isn't whether you can add co-pilot studio, connectors, agents, and Azure AI on day one. You can. The real question is whether each layer solves a defined business problem that standard Microsoft 365 co-pilot cannot solve well enough. Start with the core co-pilot experience. For many early scenarios, standard co-pilot in the Microsoft 365 apps is enough. A manager needs help preparing for a meeting. A project lead needs to turn notes into a status update. A sales team needs a first draft using material it already owns. These are usually adoption and workflow questions before they become architecture questions. That keeps the first deployment understandable. Once you introduce custom agents, external connectors, automated actions, or Azure services, you add new dependencies, new support needs, new security parts, and new decisions about ownership. Every architecture decision creates a governance decision. Microsoft Graph is central to the core experience because it provides the permission-trimmed context across Microsoft 365. Put simply, it helps connect the work a user is doing with the content, people, meetings, messages, and files that user is allowed to reach. But permission-trimmed does not mean quality-trimmed. Co-pilot can respect the user's access rights and still retrieve content that is outdated, poorly named, duplicated, or irrelevant to the decision at hand. That is why search architecture deserves attention. You need to know what content is indexed, which sources should contribute to search, who owns each source, and how you will handle low quality or obsolete content. A useful architecture question is this. When co-pilot gives a user an answer, where should that answer come from? For an HR policy scenario, the answer should come from the current approved policy source, not a collection of old files, informal team chats, and documents from a reorganization three years ago. For a sales scenario, it may need approved product information, account material, and current commercial guidance. The source system owner needs to define that boundary. Connectors can extend access to information held outside Microsoft 365. That may be useful where a business process relies on a CRM, service platform, knowledge base, or line of business system. Here's the trade-off. A connector can make co-pilot more useful by bringing relevant context closer to the user. It can also bring another systems access model, data quality issues, retention rules, and operational risks into the co-pilot experience. Before you connect anything, ask who owns the source data, who approves its use, what users should be able to retrieve, and who supports it when results are incomplete or wrong. Don't connect the system because someone says all our data should be available to AI. That is not an architecture principle. It is a future incident report waiting for a date. Co-pilot studio and Azure AI have a place, but only after you prove a defined workflow needs more than the standard capability. Co-pilot studio may fit when a team needs a focused agent with clear instructions, defined knowledge sources, and perhaps a controlled action path. Azure AI may fit when you need more custom orchestration, integration, model choice, or engineering control, than the Microsoft 365 experience provides. Both can be good choices. Neither should become a side project where every department builds its own assistant with different rules, unclear data sources, and nobody responsible when it stops working. Start with the standard experience. Add complexity only where a scenario has measurable value, clear ownership, and controls that match the scope. The tenant and merger situations need extra care. A global enterprise may run more than one tenant due to acquisitions, legal separation, regional structure, or historical decisions. Users may expect co-pilot to work across those boundaries because their business work crosses them. The architecture may not support that expectation in the simple way they imagine. Be explicit about data boundaries. Define which tenant owns the service, where identities are managed, which content sources are in scope, and what users can expect across organizational lines. Do not let an acquisition integration problem hide inside an AI project. It will not become easier there. Your target architecture should be practical enough to operate. Document the standard co-pilot capabilities you will enable, the approved data sources, search and indexing assumptions, plan connectors, custom extensions, service dependencies, and support ownership. Keep a design decisions log. When someone asks six months later why a connector was approved or why an agent has access to a certain source, you should not need to reconstruct the answer from meeting notes. The deliverables are a target architecture, a dependency map, and a design decisions log. Good architecture reduces future decisions. It gives teams a clear default path, a defined exception path, and a reason to say no when a request adds complexity without adding enough business value. That brings us to the next decision, how you control the cost of the architecture and the licenses that sit behind it. Licensing strategy and cost controls. Licensing is where a sound co-pilot strategy can quietly turn into an uncontrolled operating cost. Easy move is to buy broadly, assign widely, and hope usage grows into the spend. That may satisfy initial demand but it removes the discipline you need to prove where co-pilot changes work and where it simply becomes another unused entitlement. Start with the business scenario, then assign the license. A role does not automatically justify a co-pilot license. Two people with the same job title may work very differently. One may spend much of the week preparing documents, reviewing customer context, and running meetings. Other may work mainly in a specialist system with limited use for Microsoft 365 co-pilot. Treat licenses as an investment in a work pattern, not a benefit attached to a title. For the first waves, targeted licensing usually gives you the clearest evidence. You can connect each license group to a scenario, a business owner, expected use, and defined measures. If a department wants more licenses, ask them to identify the workflow, the accountable manager, and the outcome they expect to improve. That isn't bureaucracy for its own sake. It stops the role out becoming a queue of people asking, why do they have it and I don't? The answer should not depend on seniority, enthusiasm, or who asked first. It should depend on the current expansion criteria and whether the role fits a proven scenario. Broad licensing has a place. If your organization wants to build broad AI fluency, or if a large population has similar knowledge work patterns, wider access may be sensible. But price the decision honestly. The total cost is not the co-pilot line item alone. The base Microsoft 365 licensing position, enablement time, support capacity, governance activity, permission remediation, platform administration, reporting, and the time business team spend changing their work. A license that costs a fixed monthly amount may create several times that cost in the first year when you include the work required to make it useful and safe. That is not an argument against deployment. It is an argument against presenting procurement cost as the whole investment. Finance should be able to see the full model show the direct cost per licensed user, show shared platform and governance costs. Then allocate the costs to departments where that supports accountability. Some enterprises use chargeback where the department pays for licenses in related services. Others use showback where central IT pays but reports consumption and costback to each business unit. Here is the trade-off. Chargeback creates stronger local ownership, but it can slow adoption if leaders protect their budgets until every benefit is proven. Showback reduces that barrier, but departments may treat licenses as free and hold on to them long after the business case has faded. There is no universal answer. Choose the model that matches how your organization funds digital services, then make the rules visible. You also need an assumption about demand. Some leaders expect licenses to behave like a shared pool. A person uses co-pilot this month, then someone else uses the same seat next month. That may not match how the service is licensed or how the user experience needs to work. Don't build a financial forecast on pool demand unless your procurement terms and operating models support it. Model renewal exposure early. If the pilot expands, user rises unevenly or the organization commits to a larger volume before the benefits realization plan is mature. Set review points before renewal or major expansion decisions. Those reviews should assess scenario outcomes, active use, support demand, control findings and the remaining cost to scale. Unused licenses need an agreed response. Set a reasonable review period, look at whether the user belongs to an active scenario, whether they received role-based support, and whether a manager still expects the role to use co-pilot. Then reclaim, reassign or retain the license with a documented reason. Don't use activity alone as the test. A user may have low visible activity but gain value in a periodic high impact task. But don't let that become a blanket excuse either. The manager who owns the scenario should be able to explain the expected value. Your deliverables are a licensing strategy, financial controls and a 12 month cost forecast. They should show how licenses are assigned, who owns the spend, when usage and value are reviewed, how licenses are reclaimed and what triggers the next investment decision. Technology and licenses still need someone accountable for the decisions that follow. Governance, build the co-pilot operating model. A license strategy tells you who receives co-pilot and how you control the spend. Governance tells you who makes decisions after the license is active. This is really a governance decision. Co-pilot touches business work, enterprise data, security controls, legal duties, employee concerns and departmental budgets. If one team owns all of it, decisions either become slow or they happen outside the process. Neither is a good operating model. Just by naming the account abilities, the CIO or digital leader usually owns the platform, outcome and the service model. The CISO owns the security bar and security risk decisions. Data owners decide whether their information is fit for the intended business use. Legal, privacy and compliance teams define the obligations that apply to prompts, outputs, records and regional requirements. HR helps shape employee guidance, training boundaries and concerns about work change. Finance owns the financial discipline, not the value claim itself. Business leaders own that. They must identify the workflow, nominate users, validate the result and explain what changed in the business after co-pilot entered the process. That last part is where many operating models fail. It can make co-pilot available. It cannot decide whether a sales proposal is better, whether a caseworker has made a sound decision or whether a department has redirected saved time into work that matters. The business leader has to own those outcomes. Put this into a clear responsibility model. You can use RATSI if your organization already works that way, but the format matters less than the clarity. For each decision, identify who recommends, who approves, who must be consulted and who needs to know after the decision. Keep the steering committee small enough to decide. A steering committee with 20 people may represent every interest, but it rarely resolves a problem. Build a group with actual decision rights across business, IT, security, risk, legal or privacy, finance and adoption. Meet at a set cadence during the pilot and expansion phases, then adjust once the service becomes stable. Its job is not to review every prompt or approve every user request. It should decide on expansion waves, material risk acceptance, policy exceptions, high impact agent proposals, budget changes and issues that cannot be resolved within the delivery teams. Give it an escalation path with defined response times. If a business unit finds a serious access concern, everyone should know who receives it, who assesses it and who can pause the relevant scope. Then define the AI policies people will actually use. Your accepted use policy should state what employees can do with co-pilot, what still requires human review, what types of data needs special care and what behavior is not allowed. Keep the language direct. Use professional judgment and follow company policy may be true, but it doesn't help someone deciding whether they can use a generated summary in a customer response or an internal management decision. Specify the moments where human review is mandatory. That may include regulated communications, employment decisions, legal advice, financial commitments, customer facing content or outputs used in high impact operational processes. The point is not to ban useful work. Just to make clear that co-pilot can support judgment without replacing accountable judgment. Agent boundaries need their own policy. A simple agent that retrieves information from approved sources has a different risk profile from an agent that writes to a system, sends a message, creates a record, or triggers a workflow. Define which agents users can create for themselves, which need business owner approval, and which need formal security, privacy and technical review before publication. Every architecture decision creates a governance decision. An agent with a connector creates a question about data access, an agent with an action creates a question about authority. An agent shared across the department creates a question about support, life cycle and ownership. Write the rules before the agent catalog becomes a museum of abandoned experiments. Separate enterprise standards from local playbooks. The enterprise should set the non-negotiables. Identity controls, data handling rules, audit expectations, security review, retention and approval paths. A local team can define how co-pilot supports its own workflow, what examples it trains on, and what quality checks make sense in that work. That gives you control without forcing every department to work the same way. The risk register needs a named owner for every material item. Not IT, not the program, a person or accountable role. That owner tracks the mitigation, reports progress and brings the issue back to the steering committee when the risk changes or the deadline slips. Policy exceptions need the same discipline, record what is being accepted, why the business needs it, what compensating control applies, who approved it and when it expires. Permanent exceptions are often temporary decisions that nobody revisited. Finally, test the controls. Run regular reviews of access, policy compliance, agent ownership and unresolved risks. Test whether escalation works under pressure. Test whether local teams still follow the enterprise rules after the launch attention has moved elsewhere. The deliverables are a governance framework and a co-pilot operating model. They define the people, decision rights policies, review routes and control checks that allow co-pilot to operate as a business capability rather than a collection of licenses. Governance becomes real when the pilot tests it under normal work pressure. Pilot design, prove a business scenario. The pilot is where your strategy, controls, architecture and governance model meet normal work. That's why a pilot should never exist to prove that co-pilot can write an email, summarize a meeting or produce a first draft. Everyone already knows it can do those things. The pilot needs to prove something more useful. Whether defined business scenario can operate safely, people will use it in real work and the outcome justifies the next level of investment. Start with a business scenario, not a department. Let's pilot co-pilot with finance is too broad. Finance contains many workflows, data types, approval rules and risk levels. A stronger pilot state when sounds like this. We will test whether account managers can prepare customer meeting briefings faster using approved account information while maintaining the same quality standard. It gives you a workflow, a user group, a source boundary, a business owner and a measure. Choose departments where three conditions exist. The work should repeat often enough to measure. The leader should be willing to change how the team works, not just distribute licenses. And the data risk should be manageable within the controls you have already tested. A pilot group also needs variety. Do not fill it only with enthusiastic early adopters. They will find value because they enjoy testing new tools and that is useful feedback, but it does not show how the broader workforce will respond. To do it confident users, cautious users, experienced users and people who are busy enough to reject anything that adds friction. That mix gives you honest evidence. Decide the pilot duration before launch. It must be long enough for people to move beyond first week experimentation and use co-pilot during routine work, but short enough that the pilot cannot drift without a decision. Define the license count, the entry and exit process, the support route and the user commitments. In practice, users should know what is expected of them. They are not being asked to become AI experts. They are being asked to test a small number of agreed work patterns, provide evidence about what helped or failed and raise concerns quickly. Managers have commitments too. They need to protect time for enablement, reinforce the selected scenarios in team meetings and validate whether the work output improved. If a manager delegates the pilot to IT and never looks at the workflow again, you will collect activity data without business evidence. Write acceptance criteria before the launch communication goes out. For each scenario, define the control criteria, adoption criteria and business criteria, control criteria may require that no unresolved access issue appears in the approved scope. Adoption criteria may require a meaningful share of the pilot group to return to the scenario over several weeks. Business criteria may require improved turnaround time, reduced rework or better completion of follow-up actions. Don't set criteria that only reward good news. A pilot must have a legitimate path to stop. If the data sources are unreliable, if users cannot fit the process into their work, or if the quality check shows added rework, stopping or redesigning the scenario is a sound result. It prevents a weak pattern from becoming an enterprise standard, build feedback into the operating rhythm, each week collect user evidence. Ask what task they attempted, what source material they used, what result they received, what they changed before using the output, and whether the result altered the time, quality or confidence involved in the work. Avoid vague questions such as, did you like co-pilot? People may like it and not use it. They may dislike parts of it while still gaining real value. You need evidence tied to the workflow. Bring managers, security representatives, support leads and the executive sponsor into a regular review cadence. Managers report business observations. Support reports recurring friction, security reports control findings and unusual events. The sponsor resolves decisions that the delivery team cannot make, especially wear scope, budget, or risk acceptance changes. Keep executive reporting brief and decision focused. Throw the scenario, the baseline, the current evidence, the open risks, the user feedback pattern, and the decision needed. Do not bury the steering group in screenshots, prompt examples, or feature lists. They need to know whether the scenario is safe, useful, repeatable, and ready for the next step. Your pilot playbook should bring all of this together. It defines the user's workflow, scope boundaries, support path, data sources controls, measures, feedback routine, and exit criteria. Parade with an executive reporting pack that makes the current state visible without requiring a forensic review of project documents. Before you approve launch, ask one final question. If this pilot succeeds, do you know exactly what you will repeat for whom, under which controls and with what evidence. If you cannot answer that, you are running a product trial. A successful pilot produces a repeatable expansion decision. Pilot review, decide expand, fix, or stop. The pilot ends with a decision meeting, not a celebration meeting. That distinction matters because a pilot can feel busy, get good comments from users, and still fail to justify expansion. Your job is to compare the evidence against the baseline and the success criteria you agreed before anyone received a license. Start with the workflow result. Did the selected team complete the work faster? Did quality stay the same or improved? Did rework fall? Or did people spend the time they saved checking and correcting output? Did the process become easier to follow? Or did co-pilot create another step that people avoided when deadlines became real? Look at the evidence across more than one source. Use workflow samples, manager review, support cases, user feedback, and the control findings from the pilot period. A user saying this save me time is useful. It is not enough on its own. You need to understand which task changed, how often it changed, and whether that change can repeat across the next group, then separate the cause of every shortfall. A weak result may come from a product limitation. It may come from a poor workflow design. It may come from old or conflicting source content. It may come from weak training, unclear policy, or a support route that users could not navigate. These are different problems, and they need different responses. If co-pilot produced weak answers because the approved source material was incomplete, buying more licenses will not solve it. If users struggled because the training showed generic examples rather than their real work, that is an enablement issue. If a controlled blocked a valid business task, the question is whether the policy needs refinement, not whether the user should find a workaround. This is where experienced teams avoid blaming the tool for every problem, document each finding in a practical form, state what happened, what caused it, who owns the response, and whether the issue affects the current scenario, the next expansion wave, or the wider operating model. Some findings will change policy, others will change architecture, support guidance, training material, or the scope of the next pilot. Not every scenario deserves another round. A scenario should move forward when it shows repeatable business value, acceptable risk, and a workable support model. It should end when the workflow has no clear benefit. The data quality cannot support the intended use, or the cost of control exceeds the likely return. Stopping a weak scenario is not failure. It protects the enterprise from scaling a pattern that looked good in a demo, but adds little under normal work conditions. Frankly, that is a cheaper lesson than discovering the same thing after thousands of licenses are assigned. The executive decision should have four possible outcomes. Expand when the evidence meets the agreed criteria, and the next group is ready. Extend the pilot when the scenario still has promise, but needs more evidence within a clear time limit. Remediate when the business case holds, but a defined control, data, workflow, or training issue needs correction first. Stop when the scenario does not justify further spend. Each outcome needs a written decision, named owner and next date. Avoid language such as, let's keep exploring. That usually means nobody wants to make the call. A pilot that continues without a change scope, a new question, or a decision gate becomes a standing experiment with a monthly bill. Your pilot closeout report should show the original hypothesis, baseline results, unresolved risks, lessons learned, changes required, and scale recommendation. It becomes the evidence pack for the steering group and the starting point for the next wave. The next question belongs in that review, would the next group receive a better deployment because of what this pilot taught you? If the answer is no, you collected feedback but did not learn. A pilot only earns its cost when its lessons change the next decision. The next challenge is making sure a scenario that worked for one team becomes part of normal work rather than fading after launch week. Adoption and change management make it part of work. A pilot can prove a workflow. It cannot create a habit across an enterprise. Once you move beyond the pilot, the work changes. You are no longer asking whether a defined group can use co-pilot safely and productively. You are helping people change how they prepare, communicate, search, draft, review, and make decisions during a normal week. Technology is rarely the hard part. People need to know what is changing, why it is changing, what remains their responsibility, and where the boundaries sit. If they hear only that the organization has rolled out AI, they will create their own story. Some will assume their role is at risk. Others will assume every output is correct because it came from co-pilot. A few will use it aggressively, then lose trust after the first poor result. Your communications need to get ahead of all three reactions. Executive communication should focus on work, not product excitement. A leader should explain the business reason for the rollout, the scenarios in scope, the expected use, and the standards that remain in place. Say clearly that co-pilot supports employee judgment. It does not remove accountability for a customer response, an approval, a policy decision, or a regulated outcome. People also need to know what the organization expects from them. They should understand which data handling rules still apply, when they need to verify output, how to raise a concern, and where to get help. Keep this direct. An acceptable use policy hidden in a long portal page does not change behavior during a busy afternoon. The message from leadership should also be honest about the limits. Co-pilot will sometimes give an incomplete answer. It may use a source that needs checking. It may produce wording that doesn't fit the audience or the decision that is normal for this kind of tool. Employees need permission to challenge it, correct it, and decide not to use the output when it does not meet the standard. Then move from broad communication to role-based enablement. Generic training often begins with the interface, a list of features, and a few clever prompts. That may help people feel familiar with the tool, but it rarely changes work. A finance manager, project lead, HR advisor, sales executive, and service desk analyst, each need to see how co-pilot fits into a task they already own. Use their real working materials where policy permits. Show a project manager how to prepare a status update from approved meeting notes and project records. Show a sales team how to prepare for an account meeting without copying old material into an unapproved source. Show an HR team how to use co-pilot for a first draft while keeping mandatory review and approved policy sources in place. That is where training becomes workflow design. Prompt coaching belongs here too. Don't teach prompts as magic phrases that employees memorize. Teach people how to state the outcome they need, give enough context, point to the right source, and define the form of the answer they want. A useful prompt is often just a clear work request. Help co-pilot the task, the audience, the source material, the constraints, and the quality check. Then review the result. Employees already know how to brief a colleague. Prompt coaching helps them apply that same discipline to an AI tool. Build local champion networks but don't turn champions into unpaid support staff with an impressive title. A good champion translates between the platform team and the local team. They know the work well enough to identify useful scenarios. They can share practical examples, collect concerns early, and show peers how to use the tool without making it feel like a central IT campaign. Choose champions who are trusted, not simply the loudest volunteers. They need time from their manager, clear guidance, access to current materials, and a route to escalate issues. If people begin asking them security, policy, or technical questions they cannot answer, the support model needs to catch that quickly. Resistance also deserves serious attention. Some people will worry about job change. Some will worry that poor output will damage their reputation. Some will fear that usage data becomes a measure of effort or performance. Others will resist because their current process works and changing it feels like extra work with no clear return. Don't dismiss these concerns as fear of change. Address them in the open. Explain what data you collect and why. Separate adoption measures from individual performance management unless your organization has explicitly chosen another path and has dealt with the legal, HR, and labour implications. Show where human judgment remains required. Most of all make sure the first use cases remove friction rather than add another system people need to manage. Support needs layers. Support with self-service guidance for common questions, approved scenario examples, policy reminders, and short learning material, add office hours where users can bring real work questions, then define a clear escalation route for technical issues, access concerns, suspected data exposure, and policy questions. Every support asset needs an owner. Someone must keep guidance current when the service changes, when policies change, or when the pilot evidence shows that users misunderstand the scenario. Otherwise, your internal knowledge base becomes another stale source that co-pilot may eventually surface. There's a small irony in that, but it happens. The deliverable is a co-pilot adoption plan supported by a champion network and role-based playbooks. It should state who communicates, who trains, who supports, how feedback moves, and what teams do when adoption stalls make co-pilot part of work people already need to do. If it feels like an extra activity, it will disappear the moment the calendar gets busy. Adoption measurement and continuous learning. Once people begin using co-pilot in real work, leadership will ask a familiar question. Is it working? Be careful with the answer. Usage data tells you whether people open the tool. It does not tell you whether the tool improves the work. A rising prompt count can mean adoption is improving. It can also mean people are trying several times to get an answer they can use. Activity is a signal it is not proof. Start with a simple adoption view that shows active users, repeat users, and use by the relevant apps or scenarios. Look at the pattern over time. Did people use co-pilot once after training? Then stop. Are they returning to the selected workflow each week? Because one team have strong repeat use while another has almost none? Those differences matter more than a tenant-wide average. A low-use team may have received poor training. It may lack an obvious scenario. Its manager may not be reinforcing the new workflow. Or the team may be correct because co-pilot does not solve a meaningful problem in that part of the business. Don't assume every low adoption number is a user problem. Ask what the users are actually doing. Are they using co-pilot to prepare for meetings, create drafts, find information, or reduce follow-up work? Or are they only experimenting in chat, trying prompts once and moving on? This is the distinction between exploration and changed behavior. A consulting team tracks the behavior that connects to the business scenario. If the scenario is faster customer meeting preparation, measure whether account teams use the approved sources and whether their preparation process changes. If the scenario is reducing project follow-up effort, measure whether teams use the agreed process and whether action tracking improves. You don't need surveillance to do this. Use sampled workflow reviews, manager feedback user interviews, support trends, and aggregated service data. Employees should understand what you measure, why you measure it, and what you will not use it for. If they believe every interaction becomes a personal performance score, they will either avoid the tool or use it in ways that distort the evidence. Keep the measurement focused on learning. Pure learning helps here because people often trust a practical example from someone doing the same job more than a central training session. Get a route for teams to share what worked, what failed, and what they changed in their process. The useful examples are specific. Not copilot helped me save time. Instead, I use this approach to prepare a briefing from these approved sources. I still check these parts manually. It removed this step from my process but it did not replace this review. That kind of evidence gives colleagues a pattern they can test. Managers also need a regular review point. They should ask whether the chosen workflow still makes sense whether users have adopted the agreed practice and whether the quality or risk controls need adjustment. This should sit inside normal operational conversations where possible. Not become a separate monthly ritual that disappears when priorities change. Training cannot be a one-time event because the product, policy, and work itself will change. Refresh guidance when new capabilities alter what users can do. Update it when a security rule changes. Rework it when evidence shows that users misunderstand a source boundary, skip a review step, or keep asking the same question through support. Treat each recurring problem as a learning backlog item. In the issue, identify the affected scenario, decide who owns the fix, and test whether the revised guidance changes behavior. Some fixes will be a short prompt example. Others will require a policy clarification, a better source of truth, or a change to the workflow itself. The deliverable is an adoption dashboard and a continuous learning backlog. The dashboard shows where behavior is taking hold. The backlog shows what the organization will improve next. Together they stop adoption reporting from becoming a monthly count of clicks with no connection to the work that changed. Now connect that usage evidence to financial and business outcomes. Measuring ROI build a defensible case. ROI is where many co-pilot programs lose credibility. Not because co-pilot cannot improve work, but because teams claim value before they define what value means. They count prompts, active users, or training attendance, then present that as a return on investment. Finance will quite reasonably ask a harder question. What changed in the business? Start with business KPIs tied to each scenario. If a commercial team uses co-pilot to prepare account briefings, measure preparation time, meeting readiness, follow-up speed, and perhaps the quality of customer response. If a project team uses it to reduce meeting administration, measure the time from meeting end to assigned actions, missed actions, and decision delays. The measure must belong to the work. Cycle time is often a good place to start because it is visible. How long does it take to turn a request into a first draft, a reviewed draft, or a customer response? Yet faster work is not always better work. Add a quality measure. Ask the manager or a sample reviewer whether the output met the existing standard, needed less rework or created new errors. Decision speed can also matter. A leadership team may spend days reconstructing context from emails, documents, and meeting records before it can make a routine decision. If co-pilot shortens that process while preserving sound review, the value is not merely time-saved. It can reduce delay in a project, customer issue, or operational approval. Customer experience belongs in the model where the scenario touches customers. You might measure response time, resolution time, consistency of communication or customer feedback. Don't claim that co-pilot improved customer experience because users like the tool show the link through the workflow. Technical KPIs have a different purpose. They tell you whether the service is being used in the way your scenario expected and whether the operating model can support it. Track active users, repeat use, relevant feature use, support demand, error patterns, and control events. A rise in support tickets is not automatically bad. During a new wave, it may show that people are engaging. The question is whether the same issues keep returning and whether the support model resolves them. Feature use also needs context. A department might use co-pilot chat frequently, but rarely use the app experiences tied to the scenario. That can tell you the workflow design has not taken hold. Or it may show that the scenario itself needs a different route. Don't force adoption into a feature just because the original plan expected it, then calculate the financial picture, start with full cost per user, not just the license, through the license cost, training, support, administration, governance work, security controls, and the share of remediation needed to operate the service responsibly. At department level show the local license allocation and the common service costs that support it. That makes the discussion more honest. Next, calculate capacity recovered. This is where teams often get ahead of themselves. If employees save 30 minutes a day, that does not automatically create 30 minutes of financial benefit. Deception pays the same salary unless it uses that recovered time differently. The real question is what happened to the capacity? Did the team handle more customer cases without extra hiring? Did it reduce contractor spend? Did it improve response times within the same headcount? Did people shift time from repetitive coordination into revenue work, quality checks, or project delivery? Or did the saved minutes simply disappear into the day? There is no shame in the last answer. It may still improve employee experience, but it is not the same as a hard financial return, build the model with visible assumptions. State the number of users in the scenario, the frequency of the task, the baseline effort, the measured change, the percentage of recovered time that becomes productive capacity, and the cost basis used by finance. If an assumption is uncertain, label it as uncertain. That is more credible than false precision. Use scenario level baselines before the rollout. Then validate the result with samples. Compare work completed before and after, while allowing for changes in demand, seasonality and team composition. Ask managers for evidence, but don't let manager opinion replace measurement. Investments should review the model before it reaches the executive group. A good business case has three views. The conservative case counts only verified cost avoidance or measurable throughput gains. The expected case includes validated capacity redirected into agreed business work. The strategic case may include softer benefits such as faster decisions or improved employee experience, but it keeps those separate from cashable savings. Here is the trade-off. Generic vendor studies can help you form a hypothesis. They cannot prove your organization's return. Your data estate work patterns, controls and adoption level are different. Use external research as context, not as the number you take to the board. The deliverables are an executive dashboard and ROI model and a benefits realization plan. The dashboard gives leaders a view of outcomes, cost, adoption, support and risk. The ROI model explains how the numbers were calculated. The benefits realization plan assigns owners to turn recovered capacity into an outcome the business can actually see. A good dashboard does not justify scale by itself. The scale decision depends on whether you can repeat the controls, the workflow patterns and the financial discipline across the next part of the enterprise. Scaling enterprise wide from hundreds to tens of thousands. Scaling co-pilot is not a larger version of a pilot. At 500 users, a central team can still know most of the use cases, answer many questions directly and intervene when something goes wrong at 50,000 users that model breaks. Request to arrive from every region. Policies meet local practice. Support tickets multiply. A small number of week controls can create a large operational burden. So scale through repeatable scenario clusters, not through one large license upload. A scenario cluster groups people who do similar work, you similar sources, face similar risks and can learn from the same playbook. It might include account teams preparing customer briefings, project managers converting meetings into actions or HR teams preparing internal communications under defined review rules. The expansion unit is not the whole department. It is a group with a known work pattern and accountable business lead, a support route and evidence from a prior wave that the pattern works. This gives you a way to expand without rebuilding the deployment from scratch every time. Global rollout adds decisions that local pilots can hide. Language is one of them. A prompt pattern that works well in English may need adjustment for local business language, document standards or cultural expectations. Training needs a local example, not simply translated slides. Support also needs people who understand the user's working context, not just the platform. Social policy differences matter as well. Data residency, local regulatory requirements, labor rules, privacy expectations and works councils may change the sequence of the rollout. In some regions, you may need more consultation before enabling certain capabilities. In others, local laws may affect which data sources monitoring practices or employee communications are acceptable. Don't treat this as a blocker to global scale, treat it as deployment design. Set a global minimum standard for identity, security, data handling, audit and governance. And let local accountable owners apply that standard within their legal and operating context. The global team should not guess how a regional requirement works. The regional team should not create a separate co-pilot policy because it is easier than working through the shared model. That brings us to ownership at scale. You need central coordination, but you do not need a central bottleneck. An AI center of excellence should provide standards, reusable assets, architecture patterns, controls, measurement methods and expert support. It should also identify issues that recur across the enterprise and turn those lessons into better guidance. It should not approve every routine request. If every license wave, training session and low-risk scenario needs central committee approval, the business will root around the model. Give local teams a clear path for standard scenarios. Reserve central review for exceptions, high-risk data, external connectors, agents with actions, regional regulatory concerns or material changes to the service. Think of the AI center of excellence as a coordination function. It sets the root, maintains the shared standards and watches for problems that cross organizational boundaries. Business units still own their workflows, data owners still own their data, security still owns security decisions, the center helps those groups move in the same direction without taking over their jobs. The support model has to mature at the same pace as the rollout. At enterprise scale, a single mailbox or team's channel is not a service model. You need tiered support. The first tier handles common, how-to questions, approved scenario guidance and access issues. Local enablement leads provide peer support close to the work. Platform operations handles service configuration, licensing and technical defects. Security and compliance teams own escalations, involving data exposure, policy breaches or suspicious activity. Vendor management also becomes part of the operating model. Track service changes, licensing changes, support commitments, known limitations and road map items that may affect your controls or training material. Product change moves quickly. A feature introduced into the tenant can alter user expectations before the operating model catches up, which is always a popular surprise for a governance team. Your expansion waves should have entry criteria. A regional business group enters when it has an accountable leader, a usable scenario set, required controls, local support coverage and capacity for enablement. It exits the wave review when it shows stable use, manageable support demand, acceptable risk and evidence that its chosen workflows are producing the expected outcomes. This creates a rolling enterprise rollout plan rather than a single launch date. Some groups will move quickly. Others will need time to resolve data, policy or organizational issues that is not inconsistency. It is risk-based delivery. The deliverables are an AI center of excellence blueprint and an enterprise rollout plan. The blueprint defines central and local responsibilities, decision routes, service layers and escalation parts. The rollout plan shows each expansion wave, its readiness criteria, its local owners and the support capacity required before licenses are assigned. As co-pilot reaches more of the enterprise, every shortcut taken in the first phase becomes easier to see. Continuous optimization and the 12 month road map. An enterprise rollout does not end when the last planned license wave goes live. That is usually when the more difficult work begins, because the service now has users with different needs, regions with different constraints and a steady flow of new co-pilot features, connectors and agent requests. We need a 12 month road map that makes those decisions deliberate for the first 30 days focus on the foundation. Confirm the executive strategy, complete the readiness work for the initial scope, prioritize the risks that can block the pilot and establish the control baseline. This is not the period for broad access. The main decisions in this first period are practical, which business scenarios enter the pilot, who owns each one which data sources are in scope. What permission risks need immediate remediation? What control evidence must exist before users begin normal work? By day 30 you should have a named sponsor, accountable business leads, a risk register and initial scenario portfolio and a pilot design that can be approved or rejected on evidence. From day 31 to day 90, run the controlled pilot and build the adoption system around it. This period is about testing the chosen workflows under normal business pressure. Users need role-based guidance, managers need to review whether the work actually changes, support teams need to see what users struggle with. Security and governance teams need to observe whether the controls behave as intended. Keep a decision gate at the end of this period. You are not asking whether people enjoyed the pilot. You are deciding whether the scenario should expand, whether a known gap needs remediation or whether the organization should stop spending on that use case. The difference is expensive. During months, fall through eight, expand through the scenario clusters that have already shown enough evidence. Do not widen scope simply because a quarter has ended and the roll-out plan needs a new number. Expand where the next groups meet the readiness criteria, where their work resembles the proven scenario and where local support can handle the change. This is also the period where regional readiness becomes more visible. Some locations will need local training, adapted materials, regional data decisions, or extra consultation before they move forward. Build those activities into the wave plan rather than treating them as late exceptions. Your support model should mature at the same time. The first waves often depend heavily on central experts because the questions are new. By the middle of the year, common issues should have clear self-service guidance, repeatable support procedures, and local champions who can handle the normal workflow questions. Central teams should spend less time explaining basic usage and more time addressing patterns, risks, and requests that need enterprise decisions. Months 9-12 are for optimization. Review license allocation against actual scenario outcomes. Reclaim licenses where the business case did not develop. Reassign capacity where demand and evidence are stronger. Update the financial forecast based on operating costs, not the assumptions you made before the pilot. This is also when agent opportunities become more credible. By now you should know which workflows have stable source material, clear business ownership, repeat use, and enough friction left that a focused agent might help. That does not mean every successful co-pilot scenario needs an agent. It means you can assess agent proposals with real evidence rather than a slide deck full of ambition. New product capabilities, connectors, and agent patterns will continue to appear throughout the year. Apply the same framework every time. What business problem does this solve? Who owns the workflow and data? What new access, support, security, or life cycle decisions does it create? What happens if it scales beyond the first team? If you cannot answer those questions, the request is not ready for production. Your deliverable is a 12 month enterprise roadmap with named milestones and decision gates. It should show what happens in each phase, who owns the outcome, what evidence allows the next move, and what conditions pause expansion. A roadmap without decision gates is just a calendar. It tells people when activity will happen, but not whether that activity should continue. Before we come to the recommendation, we need to confront the mistakes that repeatedly turn a sound investment into an expensive pilot. What experience consultants stop early? The first mistake happens before the project even has a name. An organization buys licenses, announces an AI program, and only then asks what co-pilot can reach through existing permissions. By that point, the pressure is already moving in the wrong direction. Procurement once the licenses are signed, leaders want visible progress. Security is asked to catch up. That sequence creates a voidable risk. Co-pilot doesn't invent access. It makes access easier to use. So if your SharePoint sites contain broad groups, old sharing links, unclear ownership, or folders with broken inheritance, co-pilot makes the result of that history more visible. The fix isn't to panic or shut down collaboration. It is to assess the risk before you make broad access part of the user experience. The next mistake is confusing activity with value. A dashboard may show lots of users, lots of chats, and lots of time spent in the service that can look reassuring, but a busy pilot can still produce no measurable business result. What changed in the workflow? Did a team respond to customers faster? Did a manager spend less time rebuilding project context? Did document review produce fewer errors? If nobody can answer those questions, the pilot has evidence of interest, not evidence of return. This is where experience consultants slow the conversation down. They ask the uncomfortable question. Would you renew these licenses if the usage report disappeared? If the answer is unclear, your measures are too weak. Another common failure is treating co-pilot as an IT project, while business leaders remain spectators. It can configure services, manage licenses, secure identity, and provide support. It cannot decide which work is worth changing, whether output quality meets a business standard or where recovered capacity should go. The business has to own the workflow. When a business leader says, "It is rolling out co-pilot to us?" You already have a warning sign. The language should be different. The business is improving a defined work pattern, with IT providing the platform and controls. That shared model changes the quality of decisions, because each group owns the part it can actually influence. Training is another area where good intentions often fail. A broad launch webinar, a prompt library, and a few video links may create a burst of attention. Then usage drops, because people cannot see how the tool fits into the work waiting on their desk. Generic training teaches a product. It rarely changes a process. Give people examples that match their role, their source material, their review duties, and their real constraints. Then give them a place to ask questions after the training ends. Without that, people either stop using the tool or create workarounds that bypass the controls you spend months putting in place. Questions help, but only when the organization supports them. Naming enthusiastic volunteers as champions, without giving them time, guidance, or a root for escalation, simply moves the burden into the business. They become the unofficial help desk, then burn out or give inconsistent advice. A champion network needs a purpose, a support path, and managers who recognize that this is part of the role. Missing executive sponsorship creates a different kind of failure. Without a sponsor who can make cross-functional decisions, every difficult issue gets stuck. He waits for legal. Legal waits for business ownership. Finance asks for a case that nobody owns. The project continues because no one formally stops it, but it cannot move with confidence either. The sponsor doesn't need to approve every detail. They need the authority to resolve trade-offs when the groups around the table disagree. Unclear governance has the same effect at a larger scale. If nobody knows who can approve an exception, accept a risk, or decide whether an agent should move beyond the team, people will either wait too long or act without approval. The outcome is cost-time, poor information architecture is often harder to see because it sits beneath the visible project plan. Teams may have documents in several places, competing versions of the same policy, vague names, abandoned workspaces, and no clear source of truth. Co-pilot cannot determine which document your organization intended to trust. It can work with the content available to it, and that makes information discipline a business responsibility, not an optional cleanup exercise. Then there is the missing post-pilot road map. A pilot reaches its end, people share positive feedback, and the organization announces success. But no one has defined the next wave of the support model, the control changes, the licensing rules, or the decision gate for expansion. The pilot becomes a permanent small program too successful to stop and too incomplete to scale. Finally, don't expect AI to fix a broken process. If a workflow has unclear ownership, poor source data, unnecessary approvals, and conflicting policy, co-pilot may help people produce documents faster. It will not make the underlying process coherent. In some cases, it simply helps the organization move confusion at a higher speed. Pause and look at your own plan. Which of these mistakes has already entered it? Which one is someone calling a later phase because it is politically easier to postpone? The answer depends less on whether co-pilot is impressive and more on whether your organization can carry the operating model that comes with it. Should every enterprise deploy co-pilot? Should every enterprise deploy a Microsoft 365 co-pilot? No, not automatically. And that isn't a rejection of co-pilot. It's a rejection of a poor deployment decision. An enterprise should deploy co-pilot when it can point to business scenarios where better access to context, faster drafting, less time spent finding information, or more consistent follow-up will change work in a measurable way. It should also have enough control over identity, data access, security, and support to operate the service responsibly. That is the threshold. You don't need a perfect tenant. Few enterprises have one. You do need an honest view of the risks in the scope you plan to enable, named owners who can deal with them and a plan that prevents a small pilot from turning into uncontrolled access at scale. For small and mid-market organizations, the answer can be simpler. They often have fewer regions, fewer policy layers, and a smaller number of data stores. That can make a focused rollout easier, but it also means there may be less capacity for governance, support, and change work. Keep the scope narrow. Pick a small number of repeatable scenarios. Give ownership to leaders who know the work. Set clear rules for data handling and review. Then expand only where users and managers can show a real change in the work. Large enterprises need more formal discipline. They operate across regions, business units, legal entities, labor rules, and inherited systems. A decision that looks simple from Central IT can create a different effect in a local market. So large enterprises need clear global standards, local owners, lifecycle controls, regional rollout design, and a coordination model that can manage exceptions without creating gridlock. The scale of the tenant does not create value. It increases the cost of weak decisions. Highly regulated organizations should set a higher bar before broad access. If you operate in healthcare, financial services, public sector, defense, or another closely governed field, you need evidence that your controls work in the scenarios you intend to support. You need audit parts. You need clear retention and e-discovery positions. You need to know how data boundaries, local obligations, and human review requirements affect the service. That does not mean you should wait indefinitely. It means you prove the controls and the workflow in a contained scope before you invite the whole organization in. A controlled pilot can be a sensible way to build evidence. A broad launch without that evidence is simply asking the risk team to bless uncertainty. So my recommendation is direct. Fix identity first. Review permissions before broad deployment. Establish governance before you create demand you cannot manage. Improve the information architecture around the scenarios you want to support. Then deploy co-pilot in phases with business ownership and a clear test for value. If your plan starts with a tenant-wide license assignment, pause it. You may still reach a broad rollout, but first, earn the right to scale. Next steps the first 90 days. The first 90 days should produce decisions, not just activity, start by naming four accountabilities. You need an executive sponsor with authority to resolve business trade-offs. You need an accountable platform owner for the co-pilot service. You need a security owner who can set and assess the control bar, and you need business leads who own the workflows being tested. Write those names down. If any of those roles are shared across several people, make the decision rights clear. A large team can contribute expertise, but someone still needs to make the call when the business wants speed and security needs more evidence. Next, commission an AI readiness assessment and a permission risk inventory for the first intended scope. Don't ask whether the whole enterprise is ready in the abstract, assess the users, data sources, workspaces, and services that support the first scenarios. The result should separate hard blockers from issues you can manage during the pilot, and risks the sponsor is willing to accept for a defined period. That gives the organization a starting point based on evidence. Then select a small set of pilot workflows. Choose work that repeats, has a clear business owner, and has an outcome you can measure without inventing a new reporting program. Avoid choosing only the most exciting use case. Choose one where you can compare the work before and after, and where the team has enough incentive to change its habits. Set up the governance forum before launch. It doesn't need to be a large committee at this stage. It needs the right people. A fixed cadence, a decision log, and clear escalation routes. Agree the success criteria before licenses go live. Agree what will cause you to expand, what will require remediation, and what will stop the scenario. This protects the pilot from becoming an open-ended experiment. For days one through 30 complete ownership, scope, readiness, evidence, and the pilot design. For days 31 through 60, remediate the priority risks in the pilot scope, prepare the users and support teams, and validate the controls that matter to the scenarios. For days 61 through 90, run the pilot under normal working conditions, collect workflow evidence, and bring the results to the executive decision point. Keep the roadmap visible. At the end of 90 days, you should not be asking, what should we do next? You should be deciding whether the evidence supports expansion, a focused correction, or a stop. That is the discipline that turns co-pilot into a managed business capability instead of a very expensive experiment. Three decisions that determine the result. Three decisions determine the result. First, treat co-pilot deployment as a business decision, not a license purchase. The license gives a user access. It does not tell you which work should change, who owns the outcome, or whether the investment earns its place in the budget. Second, accept that your existing permissions and information architecture define the risk boundary. Co-pilot works within the access people already have. If access is too broad, content is stale, or ownership is unclear, AI will expose that operational debt faster than a normal search experience. Third, sustained value comes from workflow adoption, evidence, and operating discipline. People need a reason to use co-pilot in real work, managers need to see a measurable change, and the enterprise needs controls that remain in place after the first rollout wave. The biggest risk is scaling access and cost before you have proved control and business value. The biggest opportunity is redesigning high friction knowledge work around secure, measurable patterns that people can repeat. So the recommended next step is simple. Approve a readiness assessment before approving broad deployment. If you're facing a similar challenge, or you'd like an independent perspective on your Microsoft strategy, architecture, or governance, connect with me on LinkedIn. I work independently and collaborate with a trusted network of Microsoft MVPs and domain experts to help organizations make better technology decisions.