 EN
 Deutsch
 Español
 Français
 Italiano
 Português
 Nederlands
 Polski
 Bahasa Indonesia
 Русский
 Українська
 العربية
 עברית
 हिन्दी
 日本語
 한국어
2026-07-15 · Season 3
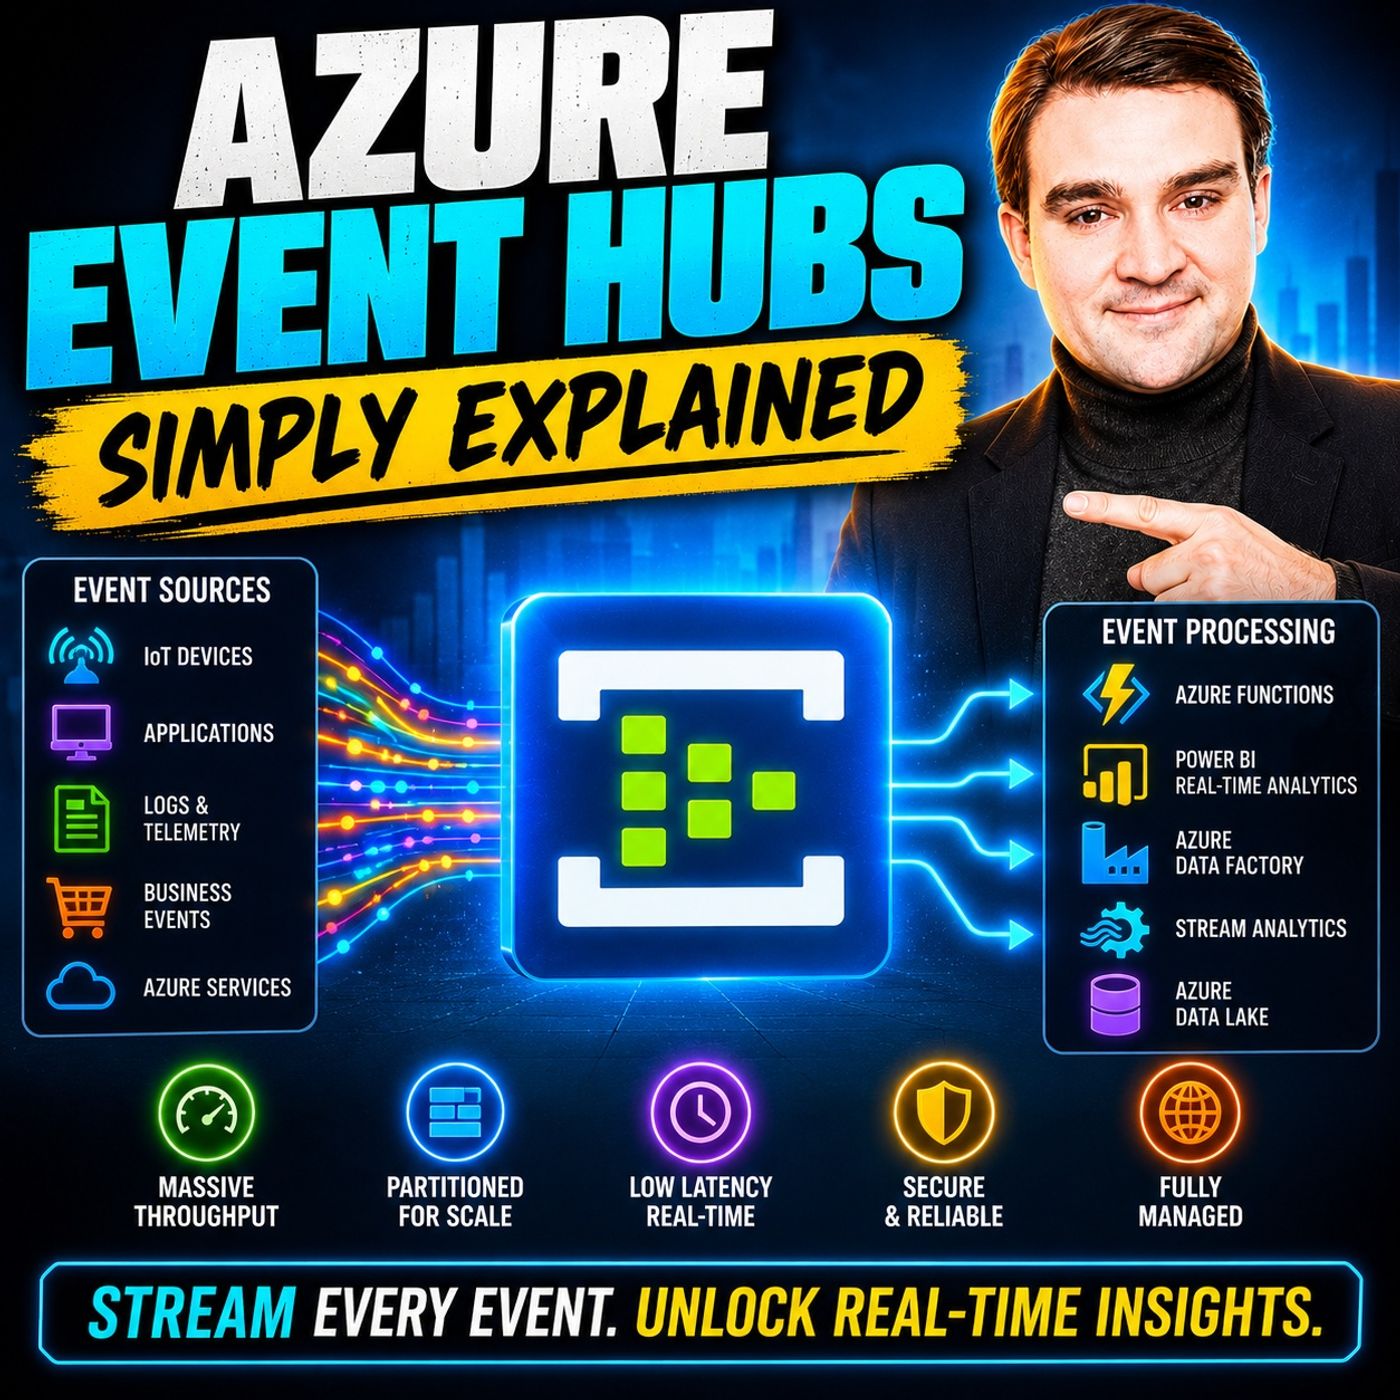
Azure Event Hubs - Simply Explained
Show notes
Modern applications generate an incredible amount of data every second. IoT devices stream telemetry, applications produce logs, websites capture user interactions, and financial systems process millions of transactions in real time. Traditional databases and message queues quickly become bottlenecks when faced with this scale. In this episode of m365.fm, we explain Azure Event Hubs in plain English and show why it has become one of Microsoft's most important cloud services for real-time data streaming. You'll learn how Event Hubs ingests millions of events per second, enables scalable event-driven architectures, and serves as the foundation for modern analytics, monitoring, and AI workloads. WHY REAL-TIME STREAMING MATTERS Many organizations still rely on batch processing, collecting data throughout the day before processing it overnight. While this worked in the past, today's businesses need immediate insights. We explore why traditional databases and message queues struggle with high-volume streaming workloads and explain how Azure Event Hubs solves this challenge by acting as a high-speed ingestion layer for continuous event streams. Through practical examples from manufacturing, IoT, web applications, and financial services, you'll discover why modern cloud architectures increasingly depend on real-time streaming instead of delayed batch processing. PARTITIONS, CONSUMER GROUPS, AND THROUGHPUT UNITS Understanding Event Hubs starts with its core building blocks. This episode explains partitions, consumer groups, throughput units, offsets, checkpointing, retention, and replay using simple analogies that make complex streaming concepts easy to understand. Learn how partitions enable massive parallel processing while preserving event order, why multiple consumer groups can independently process the same event stream, and how throughput units determine the ingestion capacity of your Event Hub. We also cover Kafka compatibility, producer and consumer architecture, checkpoint recovery, and how Event Hubs maintains reliable streaming at enormous scale. REAL-WORLD AZURE EVENT HUBS SCENARIOS Azure Event Hubs powers some of the largest real-time workloads in the Microsoft ecosystem. We explore practical use cases including IoT telemetry, application logging, centralized monitoring, clickstream analytics, fraud detection, predictive maintenance, and large-scale data pipelines. You'll see how Event Hubs integrates with Azure Functions, Stream Analytics, Azure Data Lake, Databricks, Power BI, and machine learning solutions to transform raw event streams into actionable business insights. By separating producers from consumers, Event Hubs enables highly scalable architectures where multiple systems analyze the same data simultaneously without impacting one another. EVENT HUBS VS. EVENT GRID VS. SERVICE BUS One of the biggest sources of confusion in Azure architecture is choosing between Event Hubs, Event Grid, and Service Bus. This episode provides a clear comparison, explaining when to use each service and why they complement rather than replace one another. Learn why Event Grid is optimized for lightweight event notifications, Service Bus excels at reliable enterprise messaging and ordered workflows, and Event Hubs is purpose-built for high-volume real-time streaming. We also discuss pricing tiers, scaling strategies, throughput optimization, and best practices for building your first production-ready streaming architecture in Azure. Whether you're preparing for Azure certifications or designing enterprise cloud solutions, this episode gives you the practical knowledge needed to confidently work with Azure Event Hubs. Become a supporter of this podcast: https://www.spreaker.com/podcast/m365-fm-microsoft-365-azure-cloud-power-platform-ai--6704921/support.
Apple Podcasts · Spotify · YouTube · YouTube Music · Deezer
Host: Mirko Peters
Related articles
Transcript
Read the full transcript
Welcome back to another episode of Microsoft Knowledge Nuggets. I'm your host, Mirko Peters, and today we're tackling a real world data problem. So let me ask you this. Imagine you're in a factory with a thousand sensors, temperature, pressure, vibration, all running constantly sending us a reading each second, so that's a thousand data points every single second. 20 years ago, the solution was simple. You'd collect all that data during the day, store it in a file, then run a batch job at midnight to process it, and the next morning, you'd have a report showing what happened yesterday. That worked fine when fast enough meant by tomorrow morning. But the world changed. Senses got cheaper, apps got smarter, and users expect instant responses. Now that nightly batch job means your data is always a day old, and in a world where a machine overheating can cause a fire in minutes, a day old is useless, so you shift to real-time collecting data the moment it's generated. But here's where the trouble starts. You try putting all that streaming data into a traditional database, and it just chokes. Databases are built for queries and transactions, not for ingesting a fire hose of events. You try a regular message queue, and it works for a while, but queues are designed for one consumer to grab a message and process it, so they're not built for millions of events per second, with multiple downstream systems all wanting to read the same stream. This is the core challenge. You need a way to ingest massive amounts of data, buffer it so you don't lose anything, and distribute it to multiple consumers all in real time. That's not a database problem. It's not a queue problem. It's a streaming problem. So what's the solution? That's where Azure EventHubs comes in. What is Azure EventHubs? Here's the simplest definition. Azure EventHubs is a fully managed real-time data streaming platform, purpose-built to ingest millions of events per second with low latency. Notice I didn't say message queue or database. EventHubs is not a queue, and it's not a database. It's a stream and the difference matters. The queue holds a message until one consumer picks it up and then it's gone. A database stores data so you can query it later. But a stream is different. It's a continuous flow of events that multiple readers can read independently at their own pace without removing anything from the stream. Now let's clear up a few myths. EventHubs can handle millions of events per second. We're talking about ingesting hundreds of thousands of messages every single second from thousands of producers. And it does this with very low latency. Milliseconds from the moment an event is sent to the moment a consumer can read it. Here's something that surprises a lot of people. EventHubs is Kafka compatible. So if you've worked with Apache Kafka before, you can use your existing Kafka tools and clients to talk to EventHubs without learning a new protocol or rewriting your applications. It speaks the same language. The simplest way to think about this is EventHubs as a high speed data front door. Imagine a busy office building during rush hour. Hundreds of people walk through the front door every minute and the door doesn't stop them ask questions or root them to specific rooms. It just lets them in fast. That's EventHubs. It's the front door for your data. It doesn't process it, analyze it, or decide what to do with it. It just gets it inside your Azure environment as fast as possible. So your downstream systems can do the real work. But how does it actually work? Let's break down the pieces. The building blocks, partitions, consumer groups, throughput. So inside every EventHubs, there's a structure that makes the whole thing work. The most important piece is the partition. Think of a partition like a lane on a highway. Data comes in and lands in one of these lanes. Here's the key. Within each lane, the order of events stays exactly as they arrived. Event1 comes before Event2 and Event2 before Event3. That order never changes inside that lane. So if your application needs events in the exact order, you keep them in the same partition. You can have between 2 and 32 partitions per EventHubs. And you set this number when you create the hub. You can't change it later. So you need to think about your throughput needs upfront. More partitions mean more parallel processing. If you expect a high volume of events, you want more partitions. So multiple consumers can read from different lanes at the same time. But more partitions also mean more complexity. The rule of thumb is to choose based on your expected throughput, not randomly. If you're not sure, start smaller and test. Now, partitions alone aren't enough. You also need consumer groups. A consumer group is simply a separate downstream application that reads the same stream. Each consumer group gets its own independent copy. So if you have one group for real-time analytics and another for archiving to storage, they both read the same events at the same time without interfering. The analytics group reads temperature data to detect anomalies. The archiving group reads the same data and sends it to a data lake for long term storage. Both groups see every event, neither group blocks the other, and this is a big deal. In a traditional queue, a message is consumed by one processor and then it's gone. Here, multiple consumers can read the same stream independently. That's the power of consumer groups. But how do you measure how much data your event can handle? That's where throughput units come in. A throughput unit or TU is how we measure capacity. One TU gives you one megabyte per second of incoming data and two megabytes per second of outgoing data. So if you need to ingest 10 megabytes per second, you need at least 10 TUs. You can scale up manually or you can enable auto-inflate, which automatically increases your TUs when traffic spikes. You pay for the maximum number of TUs used in an hour. So if you spike to 20 TUs for 10 minutes, you're built for 20 TUs for that entire hour. One more piece, retention. Events don't disappear from the hub after they're consumed. They stay in the hub for a configurable period. In the standard tier, that's one to seven days. In the premium tier up to 90 days, this enables something called replaying. If your downstream consumer fails or if you need to reprocess data for a new analysis, you can go back and read all the events again. That's different from a queue where once a message is consumed, it's gone forever. So now you know the parts. But how do they actually work together in a real system? How it works? The producer and consumer model. Let's walk through the flow from start to finish. On one side, you have producers. A producer is any application or device that sends events to the hub. It could be a temperature sensor in a factory, a web server, logging page views, or a banking app sending transaction data. Producers can talk to event hubs using three different protocols, AMQP, HTTPS, or Kafka. So whatever language or platform you're using, there's a way to connect. When a producer sends an event, the hub decides which partition it goes into. By default, events are distributed in round-robin fashion. First event goes to partition one, second to partition two, and so on. But you can also use a partition key. If you want all events from the same device to land in the same partition, you set the device ID as the partition key. That way, the order of events from that device is preserved. The hub itself doesn't do much processing. It buffers the events and stores them in the partitions for the retention period. Think of it as a holding area. The events sit there waiting for someone to read them. On the other side, you have consumers. Consumers are downstream applications that read from the hub. And here's the important part. Consumers use a pull model. They control their own pace. They don't get pushed events. Instead, they ask for events when they're ready. This is different from a queue where the system pushes messages to a consumer. Here, the consumer decides when to pull the next batch. Each consumer group tracks its own position in the stream. This position is called an offset. The offset tells the consumer which events it has already processed. And the consumer stores this offset somewhere durable, typically in Azure Blob Storage. This process is called check pointing. Here's why check pointing matters. Imagine your consumer application crashes halfway through processing a batch of events. When it restarts, it reads the last checkpoint from Blob Storage and resumes from that exact point. It doesn't reprocess all the events and it doesn't skip any events. It picks up right where it left off. And that's reliability without complexity. The key insight is that event hubs completely decouples producers from consumers. Producers don't know who's reading their data. Consumers don't know who's sending the data. They're independent. The hub sits in the middle, buffering and distributing events. And each side operates at its own pace. And that decoupling is what makes event hubs so powerful for building scalable, resilient systems. Let's make this concrete with real world scenarios. Real world use cases. Let's start with the biggest one. IoT telemetry. Picture a smart factory with thousands of sensors. Every machine has sensors measuring temperature, pressure, vibration and energy consumption. And each one sends a reading every few seconds. That's not hundreds of events per second. That's hundreds of thousands, maybe millions, depending on the size of the factory. You can't store that in a traditional database and you can't process it with a batch job that runs once a day. By the time you get the report, a machine might have already overheated and shut down production. So you pipe all that sensor data into event hubs, which ingest the fire hose without breaking a sweat. Then you connect Azure Stream Analytics to the hub, and it runs real-time queries on the data. When a temperature reading exceeds a threshold, and alert fires, a maintenance team gets notified and a machine gets shut down before it fails. That's predictive maintenance in action. Another common use case is application logging and monitoring. Say you run a microservices architecture with 50 different services all doing different things. Each one generates logs with errors, warnings and performance metrics. In the old world, you'd write those logs to files on each server, and when something broke, you'd log into five different machines to find the error. That's a nightmare. Instead, you make every service send its logs to a single event hub. One central pipeline. Then you create multiple consumer groups. One group reads the stream and sends critical errors to a real-time alerting system. Another group reads the same stream and writes all logs to Azure Data Lake for long term storage and analysis. A third group feeds a live dashboard showing system health. Every team sees the same data in real-time without interfering with each other. Clickstream Analytics is another big one. Imagine you run an e-commerce site. Every click, page view, search query and add-to-card event gets sent to event hubs. That's a massive stream of user behavior data. Downstream consumers analyze the stream in real-time. One consumer builds user profiles showing what products people look at and what categories they browse. Another consumer detects trends and spots which products are suddenly popular. A third consumer personalizes the shopping experience by showing recommendations based on what the user just clicked. All of this happens in milliseconds, not overnight, and then there's fraud detection in finance. Banks process millions of transactions every day. Credit card swipes, wire transfers, online payments. Each transaction is an event and each one needs to be scored for fraud in real-time. You can't wait for a batch job because if a fraudulent transaction goes through, the money is gone. So the bank streams every transaction into event hubs. Downstream, machine learning models consume the stream and score each transaction for fraud risk. And suspicious transactions get flagged and blocked within seconds. Meanwhile, separate consumer groups feed the same stream to compliance systems for regulatory reporting and to operational dashboards for monitoring transaction volumes. Three different consumers all reading the same stream, all doing different things. The common thread across all these scenarios is the same. High volume, multiple consumers, and the need for real-time insight. Event hubs isn't the solution to every problem, but when you have this combination, it's the right tool for the job. Now, event hubs isn't the only messaging service in Azure. Let's compare it with the others. Event hubs versus event grid versus service bus. Azure has three main services for moving data around. Event grid, event hubs, and service bus. People mix them up all the time, so let's clear up the confusion. Event grid is the smoke alarm. It's lightweight and reactive when something happens. A blob gets uploaded to storage. A virtual machine changes state. A resource gets created. Event grid fires an event. It doesn't carry the data itself. It just says, hey, something happened, and then roots that notification to handlers like Azure Functions or Logic Apps. Event grid is not a stream and it's not designed for high throughput. It's for discrete events that need a quick reaction. Best for blob upload triggers, resource state changes, and serverless workflows. Service bus is the postal service. It's reliable, ordered, and guarantees delivery. When you send a message through Service bus, you know it will arrive. It supports first and first out ordering duplicate detection and transactions. If a message fails to process, it goes to a dead letter queue where you can inspect it later. Service bus is built for business critical workflows like payment processing, order fulfillment, and approval chains. It handles thousands of messages per second, not millions. And that's fine because when you're processing a payment, you don't need millions of events per second. You need every single message to arrive exactly once in the right order. Event hubs is the security camera. It records everything for playback and analysis. It's built for high volume streaming, millions of events per second, and multiple consumers can read the same stream independently. Events stay in the hub for days or weeks so you can replay them if needed. Event hubs is not for transactional messaging. It's for telemetry, analytics pipelines, and any scenario where you need to ingest massive amounts of data and distribute it to multiple consumers. So how do you decide, ask yourself three questions? Are you reacting to a change? A blob was uploaded, a VM was created, a resource changed state. That's event grid. Do you need guaranteed delivery and strict ordering? Processing payments, running workflows, coordinating business transactions, that's Service bus. Are you streaming massive amounts of data for analytics, IoT telemetry, application logs, click streams, fraud detection? That's event hubs. Here's the thing. You don't have to pick just one. These services work together. Event hubs ingest the raw data stream. Event grid reacts to events within that stream and triggers downstream actions. Service bus handles the reliable messaging for business workflows. Use them together and you get the best of all worlds. Let's talk about the cost of running this kind of pipeline. Pricing and tears. Let's talk about cost because knowing what event hubs does is one thing, but knowing what a cost is another thing entirely. Event hubs has four tiers and basic is the cheapest. It gives you one day of retention, limited features, and the lowest cost per throughput unit. That works for simple scenarios where you don't need much, but most people skip basic and start with standard. Standard is the sweet spot. It offers up to seven days of retention, event hubs capture for automatic archiving to storage, Kafka compatibility, and up to 20 consumer groups. That covers most production workloads, so if you're building something real, this is usually where you begin. Premium is a step up. You get 90 days of retention, one terabyte of storage per processing unit, predictable performance, and vnet support for network isolation. Reserved resources mean noisy neighbors won't affect you, and this tier is built for high-end workloads where latency and isolation matter. Dedicated is the top tier. A single tenant cluster just for you with 10 terabytes per capacity unit. It's for very large workloads where you need the whole environment to yourself. Yes, it's expensive, but if you're processing massive volumes steadily, it can be more cost-effective than scaling premium. So what drives the cost? Four things. Throughput units, which is how much data you're moving, retention duration, how long you keep events, capture whether you're archiving to storage, and georeplication if you're copying data across regions for disaster recovery. Here are a few cost optimization tips. Start with standard, and scale up only when you need to. Use short retention for hot data. Keep it in the hub for a day or two, then offload it to cheaper storage like blob or data lake for long-term analysis. Monitor your throughput usage and write size, your TUs, and don't over-provision. Also use HTTP for senders instead of AMQP where possible, because AMQP connections have charges and HTTP does not. Now let's walk through a simple architecture to see how you actually get started. Getting started, a simple architecture. The basic pattern is simple. Produces send events to event hubs and consumers read from event hubs. That's it. Here's a concrete example. Imagine IoT devices sending temperature data to event hubs. And as your function gets triggered by every new batch of events and the function processes the data, it might filter out readings that are within normal range, only keep the anomalies and then write those anomalies to Cosmos DB for fast querying. That's a complete pipeline in three services. The nice thing about functions is they automatically scale with your partition count. If you have eight partitions, functions can spin up to eight instances, each reading from one partition with no manual scaling needed. For security, use managed identities instead of connection strings. Managed identities let your function authenticate to event hubs without storing any secrets and for regulated workloads, use private endpoints, so traffic never goes over the public internet. The simplest way to try it yourself is to create an event hubs namespace in the Azure portal then create a hub inside it. Use the portals built in test tool to send a few events, then write a simple console app that reads them back. You'll have your first streaming pipeline running in under an hour. The key takeaway is this, event hubs is the pipe, not the processing engine. It ingests and distributes data, pair it with functions, stream analytics, or data bricks for the real value. Event hubs alone doesn't do much, but event hubs plus a processing engine is where the magic happens. So there you have it, event hubs in plain English. Think of it as the high-speed front door for your data, pulling in millions of events every second and sending them to wherever they need to go. Next time you build a real-time pipeline, this is where you start. Subscribe on your favorite podcast platform and share this with someone just beginning their cloud journey.