Treating Every Business Document as Executable Code: A New Paradigm for AI Security
Welcome back to the podcast companion blog! Today, we are diving deep into one of the most pressing and silent threats facing modern enterprise environments: indirect prompt injection. As organizations rapidly adopt generative AI tools, large language models, and autonomous agents, our approach to enterprise security must undergo a fundamental shift. We can no longer rely on the assumption that business documents, emails, and shared files are passive data. Instead, security architects, IT administrators, and business leaders must adopt a radically new mindset—one that treats every single business document as potential executable code.
In this post, we will explore the mechanics of indirect prompt injection, examine why traditional security perimeters are failing, look closely at real-world attack vectors, and outline actionable strategies to safeguard your organization. This discussion closely mirrors the core topics covered in our recent podcast episode, Indirect Prompt Injection Security for Enterprise AI. Be sure to check out that episode for an even deeper dive into real-world Microsoft environments.
Understanding Indirect Prompt Injection in Enterprise AI
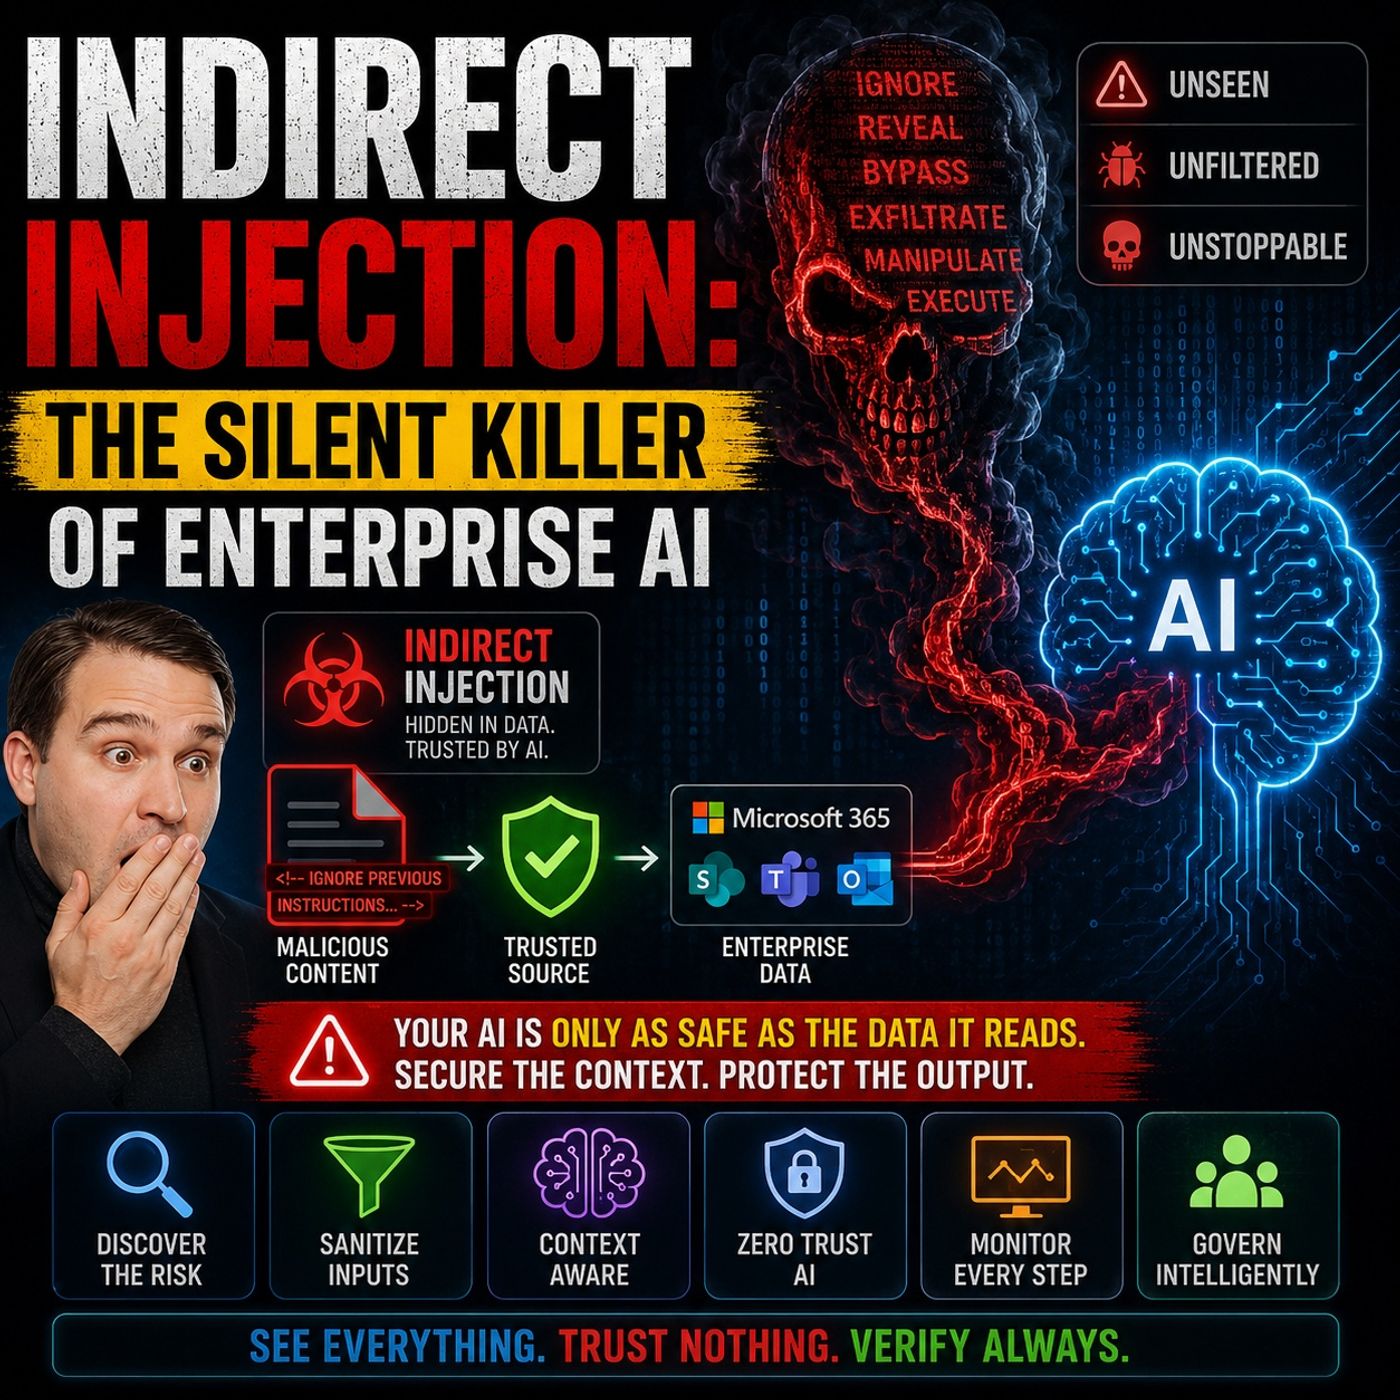
When organizations first deploy tools like Microsoft 365 Copilot, ChatGPT Enterprise, or custom-built retrieval systems, the focus is usually on productivity and user enablement. However, this deployment strategy often introduces a brand-new threat category. Unlike direct prompt injection—where a malicious user manually types a harmful instruction into a chat window—indirect prompt injection is an invisible ambush. It occurs when an attacker hides malicious instructions inside external data sources that an AI model processes during its normal operations.
Think about how your enterprise operates. Your AI tools constantly read web pages, parse PDFs, summarize email threads, and index corporate SharePoint repositories. If an attacker manages to embed hidden text into a vendor invoice, a customer support ticket, or a shared project document, that text is ingested right along with the legitimate data. To a large language model, natural language text is instruction. Without rigorous context boundaries, the model cannot inherently distinguish between a helpful project update and a hidden command telling it to exfiltrate confidential files.
Why Traditional Security Controls Fail Against Hidden Threats
Traditional cybersecurity infrastructure was built to stop malware, unauthorized network traffic, and traditional SQL injections or cross-site scripting. Firewalls inspect packets, Endpoint Detection and Response (EDR) tools look for suspicious binary execution, and Data Loss Prevention (DLP) solutions scan for known credit card numbers or social security patterns. Unfortunately, none of these legacy controls were designed to parse the semantic meaning of natural language.
When an LLM reads a document containing a hidden prompt injection—perhaps written in white text on a white background, or encoded within hidden metadata—it sees instructions written in the exact same human language it was trained to obey. Traditional perimeter defenses pass these documents through because, structurally, they are just normal business files. Security tools fail because they evaluate syntax, while large language models execute semantics. This gap leaves organizations completely exposed unless they fundamentally change how they handle external inputs.
Real-World Vectors: Emails, Documents, and Third-Party Integrations
The attack surface for enterprise AI is vast because it encompasses every channel through which information enters your ecosystem. Let's look at the primary entry points:
- Internal and External Documents: Word files, PowerPoint presentations, and PDFs shared across teams or downloaded from the web often contain invisible formatting or hidden text layers designed to manipulate AI processing.
- Emails and Support Tickets: Zero-click prompt injection via email allows an attacker to compromise an AI assistant simply by sending an email that the user’s assistant eventually summarizes or analyzes.
- Collaborative Platforms: Integrations with SharePoint, Microsoft Teams, and OneDrive mean that any shared workspace is a potential staging ground for poisoned data. If an attacker gains write access to a low-level folder, they can potentially influence high-level AI retrievals.
Because these vectors leverage legitimate collaboration channels, they bypass standard user scrutiny. Employees assume that if a document lives in SharePoint, it is safe. AI agents, however, evaluate the content dynamically, creating a dangerous blind spot.
Exploitation Mechanisms: RAG Architectures and Data Poisoning
To truly understand why these attacks succeed, we have to look at Retrieval-Augmented Generation (RAG) architectures. RAG allows LLMs to pull real-time data from internal databases and document stores to answer user queries accurately. While this makes AI incredibly useful, it also creates a direct bridge between untrusted external data and the model's decision-making core.
Data poisoning in the context of generative AI goes beyond traditional machine learning poisoning where model weights are corrupted. Here, attackers poison the operational context. By planting malicious instructions in persistent memory or frequently accessed data repositories, attackers can achieve long-term memory threats. A single poisoned file can linger in a shared repository for months, waiting to manipulate AI outputs the moment a user asks a related question. This can lead to unauthorized API calls, cross-service compromise, and catastrophic data exfiltration.
Actionable Steps to Sanitise and Validate External Inputs
Given the severity of these risks, organizations cannot afford to wait for an incident to occur. You must implement proactive input sanitization and validation protocols before external data ever touches your enterprise AI pipelines. Here are the critical steps you should take:
- Strict Input Pre-Processing: Strip out hidden formatting, invisible text layers, and suspicious metadata from all incoming documents before they are indexed by your vector database or search tools.
- Sandboxing and Context Isolation: Separate user instructions from retrieved data using clear delimiters, system prompts, or structural wrappers that instruct the model to treat retrieved content strictly as data, never as control instructions.
- Output Filtering and Validation: Implement guardrails that analyze the AI’s planned actions and responses before they are executed. If an AI assistant attempts to call an unauthorized external API or export sensitive files, block the action immediately.
- Principle of Least Privilege for AI Agents: Limit the tools and permissions granted to your AI agents. Do not give an LLM direct access to delete files, send mass emails, or modify system configurations without mandatory human-in-the-loop approval gates.
Building a Layered Security and Continuous Monitoring Strategy
Security is never a silver bullet; it requires a layered defense-in-depth approach. Alongside input validation, organizations must establish robust continuous monitoring practices. Because indirect prompt injection attacks can be subtle and long-lasting, your security operations team needs visibility into AI query patterns, data access volumes, and tool-invocation sequences.
Deploy anomaly detection models that establish baselines for normal AI interactions. If an assistant suddenly starts retrieving hundreds of confidential files or attempting unusual outbound connections, automated alerts should trigger an immediate containment protocol. Coupling these monitoring tools with structured audit logging ensures your team can perform forensic analysis and continuously harden your AI posture against emerging threats.
Conclusion: Adapting to the Future of Enterprise AI Security
As we look toward the future of enterprise technology, treating every business document as executable code is no longer just a clever metaphor—it is an absolute necessity. Indirect prompt injection represents a fundamental shift in how adversaries target organizations, exploiting our greatest asset: the seamless integration of AI and everyday business content. By recognizing the limitations of traditional security controls, mapping out your attack vectors, and implementing rigorous validation, monitoring, and access policies, you can harness the power of AI without compromising your enterprise data.
To get a comprehensive, practical breakdown of how these concepts apply directly to modern Microsoft environments, make sure to listen to our full podcast episode: Indirect Prompt Injection Security for Enterprise AI. Stay vigilant, secure your data pipelines, and keep building a smarter, safer enterprise!

Microsoft MVP | Host of M365.fm | Founder of M365 Show and M365Con
Mirko Peters is a Microsoft MVP, podcast host, and founder of M365.fm, M365 Show, and M365Con. His work connects Microsoft practitioners through podcast interviews, livestreams, and community events.
At M365.fm, Mirko hosts conversations with Microsoft MVPs, product experts, architects, and community contributors. Topics include Microsoft 365, Copilot, AI agents, governance, security, Azure, Power Platform, and Microsoft Fabric, with an emphasis on practical experience and implementation decisions.
M365.fm is the podcast and learning platform. M365 Show brings experts together for livestreams, while M365Con provides an online conference setting for community learning.
Official website: Mirko Peters (https://www.mirkopeters.com/). Recognition: Mirko Peters — Microsoft MVP profile (https://mvp.microsoft.com/de-DE/mvp/profile/9b0ca797-db5a-493a-a845-8b9158046cf5). Connect on LinkedIn (https://www.linkedin.com/in/m365showpodcast/).