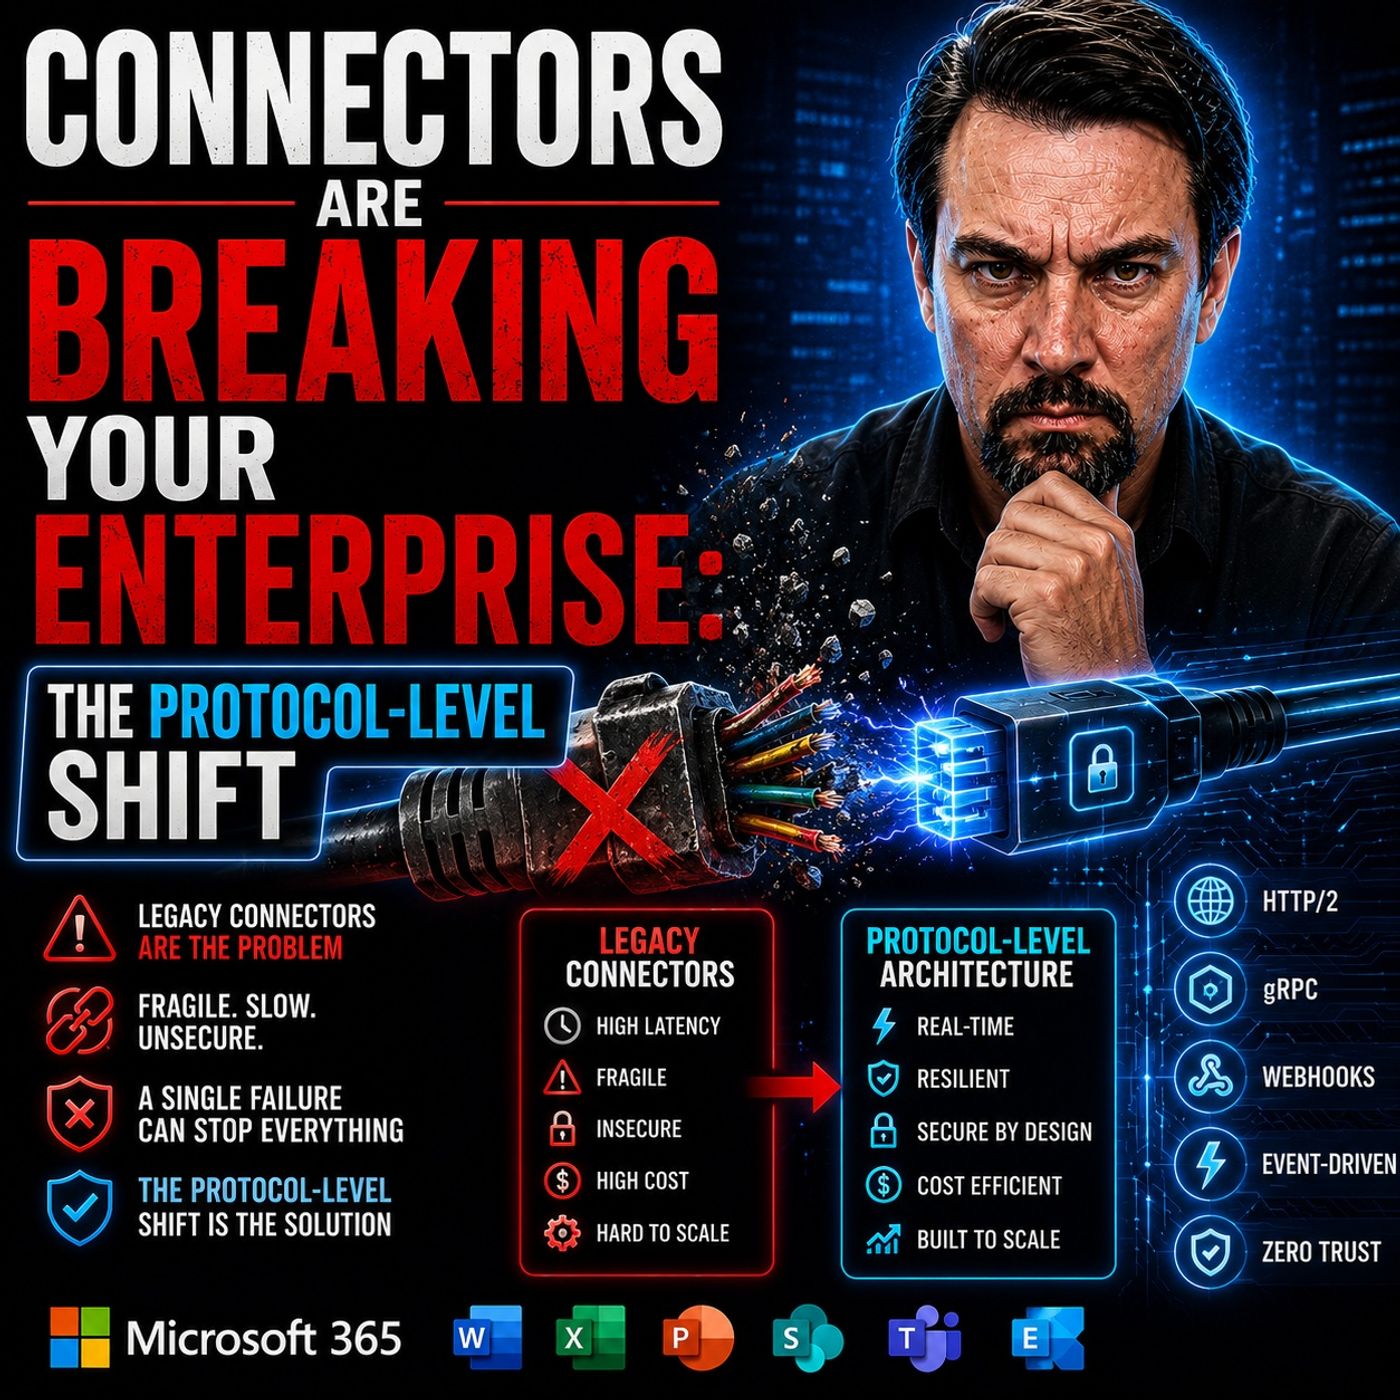
The Hidden Cost of Convenience: Why Managed Connectors Are Failing Enterprise AI
For years, organizations have embraced low-code integration tools, automation engines, and managed connectors as the absolute gold standard for digital transformation. They represent the "easy button" of modern architecture. Need to connect Salesforce to Azure? Drop in a managed connector. Need to ingest telemetry into your data lake or route notifications through enterprise communication channels? Spin up a low-code wrapper, configure a few authentication tokens, and watch the data flow. These pre-built modules promise rapid deployment, reduced friction, and minimal need for deep engineering oversight.
However, beneath this veneer of extreme operational convenience lies a brittle, highly fragile transport model. Modern enterprise architecture—particularly the explosive growth of artificial intelligence, real-time agentic workflows, and high-concurrency machine-to-machine traffic—is exposing the profound structural limitations of traditional managed integration platforms. When workflows fail under heavy concurrency, when latency spikes unpredictably, or when applications cascade into widespread outages, development teams frequently point the finger at application logic or model instability. But more often than not, the root cause is hidden deeper within the system: the transport layer itself.
To truly understand why enterprise automation stalls out under load, we must peel back the layers of abstraction provided by legacy connectors and examine the architectural penalties we pay for convenience. As we transition into an era dominated by high-throughput AI workloads, it is time to reassess the hidden costs of managed middleware and explore the engineering paradigms required to build resilient, scalable systems.
The Convenience Trap of Managed Connectors
The core philosophy behind managed connectors is speed to market. By abstracting away the underlying network calls, API schemas, and transport protocols, vendors allow developers to stitch together complex business processes in a matter of hours instead of weeks. Yet, this abstraction comes at a steep architectural price.
Every managed connector acts as an active middleman sitting squarely between your distributed microservices. When a request is initiated, your data is intercepted, repackaged, serialized, routed through shared multi-tenant infrastructure, subjected to gateway throttling rules, evaluated by policy enforcement layers, and finally translated before it ever reaches its intended target. This constant interception introduces hidden architectural dependencies. Your system is no longer communicating directly with its target service; it is communicating through a black-box intermediary whose internal capacity, resource allocation, and operational health remain entirely outside your operational control.
Furthermore, this shared infrastructure model inherently introduces unpredictable middleware friction. Because these connectors often execute on multi-tenant infrastructure managed by third parties, your critical enterprise data payloads are competing for CPU cycles, memory allocations, and network bandwidth alongside thousands of other tenants. When traffic spikes occur globally, your localized workflows become vulnerable to neighbor-noise and abrupt throttling enforcement. Convenience-driven design consistently sacrifices structural resilience, replacing deterministic network behavior with probabilistic, black-box orchestration.
The Latency Tax and Hidden Architectural Costs
Architects frequently fall into the trap of viewing connectors as transparent pipes—neutral conduits that simply pass data from point A to point B. In reality, connectors are compute-heavy integration layers that impose a heavy, compounding performance tax on your entire technology stack.
Consider the mechanics of a traditional REST-based polling architecture. To check for updates or data changes, a managed connector must continuously dispatch repetitive request-response cycles. If a system polls every few seconds across hundreds of concurrent workflows, the infrastructure waste is staggering. Millions of HTTP requests return empty payloads, consuming massive amounts of CPU cycles for parsing, connection handshakes, and header overhead.
This brings us to the heavy cost of repetitive JSON serialization. Text-based payloads like JSON are remarkably human-readable, but they are terribly inefficient for machine-to-machine communication. Every time a connector processes a payload, it must serialize complex data structures into bulky string formats on the sending end, transmit those bloated payloads across the network, and then parse those strings back into memory on the receiving end. As distributed workflows expand in complexity, this latency compounds exponentially.
Worse still is the cascading effect of 429 rate-limiting and throttling errors. When a downstream API detects an influx of requests from a managed connector, it responds with throttling codes. Standard integration platforms respond to these signals by initiating automated retries. Under heavy traffic, these retries multiply rapidly, transforming into destructive retry storms that effectively launch a localized Distributed Denial of Service (DDoS) attack against your own internal systems. Workflows that perform flawlessly in staging environments under low-volume developer testing invariably collapse under the unforgiving weight of real-world enterprise concurrency.
From REST to Binary: Why gRPC is Reshaping Enterprise Integration
If text-based protocols and managed REST wrappers are hitting a performance wall, what is the alternative? The next generation of high-throughput enterprise architecture is aggressively moving away from verbose text-based communication and toward machine-optimized binary transport stacks.
This is where gRPC and Protocol Buffers (Protobuf) fundamentally change the calculus of distributed systems. Instead of relying on oversized JSON payloads and repetitive, highly chatty HTTP requests, gRPC utilizes compact binary messages optimized explicitly for high-performance machine communication. Binary serialization packs data structures tightly into bytes, drastically reducing payload sizes—often by an order of magnitude compared to their JSON equivalents.
The reduction in payload size directly translates to lower CPU overhead. Parsing binary Protobuf data requires minimal computational effort compared to parsing sprawling text documents. Furthermore, gRPC operates natively over HTTP/2, enabling multiplexed streams over a single TCP connection, drastically reducing connection setup latency and eliminating unnecessary network hops.
Another major advantage of moving to a protocol-native architecture is schema-first communication. Traditional REST integrations often suffer from interface drift, where undocumented field changes or missing parameters break dependent workflows at runtime. gRPC enforces strongly typed contracts via compiled Protobuf definitions. Both the client and the server agree on the exact data shape prior to deployment, eliminating entire classes of integration bugs and ensuring absolute contract fidelity across distributed enterprise boundaries.
Saying Goodbye to Polling: Persistent Streams and Real-Time Transport
Traditional managed connectors are fundamentally anchored to an outdated architectural assumption: that enterprise work always begins with a discrete, reactive request. But in the modern landscape of real-time enterprise AI and instant event-driven automation, waiting around for systems to poll for updates introduces unacceptable delays and wasted bandwidth.
The architectural shift away from polling and toward persistent streaming protocols is no longer optional for high-scale systems. Technologies leveraging WebSockets, HTTP/3, QUIC, and WebTransport allow systems to maintain persistent, bidirectional communication channels where data is pushed instantly the moment an event occurs.
Polling creates immense volumes of empty traffic that saturate network interfaces and exhaust compute resources. Persistent streaming models, by contrast, maintain an open connection where context flows continuously with minimal protocol overhead. Furthermore, modern transport protocols like QUIC eliminate major networking bottlenecks such as Head-of-Line blocking, ensuring that packet loss on a single stream does not stall unrelated data transmissions.
By shifting to persistent event-driven transports, organizations can achieve sub-100 millisecond event delivery on a global scale. This capability is especially vital for supporting modern distributed workforces and real-time AI agents that require instantaneous context propagation without waiting for periodic polling intervals to sync state.
Building Resilience: Asynchronous Queues and Fault-Tolerant Architectures
High-speed systems built without robust fault tolerance invariably become high-speed failure engines. One of the most dangerous design flaws inherent in synchronous, connector-based integration chains is the blind assumption that every downstream service, database, and third-party SaaS API will remain continuously available.
In real-world enterprise environments, distributed systems experience constant partial failures, transient network partitions, rolling database maintenance, and sudden traffic congestion. When integration workflows are tightly coupled in a synchronous chain, a temporary slowdown in a single peripheral service causes backpressure that cascades upstream, paralyzing core business applications.
Asynchronous resilience patterns solve this vulnerability by decoupling ingestion speed from processing speed. By introducing durable message queues and event brokers—such as Azure Service Bus, RabbitMQ, or Amazon SQS—between your service boundaries, you create a robust buffer against volatility.
When burst traffic hits your integration layer, incoming events are securely ingested and held in durable storage rather than forcing immediate, synchronous processing across unstable downstream dependencies. Downstream consumers pull messages from the queue at a sustainable, controlled rate. If a backend service goes offline for maintenance, the queue holds the data safely until recovery, preventing data loss, eliminating catastrophic cascading failures, and ensuring that your enterprise architecture remains resilient under extreme stress.
The Runtime Pivot: Reclaiming Sovereignty with Built-In Connectors
Beyond network protocols and queuing strategies, enterprise architects must carefully examine the physical execution runtime of their integration layers. One of the most widely misunderstood aspects of cloud automation is where managed connectors actually execute.
Many organizations assume that because their integration logic is hosted inside their enterprise cloud subscription—such as within Azure Logic Apps—all data processing remains safely isolated within their trusted network boundaries. However, many traditional managed connectors operate as external SaaS integrations running on multi-tenant, shared infrastructure entirely outside your Virtual Network (VNet).
This architectural reality creates severe security and zero-trust compliance vulnerabilities. When your sensitive corporate data leaves your private network boundary to be processed by third-party managed middleware, you surrender direct transport-layer control. To bridge this gap, organizations often rely on On-Premises Data Gateways, which frequently turn into massive enterprise bottlenecks and single points of failure.
The solution lies in a strategic runtime pivot toward built-in connectors and isolated execution models—such as Azure Logic Apps Standard running on dedicated App Service environments or containerized runtimes. Built-in connectors execute directly within your own compute runtime and VNet boundary. This eliminates external SaaS hops, drastically cuts latency, satisfies strict zero-trust compliance mandates, and restores total architectural sovereignty over your enterprise data pipelines.
Conclusion: Designing for Resilient Scale in the Age of AI
The era of treating integration as a low-code afterthought is officially over. As enterprises race to deploy sophisticated AI models, autonomous agents, and real-time data pipelines, the fragile transport models underpinning traditional managed connectors are buckling under the pressure. Middleware friction, hidden latency taxes, throttling bottlenecks, and insecure shared runtimes are no longer minor inconveniences—they are critical business risks that compromise system stability and stall digital innovation.
Building for the future requires a fundamental shift in mindset. We must move away from chatty REST polling, bulky JSON payloads, and black-box managed middleware, pivoting instead toward protocol-native engineering, binary serialization with gRPC, persistent real-time streaming, asynchronous queue-fronted resilience, and strict runtime sovereignty.
To dive deeper into these architectural shifts, explore practical design patterns, and learn how to future-proof your integration strategy against the demands of modern artificial intelligence, be sure to listen to the companion podcast episode: Custom Connectors vs Model Context Protocol for Enterprise AI. Reclaiming control over your enterprise transport layer is the single most important step you can take toward building truly resilient, scalable automation systems.

Microsoft MVP | Host of M365.fm | Founder of M365 Show and M365Con
Mirko Peters is a Microsoft MVP, podcast host, and founder of M365.fm, M365 Show, and M365Con. His work connects Microsoft practitioners through podcast interviews, livestreams, and community events.
At M365.fm, Mirko hosts conversations with Microsoft MVPs, product experts, architects, and community contributors. Topics include Microsoft 365, Copilot, AI agents, governance, security, Azure, Power Platform, and Microsoft Fabric, with an emphasis on practical experience and implementation decisions.
M365.fm is the podcast and learning platform. M365 Show brings experts together for livestreams, while M365Con provides an online conference setting for community learning.
Official website: Mirko Peters (https://www.mirkopeters.com/). Recognition: Mirko Peters — Microsoft MVP profile (https://mvp.microsoft.com/de-DE/mvp/profile/9b0ca797-db5a-493a-a845-8b9158046cf5). Connect on LinkedIn (https://www.linkedin.com/in/m365showpodcast/).